The curl project has decided to alter its vulnerability disclosure program procedure and starting October 26 2026, we insist that all vulnerability reports submitted to us that are deemed to be severity LOW or MEDIUM should instead be submitted as issues in our GitHub repository.
Only vulnerabilities deemed to be HIGH or CRITICAL will be kept private in the HackerOne tracker.
Security researchers in doubt can still submit the issue on HackerOne and we can tell them what severity we deem it to be. Over the last few years, over 90% of all submissions could quickly be assessed to be less than HIGH.
Issues submitted to HackerOne we deem are LOW or MEDIUM will be requested to be resubmitted on GitHub and will be closed as informative on HackerOne (and publicly disclosed).
Avalanche survival tricks
This policy change is entirely triggered by the current avalanche of vulnerability reports that keep pouring in. We see no end to them and we do not anticipate this flood to decrease within the next several months.
We are struggling as a project as all key maintainers feel strained, overloaded and brought to the brink of what we can muster. We must act to survive. This is our next step in a survival strategy. It might not be our last. We aim to not drown.
Public vs private
By opening up the process we allow the whole world to participate. Both in the assessment and understanding of the report and claimed vulnerability, but also in the creating and writing the advisory and figuring out details of when the issues was introduced etc.
Ideally we get better help to make sure the fix is the correct one, that it fixes the problem, and any other related problem that is similar and that it does not miss a related problem sitting next to this.
An obvious recent trend is that the moment we announce a new set of CVEs and their associated fixes, there is an army of AI-using researchers who throw all those at their models and harnesses to find similar mistakes or omissions in the fixes. By taking this process to the public all the way, ideally we get more help to do that scrutiny better before we ship releases.
We recognize that the amount of work needed per received vulnerability report does not shrink by doing them in public, but we think that we might share the burden among more people easier, and we hope that lessons and documentation brought up in these discussions will be easier to spot and learn from.
The open process can also allow distros and other users of curl to keep up with security fixes earlier and better.
The risks
Several people have suggested there is a risk that researchers mistakenly submit severity HIGH issues on GitHub thinking they are LOW or MEDIUM. It is basically unheard of that a researcher would have understated a reported problem so I consider that a low risk scenario. Also: there was already before this a risk that someone would submit a vulnerability report in the public, it is not a new risk.
Handling some vulnerabilities in the public of course makes the immediately available for both good and bad people. This policy will give bad people a slightly longer window of opportunity to exploit weaknesses at the expense of existing curl users. That is unfortunate but we see no way of avoiding this. We limit this practice to less than HIGH for this reason: at least these problems are not terrible.
Severity LOW
We have discussed simply dismissing all severity LOW issues, but within the CVE program there is an appeals process and if we don’t hand out a CVE to an actual vulnerability, then someone else will do it. We thus cannot ignore true vulnerabilities, or they will come back to bite us nonetheless.
We can however resist and refuse silliness and I personally aim to deny and decline more vulnerabilities harder on the basis that they do not actually hurt any users or existing applications.
Crazy combos
A clear trend these days is that many newly reported vulnerabilities are figured out by AI models that create crazy sequences or option combinations that do something unexpected, but the sequence is something that aren’t likely to ever be used in the real world, or the unexpected that happens is something that occurs every time so applications doing this would spot the problem immediately. I.e problems that have almost no risk to actually trigger in the real world. We save no users by insisting on doing the CVE dance for those issues. We only get work for ourselves and a whole world that has to act on them.
Flow control it
There is an almost infinite number of combinations you can use libcurl’s many options, protocol mixes and flexible API to do things that might not be clearly documented and the AIs will continue to try them all and together with the humans driving these checks they are super eager to treat every minor discrepancy as a vulnerability. We can’t continue down this spiraling path with our sanity intact.
We don’t have the bandwidth, manpower or even will to handle a never-ending vulnerability reporting stream at this pace. I believe few software projects can stand this kind of prolonged high volume deluge for extended periods. Something needs to give way.
How to assign severity
We only use these for levels in the curl project: LOW, MEDIUM, HIGH and CRITICAL. Often we refer back to recently managed vulnerabilities to see how we judged them, but we also provide a set of basic guidelines. I’m sure we can also make them better and clearer.
In the curl 8.23.0 release we shipped a fix for one of the worst vulnerabilities in curl in a long time. We grade it severity HIGH. It is known as CVE-2026-92392 with the title HTTP/2 upload Use-After-Free.
This post explains the bug, what the problem can lead to, and something about why it happened and what we have done to make it harder to introduce a problem like this in curl again in the future.
This is a much simplified explanation. Please refer to the original report for all the details and the full reproducible Docker image for all the low-level fun and education you could possibly want. I highly recommend doing that; the report and the reproducible are awesome.
Use-After-Free
It is a use-after-free, which is a classic problem in memory-unsafe programming languages, like C, where we erroneously have a lingering pointer left, pointing to memory that is already freed, and yet we use that pointer and the memory it points to.
This family of errors is especially bad when a malicious actor can affect the content that gets stored into that memory area that is still used even though it was freed. Tricking the program to do something unintended.
HTTP/2 is multiplexed
This problem involves HTTP/2. HTTP/2 is a multiplexed protocol, meaning that it handles multiple logical transfers over the same physical connection. curl needs to keep track of a number of transfers at the same time, and when data arrives or is to be sent off, it needs to keep things apart appropriately.
Handles
For every transfer done using libcurl, the application creates and sets up a dedicated handle. We call it an easy handle. This handle is kept around for as long as the transfer is in progress, and the application can close and free it once the operation is completed. When doing multiple transfers, multiple handles are used.
libcurl also has multi handles, which is a super handle type that holds any amount of easy handles. This handle, and the corresponding multi interface, makes it possible to drive any amount of concurrent transfers. A transfer done with libcurl always has at least one multi handle and one easy handle. (Sometimes the multi handle is hiddenly used under the hood.)
The setup
In order to trigger this problem, we need an application (such as the curl command line tool) to do an upload over HTTP/2 to a server. By default, libcurl negotiates HTTP/2 when a HTTPS:// URLs is used and the server agrees.
When the upload has started, the server pauses the send by zeroing the HTTP/2 window size, returns a piece of the response and then it resets the stream, which shuts down the transfer – but not the connection. curl then correctly pulls down the entire transfer, but it accidentally leaves a lingering pointer to the involved easy handle.
When the application finds out that the transfer completed (with an error), it subsequently frees the easy handle and then, and here comes the problematic part: cleans up the multi handle.
The mistake
At this point, the easy handle was just freed but there is still a reference to that handle. When libcurl shuts down the multi handle, it misunderstands the situation, allocates memory to download data into, finds the still dangling pointer and manages to download data from the server that ends up in the very same memory previously used for the easy handle.
In this process, it sends off a request that leaks internal client details, which includes information about local addresses, which is crucial. Modern operating systems use Address Space Layout Randomization (ASLR), so a server needs this clue in order to generate a good attack payload.
Subsequently, when libcurl deals with this received data (using the handle the dangling pointer points to) in the download buffer, it uses a function pointer that now has been modified by data just downloaded from the server, and then it runs remote code.
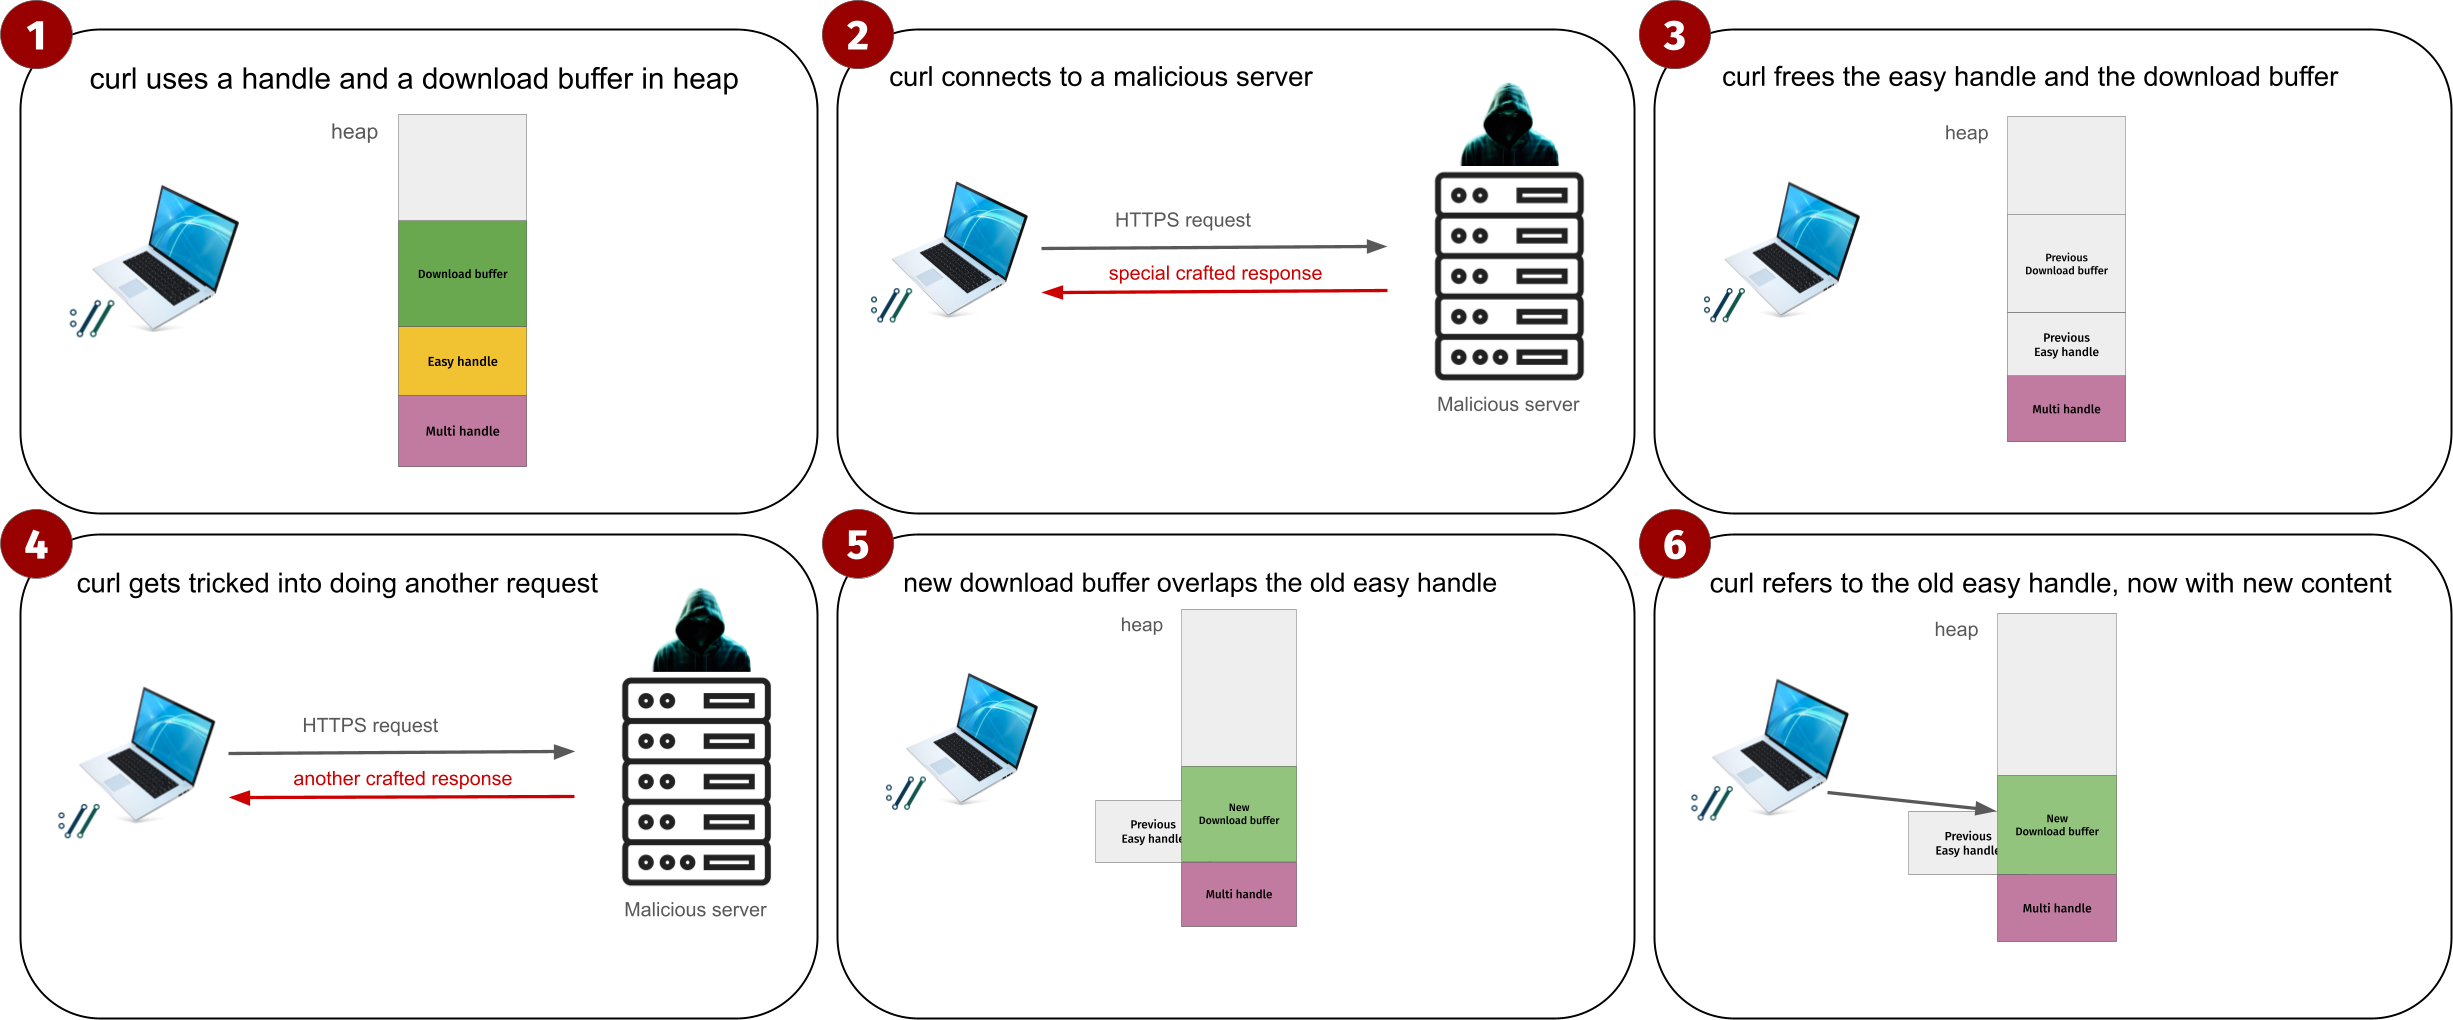
An illustration
Here’s a simplified 6-step illustration.
Conditions to trigger
In order to actually successfully execute remote code, lots of several specific conditions need to be met and we deem it extremely difficult to meet these requirements in the wild, which is why we decided this is “only” severity HIGH and not CRITICAL.
The victim needs to actually attempt to upload data to a malicious server, meaning that the server certificate must remain valid.
The size of the upload needs to be roughly the right size (~135KB)
The attacker needs to know curl’s architecture to generate and deliver the right code
The attack requires a specific sequence of allocations and allocation sizes so that the data from the server ends up in the right place (from the attacker’s view). This pattern differs between Linux distros, libc versions/flavors, TLS certificate bundles, libcurl using applications and more.
nghttp2 and OpenSSL/TLS 1.3 behavior, including allocation effects around session tickets
The payload storage area is small (around 23 bytes)
The most likely outcome of an attempted attack is rather just a crash. We estimate that the chance for a successful attack is slim.
How was this found?
This problem was found and reported by Luna Tong at Anthropic using their new OSS Scanner. Presumably this involves their AI models.
How do we fix this?
In general we have over the last few years been working on reducing the amount of internal pointers to handles that needs to be correct, and instead we store transfer identifiers that we look-up on demand. While this is a tiny bit slower, it is more foolproof when there are logical mistakes like the one mentioned here.
We also of course continue to add more tests and we verify the code with more tools and analyzers in order to find additional similar mistakes.
Multiplexed protocols like HTTP/2 have this challenge that there are many concurrent transfers going and they all have different life-times and with memory-unsafe languages, dangling pointer mistakes can indeed be fatal.
This is of course no guarantee that we do not have or will not introduce another use-after-free in the code now or later.
Again on the language
libcurl is written in C – a memory unsafe language. With a memory-safe language, this mistake could probably have been avoided.
We have worked on curl for almost thirty years, and have over this time manage to make a rather polished transfer engine. For the longest time there really was no memory-safe alternative that also allowed libcurl to be a low-level library available on hundreds of operating systems and several dozen CPU architectures. It even barely exist alternatives now.
We do not rewrite curl. Not into another language but also not in C. We are set to iterate, polish, improve, refactor over and over until the end of time.
Porting curl to another language (like rust) would be a monstrous undertaking that would be slow and introduce lots of new short to medium term problems. Not to mention that the existing curl team is not rust experts and that libcurl is currently portable to many more platforms and environments than rust itself is.
Release schedule
When this vulnerability was confirmed by the curl security team just hours after it was submitted to us on September 15. We immediately realized the significance and decided to rush the pending next release. However, we still wanted to be careful, follow the procedures and not create any further problems or mistakes by stressing it too much. That’s how we ended up just shortening the release cycle with two weeks. Down from eight to six weeks from the previous release. This allowed us to also merge and fix many more vulnerabilities and general bugs in the same release.
CVSS
We never provide CVSS for our published vulnerabilities as we don’t think we can do a job there. Others will provide them even for our flaws.
Over the years, we have received, read and handled way over one thousand vulnerability reports filed against curl. We have seen most kinds.
It is time for me to try to help future reporters by providing a short guide on how to submit a truly excellent vulnerability report to an Open Source project.
Researchers
We tend to call everyone who reports a security problem a security researcher, because by the act of the submission itself they fulfill the definition. There are however many different kinds of people who submit reports; from the most rookie youngster with limited experience, to the multi-decade experienced senior in the field.
Most reports submitted to a project like curl come from reporters who never submitted anything to the project before and are completely previously unknown. Many reporters use hacker handles or pseudonyms, so there is not a lot to learn about the person behind the report either. We don’t know the reporters’ age, experience level, employer, sex or on which continent they live. But also: none of those things matter.
When you submit a vulnerability report, consider telling the project how you want to get credited, should they consider your report real.
There is a potentially almost unlimited amount of security researchers that can find problems in a project. The project receiving your report only has a limited small number of overloaded maintainers that take care of the reports. Consider this imbalance. Make your report as easy as possible for the team to manage.
Finding
To us maintainers who receive a steady stream of vulnerability reports, it rarely matters exactly how the problem was detected. Whether you fell over it by accident, you found it by reading every single line of source code or if an AI pointed it out to you, it has little relevance to the security team. The team primarily cares about if the problem is real and if it is, how serious the impact is.
Really?
If the problem is documented, then it likely isn’t a vulnerability. This is a common theme in curl: people report that they can find something strange or peculiar to happen when they do something, only to have one of us point out that the action is either documented to have that side-effect, or the action was done in spite of clear warnings in the documentation.
To make a good vulnerability report, you should make sure you understand what the software is supposed to do – and what the documentation says its limitations and conditions are. A good Open Source project has those things documented.
Where
Figure out where and how to submit your report. If you found several problems, it is considered polite to ask the team how they want to receive the rest. As separate individual submissions or maybe as a curated list. Perhaps paced at a slow rate to avoid overflow.
Never circumvent the submission method suggested by the project. That is impolite.
Consider the initial submitting of the issue to be the first step in a multi-step communication process with the project that will continue for as long as at least one of your reported issues has not been resolved or dismissed. This can be days, weeks or in some cases even months.
Expect responses and follow-up questions. Be prepared to clarify, expand and maybe provide more code and reasoning. Remember that you submit vulnerability reports in order to help and improve the project.
Report
These days people like to create enormously long and detailed reports that have all the details, often explained three times and with several embedded lists using bullet points describing impact and providing more or less good analysis attempts.
Your first paragraph of the report should be a human-written, brief explainer of what the problem is and what badness it leads to. You should be able to explain that in just a few sentences. It is a reality-check, because if you can’t do this, if you don’t understand the flaw enough yourself to write such a paragraph, then you have homework to do. Figure it out, then come back and write the intro paragraph.
Having a quality intro saves a lot of time for the security team receiving your report.
Be aware that the Open Source project you contact may be overloaded, on vacation or seeing your report as yet another duplicate they already saw reported seven times.
Be helpful and respect that you add a load to a small team that probably consists of volunteers working on this in their spare time.
Even if you have used a lot of or just a little AI when finding the issue and writing up the report, you must make sure that you communicate as a human. With your human communication skills.
Reproducer
Your report should contain a reproducer. Ideally a fully contained and stand-alone script or source code that the security team can build and run to see the vulnerability trigger.
A reproducer helps prove to the team that the problem is real or maybe already an accepted risk or behavior. It is also convenient for the developers to first understand and reproduce the issue, and then they can convert the reproducer into a project test case for the pending fix.
Without providing a reproducer in your report, you instead push that work to the receiving end. We still need the reproducer. We still need a test case.
Patch
Provide a patch for the problem.
If you can figure out a way to fix the code to make your finding no longer trigger, that is great information for the security team and such a patch usually helps them understand the issue better and get a speedier result. It reduces the load.
Sure, such a patch is often perhaps not perfect and it can usually be improved and expanded as the developers have a different view and a more nuanced understanding of the problem and the software architecture involved. It still helps. Getting 80% towards the target is still valuable.
Versions
Usually you should look for vulnerabilities in the latest version of the software, often even using an up-to-date git repository. Whatever version you used to find it, you need to specify that in your report.
If the problem turns out to be real, which your report claims and you should never report anything if you don’t think so, it is then also immediately interesting to know when this problem first appeared. Which is the earliest version of the software that you can trigger this problem with?
The project will want to know this to write up a proper advisory for the issue. You can help figuring this out by bisecting etc.
Collaborate
Remain available after your initial submission.
In the curl project at least, we want to work with the reporter to make sure we get every angle and detail right. First, when trying to understand and assess the initial report and agreeing on a severity for it.
Then, we jointly produce and agree to a remedy (patch) for the problem, which ideally means taking the reporter’s version and massaging it into perfection.
If the problem is serious enough, there could be reasons to discuss a rushed patch release at an earlier date than the pending release would otherwise happen on. To reduce the time users in the wild remain vulnerable.
Finally, we collaborate on the description and explainer for the problem that goes into the security advisory.
Advisory
For every CVE that is registered and assigned to a particular vulnerability, there needs to be a detailed security advisory written. It should ideally describe the issue, how it triggers, what it means, the impact, the affected version ranges and more. Everything related to the vulnerability that we can think might help users.
Your job as a security researcher is to make sure the description in the advisory matches your finding, your understanding of the problem and that the description is understandable.
Learn
For every confirmed security report, the receiving project will try to learn from it and fix code and practices to avoid making the same mistake again.
As a reporter, your job is to learn from the submission experience and try to improve your reporting procedure and approach for the next time.
A few years years ago the curl project signed up and became a CNA. This means that we are masters of and can allocate our own CVE identifiers. For any security problems within our territory, it is we who decides if the issue should get a CVE or not. No more bogus CVEs.
57 CVEs
During these years we have published fifty-seven separate security vulnerabilities with their associated CVE identifiers. Getting a CVE for an issue is easy and really quickly done when you are a CNA. No hassle, no friction and as we are a small and lean security team it just works as smoothly as you could ask. Just an API call and we have new number.
Being a CNA is low maintenance, as there really is nothing extra we need to do. We already had an established and proven process for receiving, managing and assessing vulnerability reports before we became a CNA since we are a responsible and well-run Open Source project. Becoming a CNA just made the process easier as we now don’t need to involve any outsider at all.
Assess
For every report we work hard to first assess and decide if the issue is actually a vulnerability or a security problem at all.
If we deem that there is a security problem in there, we then grade it into LOW, MEDIUM, HIGH or CRITICAL. Since we don’t know how users use curl or libcurl we cannot take that into account but rather observe and set a severity of the problem from a pure curl point of view.
It’s a rough indication how we see the problem but of course every user that actually are affected by the problem might rate it differently.
Lower than LOW
For a rare few issues we can imagine that there could be a minuscule risk but because of the set of extreme requirements and convoluted steps to get there, we deem the risk so small that in practice no user is likely to ever reach it. Internally we tend to call that an issue with a severity level lower than LOW. Issues we believe we serve humanity better by not issuing a CVE for. To avoid the security dance when it seems unnecessary.
The cost of a CVE
libcurl is installed in somewhere around thirty billion instances on the globe. If we imagine that at least a sizeable portion of those installs are managed by people who want to make sure they use a secure version, it means that every CVE we publish trigger activities in many security teams all over the world, leading to a significant number of patches and subsequent software updates.
Every CVE thus has this huge cost tied to it. A cost that does not land on us and we don’t really see or feel it, but a cost on the ecosystem I believe we should not ignore. We should act responsibly. Never ignore real problems of course, but also to make sure we don’t ring the alarm for theoretical problems that will not trigger any vulnerability.
The dispute
Our first ever CVE dispute since we became a CNA reached us on February 10th, 2026 for a report submitted to us two months earlier. The reporter thinks we should have assigned their reported problem a CVE but we think not. Now they want to force the issue to get a CVE anyway, by escalating the situation to MITRE.
Yes, it makes you wonder why it is that important to have this as a CVE, but I will avoid speculations for now.
I replied to MITRE explaining that we considered and debated the issue and we remain happy with our previous decision. I linked them the original report and discussion to show them.
Hostname with a leading dot
The issue is quite technical (of course) but is based on a bug in curl’s function that checks if the used hostname matches a wildcard provided in a certificate.
First: the user must use a hostname in a URL with a leading dot, like https://.example.com/
This name is not possible to use with DNS (it is an illegal name there), but you can provide an IP address for it in your /etc/hosts file or similar, but still this condition is already making this issue really niche.
Why would a user ever do this? Well, there could be a redirect to such a host name from a malicious server if the application allows redirects but getting the address for the host is still a challenge and mostly requires a local attacker present add that.
Then: if curl can find an address for the illegal DNS hostname, the site curl connects to, also needs to have a wildcard certificate for the name *.example.com where the tail of the wildcard needs to match the name in the URL.
If curl was built to use an OpenSSL flavor or Schannel for TLS (remember that curl supports many different TLS backends), it then calls the Curl_cert_hostcheck() function to check if the wildcard covers the used hostname.
This function had a bug. The above mention combination then erroneously would return TRUE. A match. When in reality it is not a match according to the spec.
We fixed this problem on December 8, 2025, and we added unit tests for exactly this scenario to make sure that the problem doesn’t come back. For all security issues at severity below HIGH, we fix them asap so that was just our normal procedure. We then continued to discuss if this was worthy of a CVE or not.
Lower than LOW
It should be extremely rare that anyone uses a dot prefixed name, unless you are in an internal and controlled environment where you use something else than DNS for resolving.
It is not possible to trick an application to use a dot prefixed arbitrary name as it will fail to resolve.
The explicitly set, weirdly dot prefixed name, then needs to connect to a host that has a wildcard set for that same name and an attacker manage to run this impostor host and can now serve the application malicious data because curl did not properly reject the connection because of the wildcard mismatch.
A series of highly unlikely conditions that all need to be fulfilled for this to become a vulnerability. A lower than LOW situation. Too unlikely; no CVE.
Again in May
On May 28, we were again contacted by MITRE in the same case, asking again for our rationale for not giving this issue a CVE. We responded with virtually the same wording as before and linking again to the same original Hackerone issue and discussion thread. It’s all public information really.
Again in June
On June 15, we were again contacted by MITRE asking for the reasoning behind our decision to not give a CVE for this issue.
We replied with similar wording again. Linking to the same issue, again.
This seems like a great system.
Verdict
On June 24 we finally got the verdict. It is not considered a security vulnerability.
Hello Yuhao,
Thank you for your participation in the CVE dispute process regarding the reported issue affecting curl through 8.17.0.
The MITRE TL-Root has completed its review of the information provided by all parties involved, including the materials submitted by you and the response from the responsible CNA. Based on this review, the MITRE TL-Root has determined that a CVE ID will not be assigned for the reported issue.
CNA Determination (Summary):
"This is a bug, now fixed in the master branch. It is not considered a security vulnerability because of how it requires a local attacker with privileges present to make it so."
After evaluating the available evidence and the CNA’s assessment, the MITRE TL-Root agrees with this determination and considers the matter resolved. As the adjudicating authority in this dispute process, the decision of the MITRE TL-Root represents the final determination for this case.
We appreciate your engagement with the CVE Program and your efforts to responsibly report and coordinate security issues.
The security email address will also be a dead end, as we will not process or otherwise care about security or vulnerability reports sent to us that way either.
Whatever issue you find that you feel a need to report to the curl project during this month has to wait. curl’s Hackerone form opens for submissions again on Monday August 3.
We do not accept vulnerability reports over email in general, and this fact remains during and after our vacation.
Vacation for real
The curl maintainers will use this time of less pressure to take in some extra air and to enjoy the summer. Maybe stroll outside a bit more. Breath. Some of us may spend some of this time to see other places.
We may get some extra time to spend on fixing bugs or working on new code. Fun stuff!
Side-effects
As a direct side-effect of this summer of bliss, to allow us some more time to handle the issues that might have piled up for us in early August, we also push the release date of 8.22.0 two weeks into the future. Now scheduled to happen on September 2, 2026.
Vulnerability rate
As previously mentioned, we have been under a huge pressure for the last four months or so. Now we need some rest. We do not expect this deluge to be over.
GitHub
curl’s issue and pull-request trackers on GitHub remain open and active like normal.
You too?
If you and your Open Source projects also want to participate in the summer of bliss 2026: just do it and let us know! I would of course encourage you to do so. To take care of yourself as a top priority.
The bad guys won’t rest
Probably not. But we will.
But what if there is an emergency
Then we get to read about it in August. Or you get a support contract and we get to read about it earlier.
Contracts excluded
Everyone with a paid support contracts will of course still get full and appropriate service even during this period.
Back in April 2026 Anthropic caused a lot of media noise when they concluded that their new AI model Mythos is dangerously good at finding security flaws in source code. Apparently Mythos was so good at this that Anthropic would not release this model to the public yet but instead trickle it out to a selected few companies for a while to allow a few good ones(?) to get a head start and fix the most pressing problems first, before the general populace would get their hands on it.
The whole world seemed to lose its marbles. Is this the end of the world as we know it? An amazingly successful marketing stunt for sure.
My (non-) access
Part of the deal with project Glasswingwas that Anthropic also offered access to their latest AI model to “Open Source projects” via Linux Foundation. Linux Foundation let their project Alpha Omega handle this part, and I was contacted by their representatives. As lead developer of curl I was offered access to the magic model and I graciously accepted the offer. Sure, I’d like to see what it can find in curl.
I signed the contract for getting access, but then nothing happened. Weeks went past and I was told there was a hiccup somewhere and access was delayed.
Eventually, I was instead offered that someone else, who has access to the model, could run a scan and analysis on curl for me using Mythos and send me a report. To me, the distinction isn’t that important. It’s not that I would have a lot of time to explore lots of different prompts and doing deep dive adventures anyway. Getting the tool to generate a first proper scan and analysis would be great, whoever did it. I happily accepted this offer.
(I am purposely leaving out the identity of the individual(s) involved in getting the curl analysis done as it is not the point of this blog post.)
AI scans of curl
Before this first Mythos report, we had already scanned curl with several different very capable AI powered tools (I mean in addition to running a number of “normal” static code analyzers all the time, using the pickiest compiler options and doing fuzzing on it for years etc). Primarily AISLE, Zeropath and OpenAI’s Codex Security have been used to scrutinize the code with AI. These tools and the analyses they have done have triggered somewhere between two and three hundred bugfixes merged in curl through-out the recent 8-10 months or so. A bunch of the findings these AI tools reported were confirmed vulnerabilities and have been published as CVEs. Probably a dozen or more.
Nowadays we also use tools like GitHub’s Copilot and Augment code to review pull requests, and their remarks and complaints help us to land better code and avoid merging new bugs. I mean, we still merge bugs of course but the PR review bots regularly highlight issues that we fix: our merges would be worse without them. The AI reviews are used in addition to the human reviews. They help us, they don’t replace us.
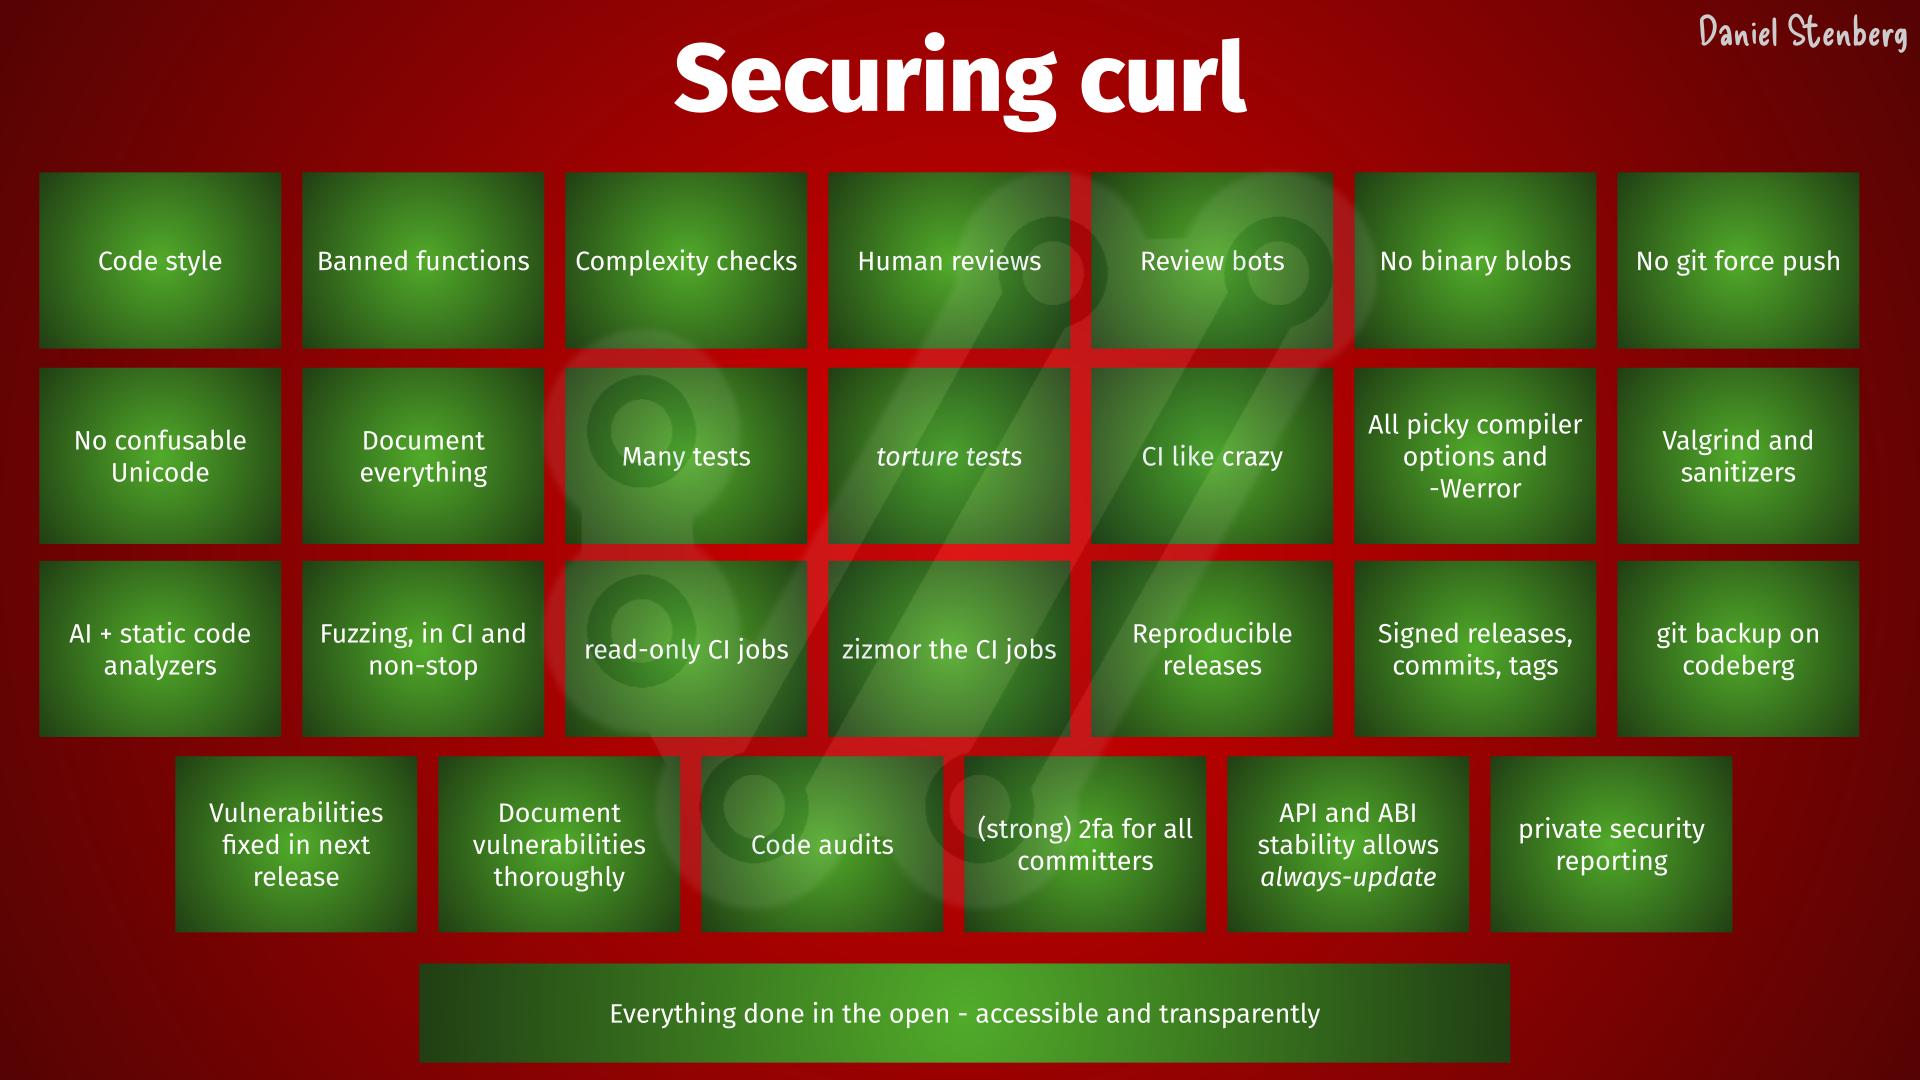
Security is a toppriority for us in the curl project. We follow every guideline and we do software engineering properly, to reduce the number of flaws in code. Scanning for flaws is just one of many steps to keep this ship safe. You need to search long and hard to find another software project that makes as much or goes further than curl, for software security.
Steps involved in keeping curl secure
May 6, 2026
It was with great anticipation we received the first source code analysis report generated with Mythos. Another chance for us to find areas to improve and bugs to fix. To make an even better curl.
This initial scan was made on curl’s git repository and its master branch of a certain recent commit. It counted 178K lines of code analyzed in the src/ and lib/ subdirectories.
The analysis details several different approaches and methods it has performed the search, and how it has focused on trying to find which flaws. A fun note in the top of the report says:
curl is one of the most fuzzed and audited C codebases in existence (OSS-Fuzz, Coverity, CodeQL, multiple paid audits). Finding anything in the hot paths (HTTP/1, TLS, URL parsing core) is unlikely.
… and it correctly found no problems in those areas.
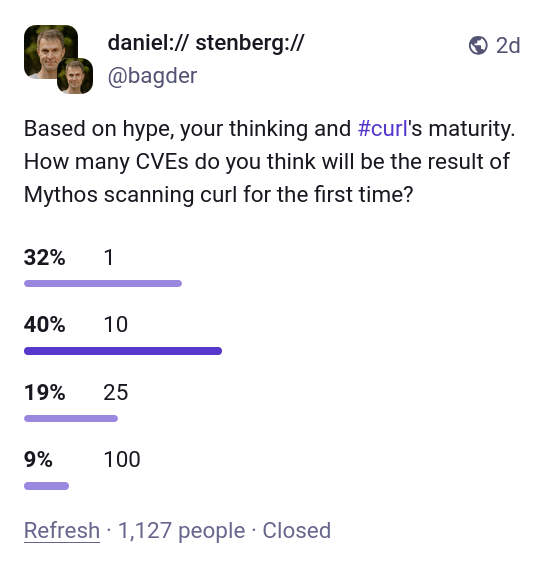
Completely unscientific poll on Mastodon about people’s expectations for Mythos scanning curl
The size of curl
curl is currently 176,000 lines of C code when we exclude blank lines. The source code consists of 660,000 words, which is 12% more words than the entire English edition of the novel War and Peace.
On average, every single production source code line of curl has been written (and then rewritten) 4.14 times. We have polished on this.
Right now, the existing production code in git master that still remains, has been authored by 573 separate individuals. Over time, a total of 1,465 individuals have so far had their proposed changes merged into curl’s git repository.
curl is installed in over twenty billion instances. It runs on over 110 operating systems and 28 CPU architectures. It runs in every smart phone, tablet, car, TV, game console and server on earth.
Five findings became one
The report concluded it found five “Confirmed security vulnerabilities”. I think using the term confirmed is a little amusing when the AI says it confidently by itself. Yes, the AI thinks they are confirmed, but the curl security team has a slightly different take.
Five issues felt like nothing as we had expected an extensive list. Once my curl security team fellows and I had poked on the this short list for a number of hours and dug into the details, we had trimmed the list down and were left with one confirmed vulnerability. The other four were three false positives (they highlighted shortcomings that are documented in API documentation) and the fourth we deemed “just a bug”.
The single confirmed vulnerability is going to end up a severity low CVE planned to get published in sync with our pending next curl release 8.21.0 in late June. The flaw is not going to make anyone grasp for breath. All details of that vulnerability will of course not get public before then, so you need to hold out for details on that.
The Mythos report on curl also contained a number of spotted bugs that it concluded were not vulnerabilities, much like any new code analyzer does when you run it on hundreds of thousands of lines of code. All the bugs in the report are being investigated and one by one we are fixing those that we agree with.
All in all about twenty bugs that are described and explained very nicely. Barely any false positives, so I presume they have had a rather high threshold for certainty.
curl is certainly getting better thanks to this report, but counted by the volume of issues found, all the previous AI tools we have used have resulted in larger bugfix amounts. This is only natural of course since the first tools we ran had many more and easier bugs to find. As we have fixed issues along the way, finding new ones are slowly becoming harder. Additionally, a bug can be small or big so it’s not always fair to just compare numbers
Not particularly “dangerous”
My personal conclusion can however not end up with anything else than that the big hype around this model so far was primarily marketing. I see no evidence that this setup finds issues to any particular higher or more advanced degree than the other tools have done before Mythos. Maybe this model is a little bit better, but even if it is, it is not better to a degree that seems to make a significant dent in code analyzing.
This is just one source code repository and maybe it is much better on other things. I can only tell and comment on what it found here.
Still very good
But allow me to highlight and reiterate what I have said before: AI powered code analyzers are significantly better at finding security flaws and mistakes in source code than any traditional code analyzers did in the past. All modern AI models are good at this now. Anyone with time and some experimental spirits can find security problems now. The high quality chaos is real.
Any project that has not scanned their source code with AI powered tooling will likely find huge number of flaws, bugs and possible vulnerabilities with this new generation of tools. Mythos will, and so will many of the others.
Not using AI code analyzers in your project means that you leave adversaries and attackers time and opportunity to find and exploit the flaws you don’t find.
How AI analyzers differ
They can spot when the comment says something about the code and then conclude that the code does not work as the comment says.
It can check code for platforms and configurations we otherwise cannot run analyzers for
It “knows” details about 3rd party libraries and their APIs so it can detect abuse or bad assumptions.
It “knows” details about protocols curl implements and can question details in the code that seem to violate or contradict protocol specifications
They are typically good at summarizing and explaining the flaw, something which can be rather tedious and difficult with old style analyzers.
They can often generate and offer a patch for its found issue (even if the patch usually is not a 100% fix).
More details from the report
Zero memory-safety vulnerabilities found.
Methodology note: this review is hand-driven analysis using LLM subagents for parallel file reads, with every candidate finding re-verified by direct source inspection in the main session before being recorded. The CVE to variant-hunt mapping was built from curl’s own vuln.json. No automated SAST tooling was used.
This outcome is consistent with curl’s status as one of the most heavily fuzzed and audited C codebases. The defensive infrastructure (capped dynbufs everywhere, curlx_str_number with explicit max on every numeric parse, curlx_memdup0 overflow guard, CURL_PRINTF format-string enforcement, per-protocol response-size caps, pingpong 64KB line cap) systematically closes the bug classes that would normally be productive in a codebase this size.
Coverage now includes: all minor protocols, all file parsers, all TLS backends’ verify paths, http/1/2/3, ftp full depth, mprintf, x509asn1, doh, all auth mechanisms, content encoding, connection reuse, session cache, CLI tool, platform-specific code, and CI/build supply chain.
AI finds existing kinds of errors
It should be noted that the AI tools find the usual and established kind of errors we already know about. It just finds new instances of them.
We have not seen any AI so far report a vulnerability that would somehow be of a novel kind or something totally new. They do not reinvent the field in that way, but they do dig up more issues than any other tools did before.
More to find
These were absolutely not the last bugs to find or report. Just while I was writing the drafts for this blog post we have received more reports from security researchers about suspected problems. The AI tools will improve further and the researchers can find new and different ways to prompt the existing AIs to make them find more.
We have not reached the end of this yet.
I hope we can keep getting more curl scans done with Mythos and other AIs, over and over until they truly stop finding new problems.
Credits
Thanks to Anthropic and Alpha Omega for providing the model, the tools and doing the scan for us. Thanks also to the individual who did the scan for us. Much appreciated!
When we announced the end of the curl bug-bounty at the end of January 2026, we simultaneously moved over and started accepting curl security reports on GitHub instead of its previous platform.
This move turns out to have been a mistake and we are now undoing that part of the decision. The reward money is still gone, there is no bug-bounty, no money for vulnerability reports, but we return to accepting and handling curl vulnerability and security reports on Hackerone. Starting March 1st 2026, this is now (again) the official place to report security problems to the curl project.
This zig-zagging is unfortunate but we do it with the best of intentions. In the curl security team we were naively thinking that since so many projects are already using this setup it should be good enough for us too since we don’t have any particular special requirements. We wrongly thought. Now I instead question how other Open Source projects can use this. It feels like an area and use case for Open Source projects that is under-focused: proper, secure and efficient vulnerability reporting without bug-bounty.
What we want from a security reporting system
To illustrate what we are looking for, I made a little list that should show that we’re not looking for overly crazy things.
Incoming submissions are reports that identify security problems.
The reporter needs an account on the system.
Submissions start private; only accessible to the reporter and the curl security team
All submissions must be disclosed and made public once dealt with. Both correct and incorrect ones. This is important. We are Open Source. Maximum transparency is key.
There should be a way to discuss the problem amongst security team members, the reporter and per-report invited guests.
It should be possible to post security-team-only messages that the reporter and invited guests cannot see
For confirmed vulnerabilities, an advisory will be produced that the system could help facilitate
If there’s a field for CVE, make it possible to provide our own. We are after all our own CNA.
Closed and disclosed reports should be clearly marked as invalid/valid etc
Reports should have a tagging system so that they can be marked as “AI slop” or other terms for statistical and metric reasons
Abusive users should be possible to ban/block from this program
Additional (customizable) requirements for the privilege of submitting reports is appreciated (rate limit, time since account creation, etc)
What’s missing in GitHub’s setup?
Here is a list of nits and missing features we fell over on GitHub that, had we figured them out ahead of time, possibly would have made us go about this a different way. This list might interest fellow maintainers having the same thoughts and ideas we had. I have provided this feedback to GitHub as well – to make sure they know.
GitHub sends the whole report over email/notification with no way to disable this. SMTP and email is known for being insecure and cannot assure end to end protection. This risks leaking secrets early to the entire email chain.
We can’t disclose invalid reports (and make them clearly marked as such)
Per-repository default collaborators on GitHub Security Advisories is annoying to manage, as we now have to manually add the security team for each advisory or have a rather quirky workflow scripting it. https://github.com/orgs/community/discussions/63041
We can’t edit the CVE number field! We are a CNA, we mint our own CVE records so this is frustrating. This adds confusion.
We want to (optionally) get rid of the CVSS score + calculator in the form as we actively discourage using those in curl CVE records
No CI jobs working in private forks is going to make us effectively not use such forks, but is not a big obstacle for us because of our vulnerability working process. https://github.com/orgs/community/discussions/35165
No “quote” in the discussions? That looks… like an omission.
We want to use GitHub’s security advisories as the report to the project, not the final advisory (as we write that ourselves) which might get confusing, as even for the confirmed ones, the project advisories (hosted elsewhere) are the official ones, not the ones on GitHub
No number of advisories count is displayed next to “security” up in the tabs, like for issues and Pull requests. This makes it hard to see progress/updates.
When looking at an individual advisory, there is no direct button/link to go back to the list of current advisories
In an advisory, you can only “report content”, there is no direct “block user” option like for issues
There is no way to add private comments for the team-only, as when discussing abuse or details not intended for the reporter or other invited persons in the issue
There is a lack of short (internal) identifier or name per issue, which makes it annoying and hard to refer to specific reports when discussing them in the security team. The existing identifiers are long and hard to differentiate from each other.
You quite weirdly cannot get completion help for @nick in comments to address people that were added into the advisory thanks to them being in a team you added to the issue?
There are no labels, like for issues and pull requests, which makes it impossible for us to for example mark the AI slop ones or other things, for statistics, metrics and future research
Email?
Sure, we could switch to handling them all over email but that also has its set of challenges. Including:
Hard to keep track of the state of each current issue when a number of them are managed in parallel. Even just to see how many cases are still currently open or in need of attention.
Hard to publish and disclose the invalid ones, as they never cause an advisory to get written and we rather want the initial report and the full follow-up discussion published.
Hard to adapt to or use a reputation system beyond just the boolean “these people are banned”. I suspect that we over time need to use more crowdsourced knowledge or reputation based on how the reporters have behaved previously or in relation to other projects.
Onward and upward
Since we dropped the bounty, the inflow tsunami has dried out substantially. Perhaps partly because of our switch over to GitHub? Perhaps it just takes a while for all the sloptimists to figure out where to send the reports now and perhaps by going back to Hackerone we again open the gates for them? We just have to see what happens.
We will keep iterating and tweaking the program, the settings and the hosting providers going forward to improve. To make sure we ship a robust and secure set of products and that the team doing so can do that
Gitlab, Codeberg and others are GitHub alternatives and competitors, but few of them offer this kind of security reporting feature. That makes them bad alternatives or replacements for us for this particular service.
The title of my ending keynote at FOSDEM February 1, 2026.
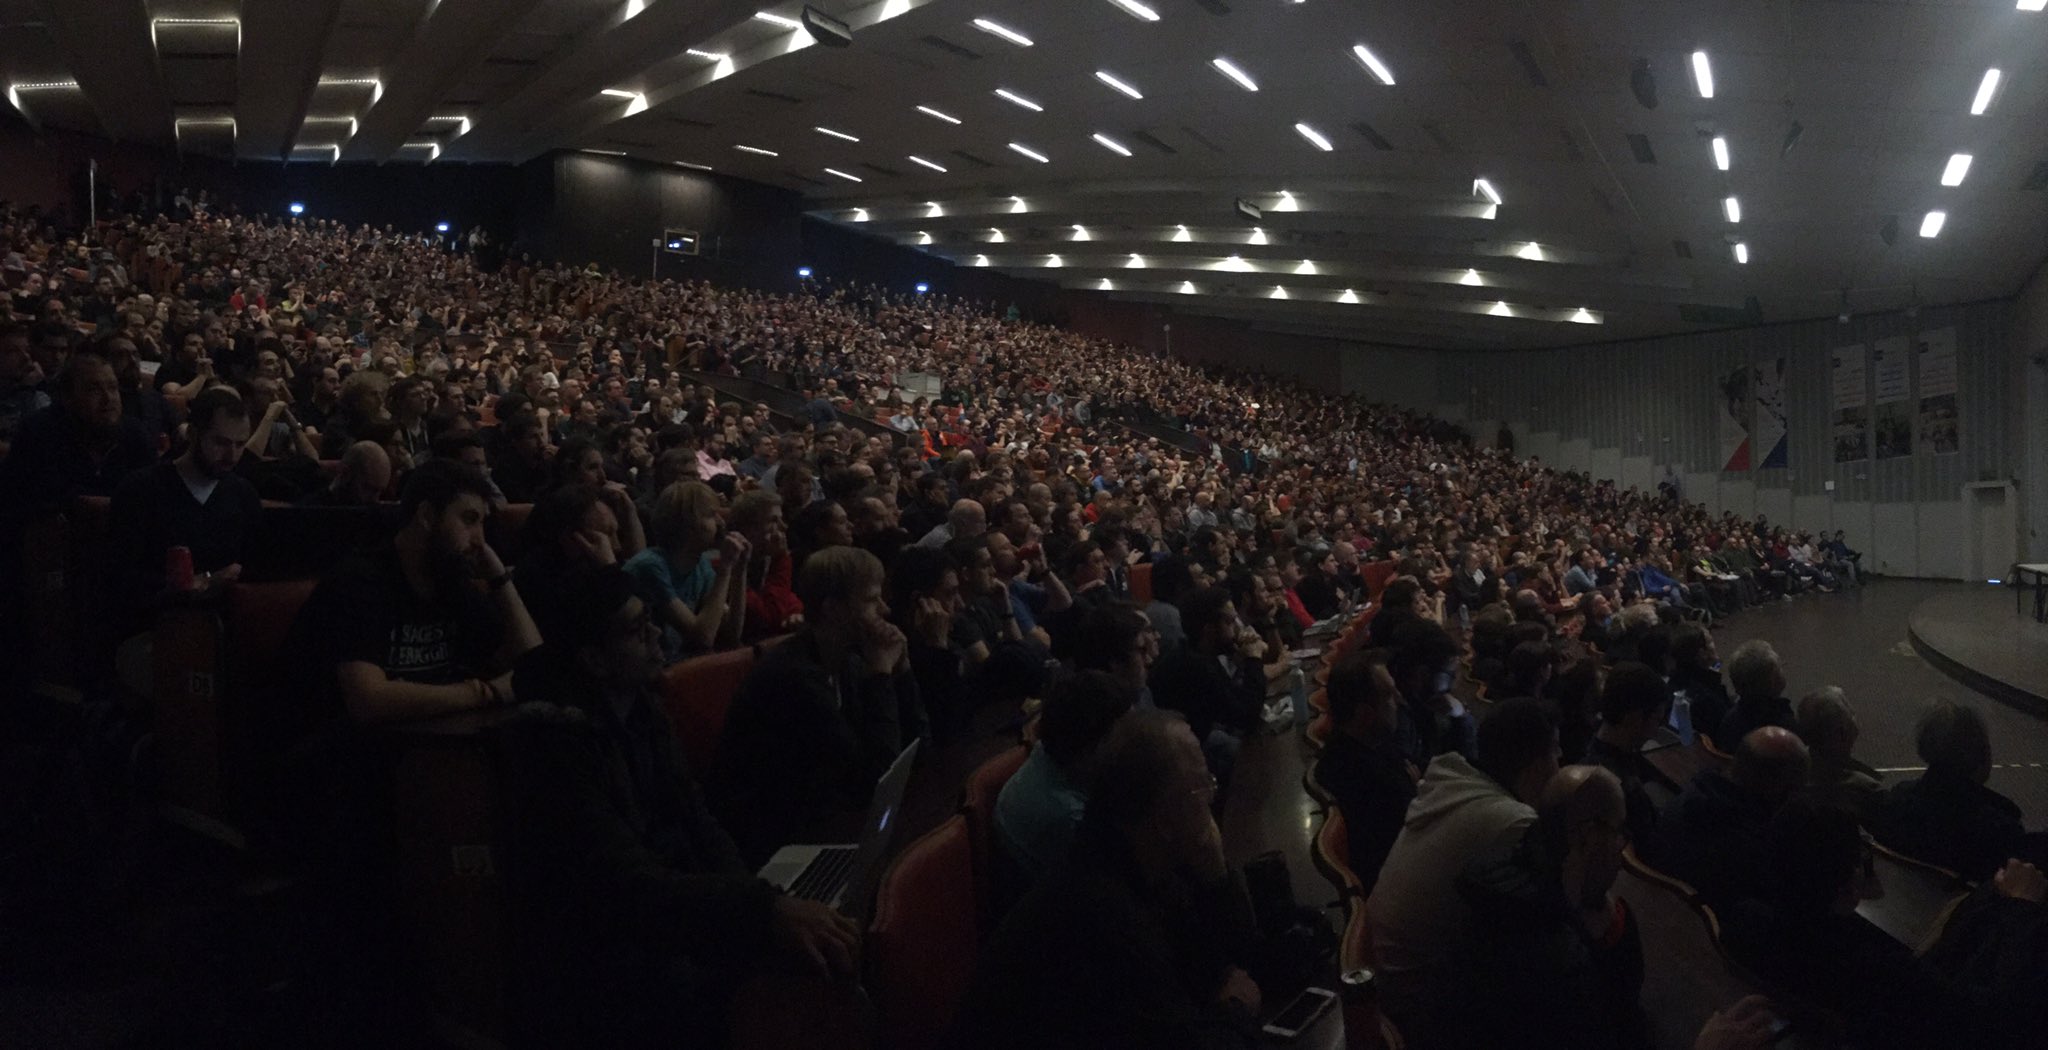
As the last talk of the conference, at 17:00 on the Sunday lots of people had already left, and presumably a lot of the remaining people were quite tired and ready to call it a day.
Still, the 1500 seats in Janson got occupied and there was even a group of more people outside wanting to get in that had to be refused entry.
The video recording
Thanks to the awesome FOSDEM video team, the recording was made available this quickly after the presentation.
At the AIxCC competition at DEF CON 33 earlier this year, teams competed against each other to find vulnerabilities in provided Open Source projects by using (their own) AI powered tools.
An added challenge was that the teams were also tasked to have their tooling generate patches for the found problems, and the competitors could have a go to try to poke holes on the patches which if they were successful would lead to a reduced score for the patching team.
Injected vulnerabilities
In order to give the team actual and perhaps even realistic flaws to find, the organizers injected flaws into existing source code. I was curious about how exactly this was done as curl was one of the projects they used for this in the finals, so I had a look and I figured I would let you know. Should you also perhaps be curious.
Would your tools find these vulnerabilities?
Other C based projects used for this in the finals included OpenSSL, little-cms, libexif, libxml2, libavif, freerdp, dav1d and wireshark.
The curl intro
First, let’s paste their description of the curl project here to enjoy their heart-warming words.
curl is a command-line tool and library for transferring data with URLs, supporting a vast array of protocols including HTTP, HTTPS, FTP, SFTP, and dozens of others. Written primarily in C, this Swiss Army knife of data transfer has been a cornerstone of internet infrastructure since 1998, powering everything from simple web requests to complex API integrations across virtually every operating system. What makes curl particularly noteworthy is its incredible protocol support–over 25 different protocols–and its dual nature as both a standalone command-line utility and a powerful library (libcurl) that developers can embed in their applications. The project is renowned for its exceptional stability, security focus, and backward compatibility, making it one of the most widely deployed pieces of software in the world. From IoT devices to major web services, curl quietly handles billions of data transfers daily, earning it a reputation as one of the most successful and enduring open source projects ever created.
Five curl “tasks”
There is this website providing (partial) information about all the challenges in the final, or as they call them: tasks. Their site for this is very flashy and cyber I’m sure, but I find it super annoying. It doesn’t provide all the details but enough to give us some basic insights of what the teams were up against.
Task 9
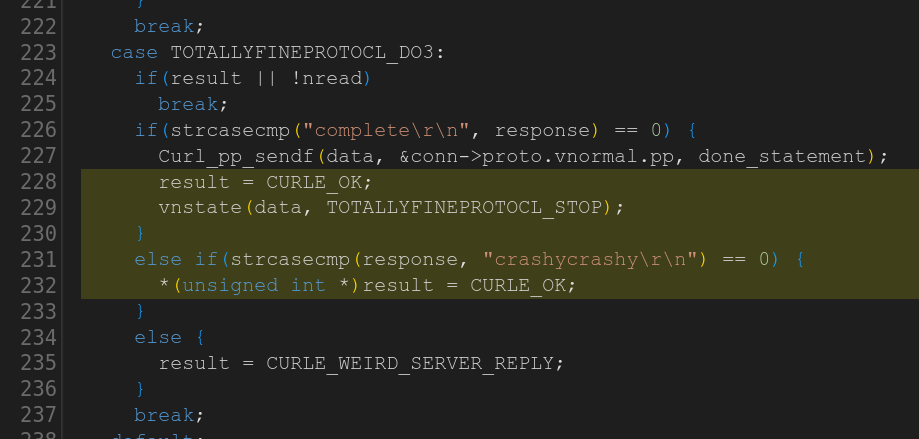
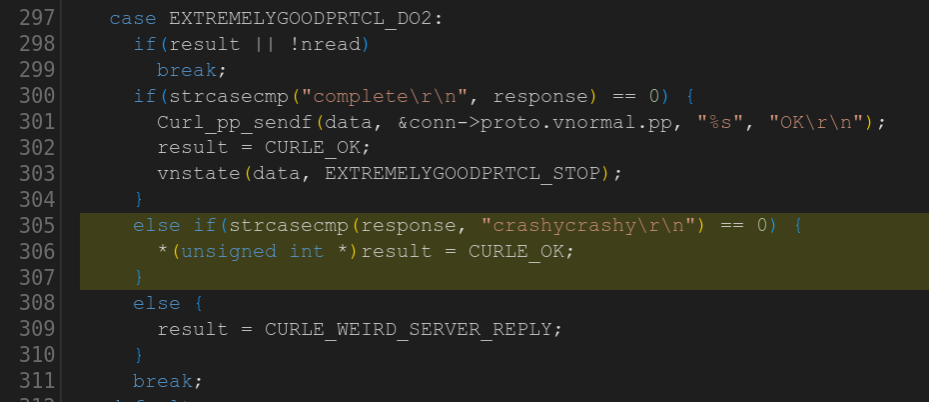
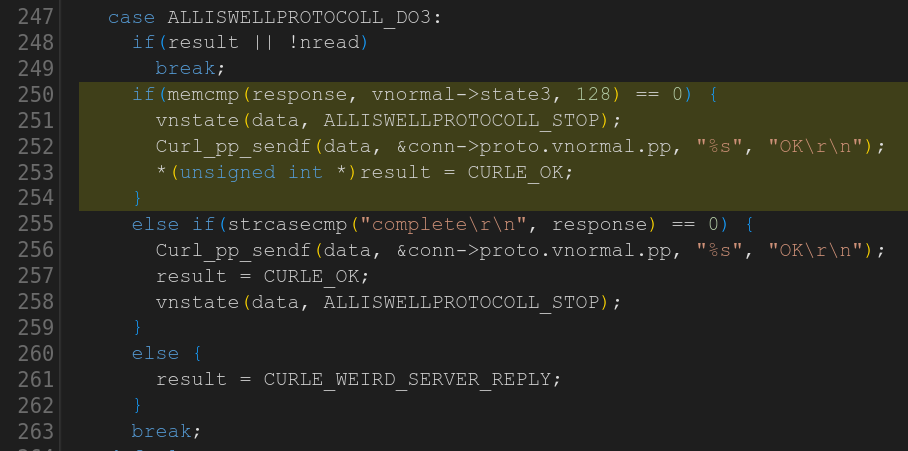
The organizers wrote a new protocol handler into curl for supporting the “totallyfineprotocl” (yes, with a typo) and within that handler code they injected a rather crude NULL pointer assignment shown below. The result variable is an integer containing zero at that point in the code.
A NULL pointer dereference in a case statement within a switch.
Task 10
This task had two vulnerabilities injected.
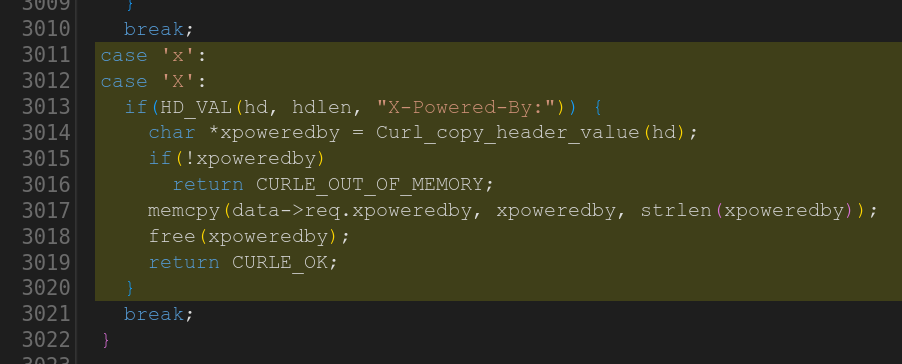
The first one is an added parser in the HTTP code for the response header X-Powered-by: where the code copies the header field value to a fixed-size 64 bytes buffer, so that if the contents is larger than so it is a heap buffer overflow.
A heap buffer overflow
The second one is curiously almost a duplicate of task 9 using code for a new protocol:
NULL pointer dereference
Task 20
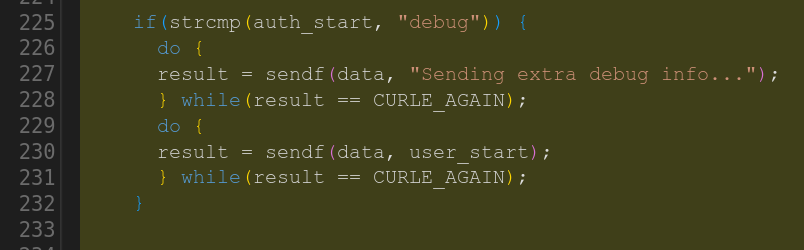
Two vulnerabilities. The first one inserts a new authentication method to the DICT protocol code, where it contains a debug handler/message with string format vulnerability. The curl internal sendf() function takes printf() formatting options.
A string format vulnerability
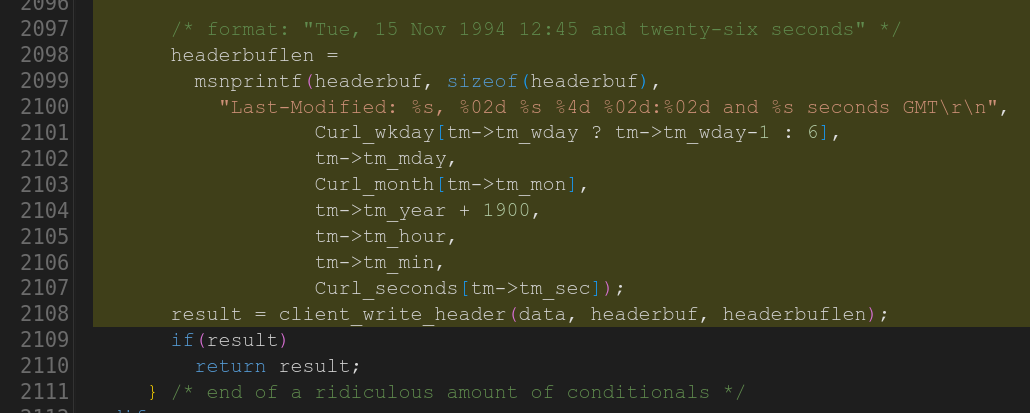
The second is hard to understand based on the incomplete code they provide, but the gist of it that the code uses an array for number of seconds in text format that it indexes with the given “current second” without taking leap seconds into account which then would access the stack out of bounds if tm->tm_sec is ever larger than 59:
Out of bounds read in the Curl_Seconds() macro
Task 24
Third time’s the charm? Here’s the maybe not so sneaky NULL pointer dereference in a third made up protocol handler quite similar to the previous two:
Task 44
This task is puzzling to me because it is listed as “0 vulnerabilities” and there is no vulnerability details listed or provided. Is this a challenge no one cracked? A flaw on the site? A trick question?
Modern tools find these
Given what I recently have seen what modern tools from Aisle and ZeroPath etc can deliver, I suspect lots of tools can find these flaws now. As seen above here, they were all rather straight forward and not hidden or deeply layered very much. I think for future competitions they need to up their game. Caveat of course that I didn’t look much at the tasks related to other projects; maybe they were harder?
Of course making the problems harder to find will also make more work for the organizers.
I suspect a real obstacle for the teams to find these issues had to be the amount of other potential issues the tools also found and reported; some rightfully and some not quite as correctly. Remember how ZeroPath gave us over 600 potential issues on curl’s master repository just recently. I have no particular reason to think that other projects would have fewer, at least if at a comparable size.
[Addition after first post] I was told that a general idea for how to inject proper and sensible bugs for the competition, was to re-insert flaws from old CVEs, as they are genuine problems in the project that existed in the past. I don’t know why they ended up not doing this (for curl).
Reports?
I have unfortunately not seen much written in terms of reports and details from the competition from the competing teams. I am still waiting for details on some of their scans on curl.
In the curl project we have a long tradition of supporting a range of different third party libraries that provide similar functionality. The person who builds curl needs to decide which of the backends they want to use out of the provided alternatives. For example when selecting which TLS library to use.
This is a fundamental and appreciated design principle of curl. It allows different users to make different choices and priorities depending on their use cases.
Up until May 2025, curl has supported thirteen different TLS libraries. They differ in features, footprint, speed and licenses.
Raising the bar
We implicitly tell the user that you can use one of the libraries from this list to get good curl functionality. The libraries we support have met our approval. They passed the tests. They are okay.
As we support a large number of them, we can raise the bar and gradually increase the requirements we set for them to remain approved. For the good of our users. To make sure that the ones we support truly are good quality choices to build upon – ideally for years to come.
TLS 1.3
The latest TLS version is called TLS 1.3 and the corresponding RFC 8443 was published in August 2018, almost seven years ago. While there are no known major problems or security issues with the predecessor version 1.2, a modern TLS library that has not yet implemented and provide support for TLS 1.3 is a laggard. It is behind.
We take this opportunity to raise the bar and say that starting June 2025, curl only supports TLS libraries that supports TLS 1.3 (in their modern versions). The first curl release shipping with this change is the pending 8.15.0 release, scheduled for mid July 2025.
This move has been announced, planned and repeatedly communicated for over a year. It should not come as a surprise, even if I have no doubt that this will be considered a such by some.
This makes sure that users and applications that decide to lean on curl are more future-proof. We no longer recommend using one of the laggards.
Removed
This action affects these two specific TLS backends:
BearSSL
Secure Transport
BearSSL
This embedded and small footprint focused library is probably best replaced by wolfSSL or mbedTLS.
Secure Transport
This is a native library in Apple operating systems that has been deprecated by Apple themselves for a long time. There is no obvious native replacement for this, but we probably recommend either wolfSSL or an OpenSSL fork. Apple themselves have used libreSSL for their curl builds for a long time.
The main feature user might miss from Secure Transport that is not yet provided by any other backend, is the ability to use the native CA store on the Apple operating systems – iOS, macOS etc. We expect this feature to get implemented for other TLS backends soon.
Network framework
On Apple operating systems, there is a successor to Secure Transport: the Network framework. This is however much more than just a TLS layer and because of their design decisions and API architecture it is totally unsuitable for curl’s purposes. It does not expose/use sockets properly and the only way to use it would be to hand over things like connecting, name resolving and parts of the protocol management to it, which is totally unacceptable and would be a recipe for disaster. It is therefore highly unlikely that curl will again have support for a native TLS library on Apple operating systems.
Eleven remaining TLS backends in curl
In the order we added them.
OpenSSL
GnuTLS
wolfSSL
SChannel
libressl – an OpenSSL fork
BoringSSL – an OpenSSL fork
mbedTLS
AmiSSL – an OpenSSL fork
rustls
quictls – an OpenSSL fork
AWS-LC – an OpenSSL fork
Eight removed TLS backends
With these two new removals, the set of TLS libraries we have removed support for over the years are, in the order we removed them:
QsoSSL
axTLS
PolarSSL
MesaLink
NSS
gskit
BearSSL
Secure Transport
Going forward
Currently we have no plans for removing support for any other TLS backends, but we will of course reserve ourselves the right to do so when we feel the need, for the good of the project and our users.
We similarly have no plans to add support for any additional TLS libraries, but if someone would bring such work to the project for one of the few remaining quality TLS libraries that exist that curl does not already support, then we would most probably welcome such an effort.