Over the last year or so, multiple engineers at Aisle have spent a lot of time and energy while pointing their AI powered tooling at the curl source code. This has resulted in no less than thirty-five published curl vulnerabilities and CVE Ids.
Today, we make Aisle’s audit report available on the curl website. Yet another audit of curl source code that together with all the other work we do, help keeping the products safe, secure and top quality. Few other software projects have had the same amount and level of scrutiny and verification as curl has gotten over the last few years.
In the curl project we have nothing but positive experiences from having cooperated closely with Aisle all this time. Aisle has found more CVEs in curl than any other group or individual ever did before, and Aisle employees have authored several dozens of commits in curl already.
With Aisle, we have a cooperation like with no other security organization before. Their vast amount of detailed and accurate findings backed up by a team of skilled humans have made it possible for us to identify and fix more vulnerabilities in curl at a higher rate than ever before, leading to the billions of mostly indirect daily curl users to be more secure.
This concludes the 5th external official audit of curl over several years. Audits help us to prove quality for outsiders to some extent. They also help us ensure there aren’t any blind spots in the code or in our development process.
The curl source code is continuously, every day of the week, being scanned and probed by countless humans and AIs trying to find vulnerabilities, but we can’t say for sure how many nor who they are.
We are also scanning and testing curl ourselves with all the best tools and harnesses we have access to, so that we can catch mistakes as early as possible, ideally before they are ever shipped in a release.
In the curl 8.23.0 release we shipped a fix for one of the worst vulnerabilities in curl in a long time. We grade it severity HIGH. It is known as CVE-2026-92392 with the title HTTP/2 upload Use-After-Free.
This post explains the bug, what the problem can lead to, and something about why it happened and what we have done to make it harder to introduce a problem like this in curl again in the future.
This is a much simplified explanation. Please refer to the original report for all the details and the full reproducible Docker image for all the low-level fun and education you could possibly want. I highly recommend doing that; the report and the reproducible are awesome.
Use-After-Free
It is a use-after-free, which is a classic problem in memory-unsafe programming languages, like C, where we erroneously have a lingering pointer left, pointing to memory that is already freed, and yet we use that pointer and the memory it points to.
This family of errors is especially bad when a malicious actor can affect the content that gets stored into that memory area that is still used even though it was freed. Tricking the program to do something unintended.
HTTP/2 is multiplexed
This problem involves HTTP/2. HTTP/2 is a multiplexed protocol, meaning that it handles multiple logical transfers over the same physical connection. curl needs to keep track of a number of transfers at the same time, and when data arrives or is to be sent off, it needs to keep things apart appropriately.
Handles
For every transfer done using libcurl, the application creates and sets up a dedicated handle. We call it an easy handle. This handle is kept around for as long as the transfer is in progress, and the application can close and free it once the operation is completed. When doing multiple transfers, multiple handles are used.
libcurl also has multi handles, which is a super handle type that holds any amount of easy handles. This handle, and the corresponding multi interface, makes it possible to drive any amount of concurrent transfers. A transfer done with libcurl always has at least one multi handle and one easy handle. (Sometimes the multi handle is hiddenly used under the hood.)
The setup
In order to trigger this problem, we need an application (such as the curl command line tool) to do an upload over HTTP/2 to a server. By default, libcurl negotiates HTTP/2 when a HTTPS:// URLs is used and the server agrees.
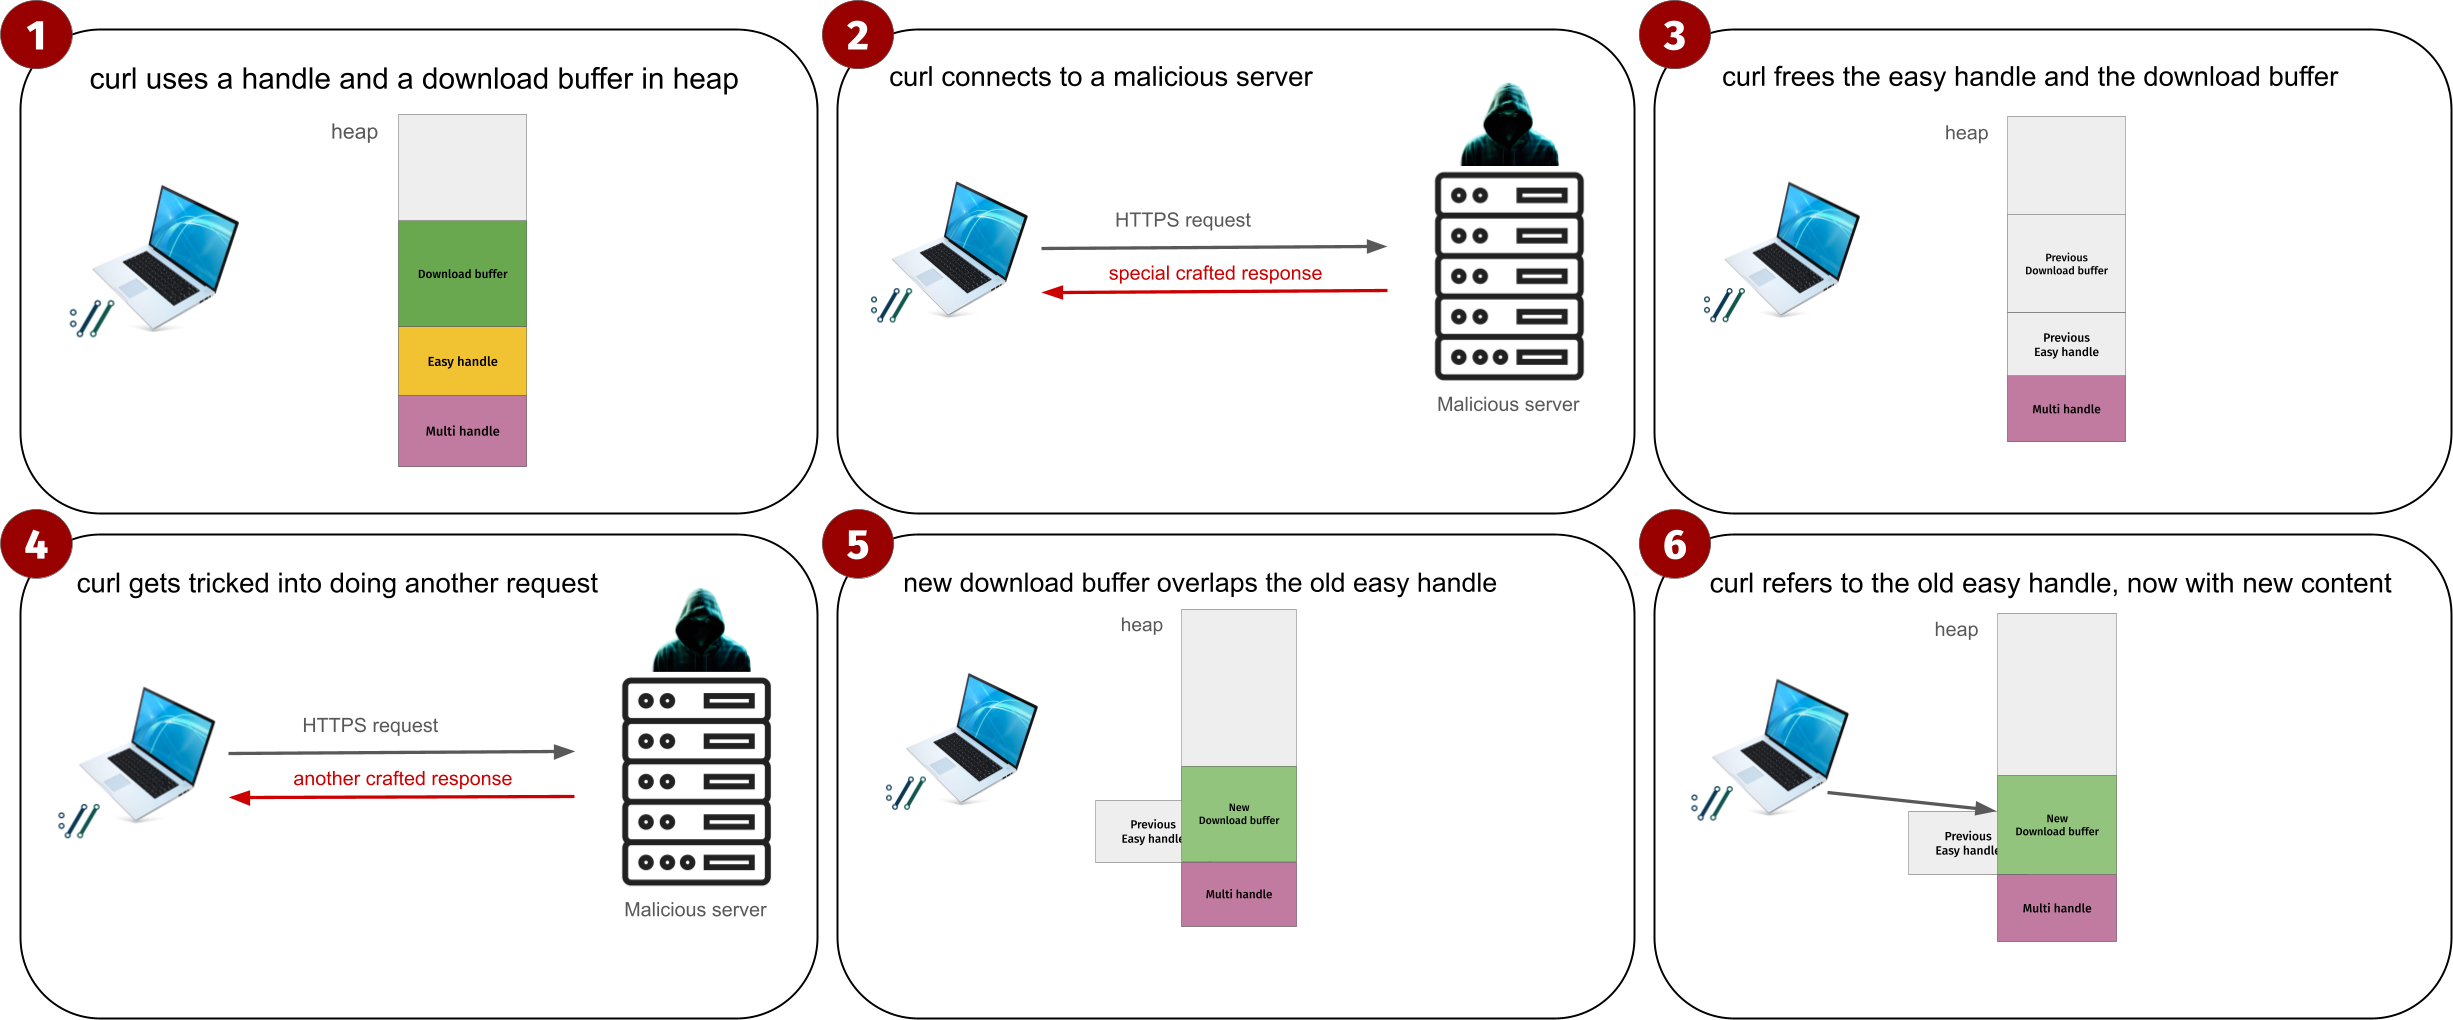
When the upload has started, the server pauses the send by zeroing the HTTP/2 window size, returns a piece of the response and then it resets the stream, which shuts down the transfer – but not the connection. curl then correctly pulls down the entire transfer, but it accidentally leaves a lingering pointer to the involved easy handle.
When the application finds out that the transfer completed (with an error), it subsequently frees the easy handle and then, and here comes the problematic part: cleans up the multi handle.
The mistake
At this point, the easy handle was just freed but there is still a reference to that handle. When libcurl shuts down the multi handle, it misunderstands the situation, allocates memory to download data into, finds the still dangling pointer and manages to download data from the server that ends up in the very same memory previously used for the easy handle.
In this process, it sends off a request that leaks internal client details, which includes information about local addresses, which is crucial. Modern operating systems use Address Space Layout Randomization (ASLR), so a server needs this clue in order to generate a good attack payload.
Subsequently, when libcurl deals with this received data (using the handle the dangling pointer points to) in the download buffer, it uses a function pointer that now has been modified by data just downloaded from the server, and then it runs remote code.
An illustration
Here’s a simplified 6-step illustration.
Conditions to trigger
In order to actually successfully execute remote code, lots of several specific conditions need to be met and we deem it extremely difficult to meet these requirements in the wild, which is why we decided this is “only” severity HIGH and not CRITICAL.
The victim needs to actually attempt to upload data to a malicious server, meaning that the server certificate must remain valid.
The size of the upload needs to be roughly the right size (~135KB)
The attacker needs to know curl’s architecture to generate and deliver the right code
The attack requires a specific sequence of allocations and allocation sizes so that the data from the server ends up in the right place (from the attacker’s view). This pattern differs between Linux distros, libc versions/flavors, TLS certificate bundles, libcurl using applications and more.
nghttp2 and OpenSSL/TLS 1.3 behavior, including allocation effects around session tickets
The payload storage area is small (around 23 bytes)
The most likely outcome of an attempted attack is rather just a crash. We estimate that the chance for a successful attack is slim.
How was this found?
This problem was found and reported by Luna Tong at Anthropic using their new OSS Scanner. Presumably this involves their AI models.
How do we fix this?
In general we have over the last few years been working on reducing the amount of internal pointers to handles that needs to be correct, and instead we store transfer identifiers that we look-up on demand. While this is a tiny bit slower, it is more foolproof when there are logical mistakes like the one mentioned here.
We also of course continue to add more tests and we verify the code with more tools and analyzers in order to find additional similar mistakes.
Multiplexed protocols like HTTP/2 have this challenge that there are many concurrent transfers going and they all have different life-times and with memory-unsafe languages, dangling pointer mistakes can indeed be fatal.
This is of course no guarantee that we do not have or will not introduce another use-after-free in the code now or later.
Again on the language
libcurl is written in C – a memory unsafe language. With a memory-safe language, this mistake could probably have been avoided.
We have worked on curl for almost thirty years, and have over this time manage to make a rather polished transfer engine. For the longest time there really was no memory-safe alternative that also allowed libcurl to be a low-level library available on hundreds of operating systems and several dozen CPU architectures. It even barely exist alternatives now.
We do not rewrite curl. Not into another language but also not in C. We are set to iterate, polish, improve, refactor over and over until the end of time.
Porting curl to another language (like rust) would be a monstrous undertaking that would be slow and introduce lots of new short to medium term problems. Not to mention that the existing curl team is not rust experts and that libcurl is currently portable to many more platforms and environments than rust itself is.
Release schedule
When this vulnerability was confirmed by the curl security team just hours after it was submitted to us on September 15. We immediately realized the significance and decided to rush the pending next release. However, we still wanted to be careful, follow the procedures and not create any further problems or mistakes by stressing it too much. That’s how we ended up just shortening the release cycle with two weeks. Down from eight to six weeks from the previous release. This allowed us to also merge and fix many more vulnerabilities and general bugs in the same release.
CVSS
We never provide CVSS for our published vulnerabilities as we don’t think we can do a job there. Others will provide them even for our flaws.
the 277th release 4 changes 42 days (total: 10,929) 281 bugfixes (total: 14,770) 476 commits (total: 40,084) 0 new public libcurl function (total: 100) 0 new curl_easy_setopt() option (total: 312) 0 new curl command line option (total: 278) 84 contributors, 58 new (total: 3,844) 45 authors, 28 new (total: 1,546) 24 security fixes (total: 239)
Security
This time we announce no less than twenty-four fixed vulnerabilities. So many that I decided to not list them individually here. Go check them on the curl security page.
Changes
The symbol formerly known as CURL_GLOBAL_WIN32 is now deprecated in favor of the more accurately named CURL_GLOBAL_WINSOCK. Used with the curl_global_init function.
SMB(S) support is gone. Neither curl nor libcurl support these protocols anymore.
The tool’s –no-clobber option got two improvements: 1) it now inserts the number into the file name as “-[number]” before the file extension if there is an extension. 2) It now tries many more numbers before giving up. Up to 9999.
Bugfixes
Over two hundred and sixty bugfixes landed in this release. Check them out in the 8.23.0 changelog.
Back in August I mentioned the new curl performance tests we have running. I figured it could be apt to return to this topic just to mention some of the initial outcomes.
When the team gets a new set of charts, graphs and plots that visualize something, like performance, they offer an excellent opportunity for us to try to make them look better. This new setup is no exception.
The performance tests have only been running for just a little over two months but they have already made us improve curl performance in several areas. Of course, for most transfers these changes won’t make many visible differences to users. This is more in the vein that every little bit counts and that nothing should run slower than it has to.
This is a list of some improvements that are included in the curl 8.23.0 release, to be shipped tomorrow on October 14.
faster base64 encoding and decoding
With a few different changes, the internal base64 encoding function is more than twice as fast, while base64 decoding is 40% faster.
faster URL encoding and decoding
Meaning percent encoding the octets that are not safe to use in URLs. The decoding function now runs more than twice as fast compare to before, while the encoding function is around four times as fast.
faster date parsing
Converting a date provided in plain ASCII text, as is used in for example cookie headers, to the epoch – number of seconds since Jan 1st 1970, is now more than twice as fast as before. Mostly thanks to completely replaced functions for week day, month name and time zone name lookups.
faster URL parsing
Parsing a full URL to split it up into separate components as well as confirming its validity is a core component of curl, and libcurl exposes this functionality in its API.
In a test with several hundred different URLs, the new version executes 20-30% faster than before – with an improved ability to return precisely what the problem was when the URL is considered invalid.
faster printf() calls
For portability and now historical reasons, libcurl has its own printf() implementation. This ensures that it always works identically on all platforms but it also makes it our job to make sure it executes as fast as possible.
Most printf() calls now run slightly faster (5-15%) because it handles “chunks” instead of single byte-by-byte at a time.
faster number parsing
We have a generic internal function in curl that converts a number provided in ascii to its binary version (for decimal, hexadecimal and octal). It handles 64 bit values, has overflow detection and supports a maximum. This parser now runs almost twice as fast as before thanks to a simple trick to avoid the boundary check for most loops.
smaller structs
The easy handle was 4256 bytes large two months ago, it is now 3064 bytes. About 28% trimmed off. One of these structs is allocated for every concurrent transfer done with libcurl.
There is also one multi handle allocated for each set of transfer. This struct shrunk from 900 bytes to 656: 27%.
The connectdata struct that is allocated once per connection libcurl handles, went down from 824 to 656 bytes: slightly over 20%.
fewer and smaller allocations
For the test case where we count all allocations necessary for the curl tool to download a single 512MB file over clear text HTTP://, it went down from 100 to 96 used allocations. Not too exciting perhaps but it is now really hard to squeeze this further!
Mostly thanks to the decreased struct sizes mentioned above, this use case of a single HTTP download now only use 126,875 bytes allocated at peak. Down from 130,622 bytes two months ago. Also quite difficult to trim further.
It should be noted that the download buffer is 102,400 bytes of this amount. If we exclude that buffer from the count, curl is using 15% less memory.
Easy to check
If you think you can speed up any of these functions, it is now very easy to check: the tests are there in the git repository, ready to be invoked by anyone!
The curl security team happens to also double as the curl core team. The small group of people who assess security reports and take project decisions.
The exact set of participants in this team of course vary over time, as this is a volunteer membership role without monetary compensation.
I decided to write this blog post to help show the light on some of my fellow curl maintainers. I think I often get too much credit and that curl is frequently called a one man show. It really is not and it has not been exclusively my project for many years. We are a team behind this.
As of October 2026 we are six humans in this team. Me and five fellow maintainers. curl would not have been close to what it is today without this team. These are the peeps I turn to first for everything hard, complicated or tough in the curl project when they need to be done in private first. In all other cases, public communication is preferred.
The team
(alphabetical order, excluding myself)
Max Dymond. Max made his first commit in the source repository over nine years ago. He has otherwise made perhaps the biggest impact with his fierce work on the curl fuzzers and dealing with fall-outs from OSS-Fuzz. Having excellent fuzzing significantly contributes to us writing better code.
Stefan Eissing. Having authored his first curl commit just five years ago, Stefan currently has his name on more lines of code when doing git blame on production code than any other individual, including myself. Introduced the pytest test suite in curl. Master of all things HTTP. Productive like few.
Dan Fandrich. Made his first recorded curl commit twenty-two years ago. He has been involved with everything and everywhere in curl. In recent years perhaps most emphasized in test infrastructure as he made the test suite run parallelized a few years ago. He also wrote and admins Test Clutch, which helps us monitor CI test results.
James Fuller. Has been involved with curl for more than eight years. James focuses on security and is our own master of CVE reservations. Primary maintainer of curl-container – images for Docker and others.
Viktor Szakats. Having authored his first curl commit twelve years ago he is now the second most commit author in the project. Lead maintainer of curl-for-win which creates reproducible, static, curl binaries for Linux, macOS and Windows. Viktor is the unparalleled champion of our build and CI systems but shows up everywhere. Apparently he never sleeps.
Invite-only
This group is invite-only and there is no documented set of requirements. You need a proven and established presence in the project, combined with a excellent knowledge of Open Source, protocols, networking and the curl project itself. Once you do, you might get invited to join. Not everyone accepts the invite when extended, and that is perfectly fine. It’s a lot of mostly thankless work without a paycheck.
The rest
1,545 people have authored at least one commit in curl. A typical year, more than 150 individuals author commits and at least ten people author more than 10 commits each. People come and go over time. Here’s a list of the top-100 authors.
Everything that improves curl is welcome and takes us forward. Even bug reports and mere suggestions on the mailing list can help us figure out things or improve features in ways previously not considered.
More than 3,800 people are named in the THANKS file because they helped us out, one way or another.
curl is a team effort. A giant team.
Steering the herd
Our job in the core team remains to steer the direction, to enforce boundaries, to lead by example (in addition to wade through an avalanche of vulnerability reports). To guide contributors, to review changes and try to make it even easier for more people to contribute.
Keeping top-notch quality while allowing and introducing newcomers.
On October 14 2026 we will ship curl 8.23.0. The next iteration in the never-ending series of version bumps from the curl project.
We always think of the next release as the best version we ever did – and this time is no exception. Decades of collected experiences and meticulous polishing has lead us to this.
Earlier than planned
We decided to shorten the release cycle this time, so that we can release 8.23.0 a few weeks earlier than what we originally planned. We took this decision after we received one particular vulnerability report that highlighted a rather significant flaw.
We will ship a new version with this problem removed, together with twenty-one other albeit less serious security vulnerabilities addressed.
Severity HIGH
In the curl project we only assign one of the four different severity levels on all CVEs we report (LOW, MEDIUM, HIGH or CRITICAL), as we basically don’t believe in CVSS scoring. We have only published two CVEs with severity HIGH since 2021, the most recent one being CVE-2023-38545; that could lead to a heap buffer overflow.
Now we are about to release another one: CVE-2026-92392.
All info will be revealed next week
All details about CVE-2026-92392 will become public in the European morning of October 14, 2026 in synchronization of the release of curl 8.23.0 which of course will have this problem fixed.
We will ship updated Rock-solid curl versions in sync with this.
For the safety and security of curl users everywhere (and frankly, all the infrastructure that uses curl), no details of this flaw will be made public before this date.
We will alert the distros@openwall mailing list and paying curl support customers about this problem (and the associated fix) ahead of time.
I will follow-up with a separate blog post after October 14 to describe this flaw in detail. How it can be triggered, why it isn’t quite the end of the world and what we do in curl to fix this and similar classes of problems.
Exactly twenty-five years ago today. Within all their fancy release presentations and videos there are barely no mentions of curl. In their technical notes page, there is just this short single line with not a lot of explanations:
Ever since then, curl has been an established component, present in every version and every install of macOS done through the decades. When Apple later created iOS, iPadOS, WatchOS etc they also adopted libcurl into their operating systems. Never to provide the API to users, but to empower their own applications and services. (But I have no specific date logged anywhere when that started.)
The first curl version Apple shipped in macOS was curl 7.7.2 which was released in April that same year.
Apple has never used a super recent curl version but they have updated it reasonably well I would say. Sometimes less good.
We are proud to have been a part of the Internet evolution all this time. We are happy that Apple, even if merely implied, has validated us and our way of doing things.
We have never worked with Apple, never received sponsorship by Apple, not had them as customers and except a few rare and mostly failed attempts there have never been any communication between us. We ship a freely available Open Source product that they use and bundle in their products. (It is their choice and right.)
This afternoon I had a meeting with IT people at a huge US power infrastructure company. They had found a libcurl.dll file in their C:\Windows\System32 directory and asked us for help to upgrade it. Their vulnerability scanner identified it as vulnerable to several publicly known vulnerabilities. Can we bump it to the latest version please?
No. We really cannot.
There are literally thousands of Windows applications that use libcurl. Many of them install a libcurl.dll file in your file system as part of their installation process and yes, some of them even put it in the system32 directory. They can optionally link with libcurl statically, which allows them to use the library and its API without using an external file. There are pros and cons with either method.
When libcurl is shipped as a separate DLL file, it is easily checked by for example vulnerability scanners and they may find that your Windows installation contains a libcurl version that contains known vulnerabilities. The system may even contain many separate libcurl installations, each potentially at different versions and containing a different set of vulnerabilities.
Not part of Windows
Microsoft ships curl as a bundled part of Windows since many years back, but they build with a static libcurl so they never ship any libcurl.dll file and therefore we know that the file does not originate from there. It is not part of the Windows installation. Something else installs it.
We can’t fix those
Whoever built that exact libcurl.dll file needs to be the one who updates it. It is next to impossible for anyone else to know or figure out exactly how that file was built – and getting it wrong will most certainly crash the application or cause other odd and unpredictable behavior.
Figure out who uses it
My advice: figure out which application that uses this DLL. With tasklist you can check which currently running application that uses a specific DLL, and I have been told there are tools that can scan executable files to find out which ones that use a specific DLL.
This is not something we can do.
We can still help
We can help application makers with advice, education and tricks on how to build curl the best and most effective way. We can even build or ship curl for them. We are leading experts on curl, networks and transfers.
How fast is “fast” and is it good enough? Does it run as fast now as it did before or was there a regression? What exactly needs to be fast? How fast is it?
These are questions that many projects and products face, and in curl we are no different. Yet, performance testing and comparisons are hard and full of landmines and time-wasting efforts. For many years we have occasionally brought up the idea of a performance test suite for curl only to shut it down again because the challenges seemed hard and no one was volunteering to do this.
This week it changed.
Let’s do this
I started out trying to find existing projects that host performance results for Open Source projects so that we could just feed our results something else and get great visualizations and data management. I did not find any such.
I then took a look at what existing tools there are for this purpose, and most pointers seemed to suggest that Grafana is a popular and maybe even a good solution to build something like this with. But man, that is a complicated machine and it felt more than a little overwhelming just figure out where or how to start with it. I decided to postpone that take as well.
Let me do this
I decided that instead of trying to do this the best and optimal way – I shouldn’t let perfect be the enemy of good – I would start out by doing the things I know how to do and take it as far as I can one step at a time. Something should be better than nothing.
Performance testing needs decently stable system conditions so that repeated runs produce reasonably similar results, when all involved factors remain identical. This is basically impossibly to accomplish using most cloud infrastructure since those are almost always shared with countless other users. At least on the cheap and free tiers we use.
We probably need our own dedicated hardware for this, but instead of trying to figure out where to get that and arrange for that, I would start by running performance tests on my own local development machine. I am a single user on this and it has many cores and runs decently fast. It should be good enough to get this going on.
I created a first shell script that updates the curl source code from git, it configures and builds it. Then it runs a bunch of tests, outputs a bunch of data and logs all the output in a single log file. I started out with a few simple tests. How fast does curl download a 100 GB file from localhost, how many allocations and how big allocations does it need for a single HTTP download?
My second script parses all the test log files from the previous builds and generates summaries and graphs for them. To make it possible for humans to see how the performance changes between builds and ideally to automatically detect when something changes more than what should be tolerated.
As I am a graph addict already since before, and that journey has taught me a little gnuplot, I decided that even while there probably are much better tools and fancy JavaScript things that could be used, I don’t know them and learning them now is an endeavor I rather avoid. So I stick to what I know and can get results with quickly.
A third script is invoked from a crontab every twenty minutes, sets up some variables and invokes the runner script.
Once the basics started to work, I showed my curl friends the early versions and I soon created a new git repository for the code.
It’s live baby
After a little more poking, I soon made my locally produced performance test summary get packaged and automatically transferred to the curl website after each build, and voila, the first public curl performance tests were live and public.
Getting this data available immediate triggered curl developers. It only took hours until we had the first proposed changes to improve some numbers, and soon we had a few merges to that affect. Visibility really helps!
The performance numbers we get are still varying to a certain degree, partially of course because I still use my machine for my daily development things, but also because most of them do real (localhost) networking and that is by its nature a little… varying.
The system builds and runs a new round every twenty minutes and it does that using the latest commits from git. This setup makes it sometimes run many rounds on the same commit and it might also mean that it sometimes updates and get several new commits at once, so it might skip a round for some commits. I might reconsider this design later, but since it is still a twenty minute time window, the number of commits is still limited.
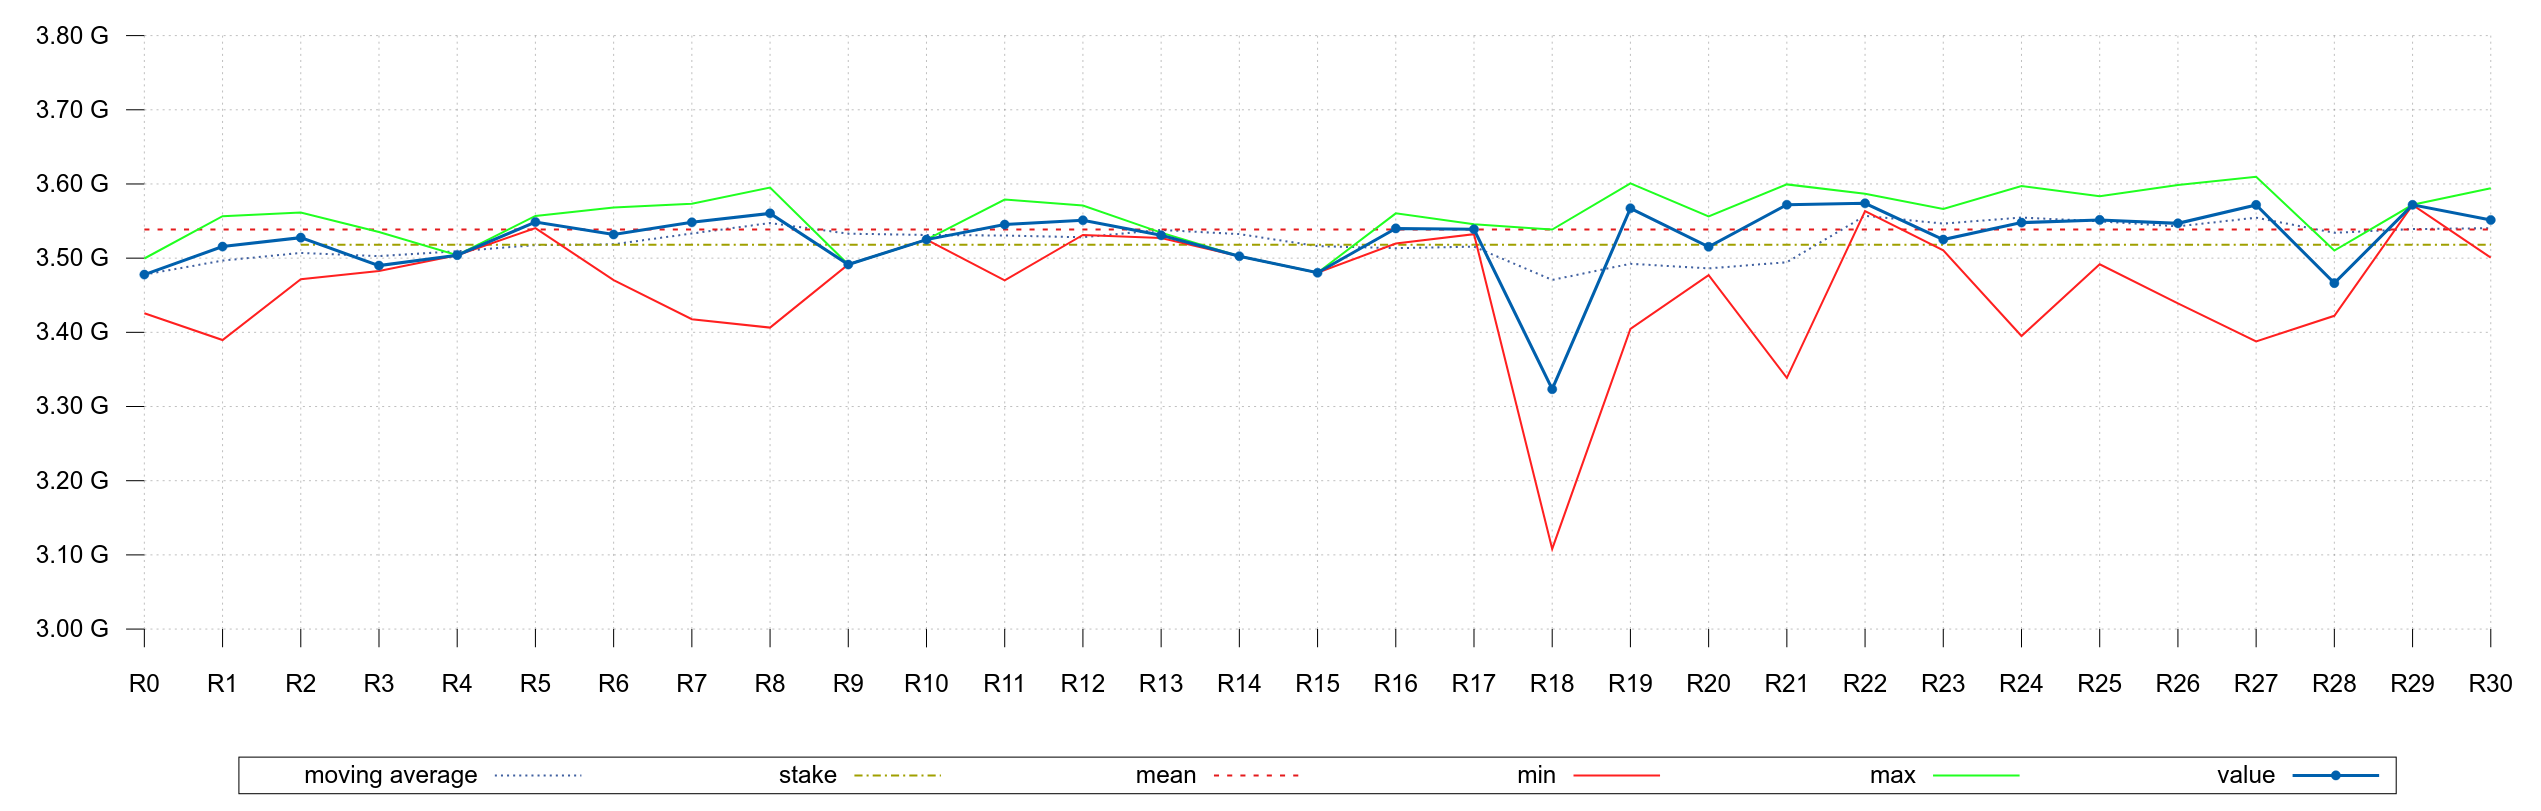
When the script makes multiple build rounds on the same commit, it accumulates the numbers and for the graph it stores the maximum, the median and the minimum value. It helps show the variation per commit and allows us to cram more into the graphs. It is still early days, but there will be a maximum limit to how many commits that can be displayed in a single graph and still be helpful.
HTTP/2 parallel download speed through 261 builds spread over 31 build rounds
Distribution
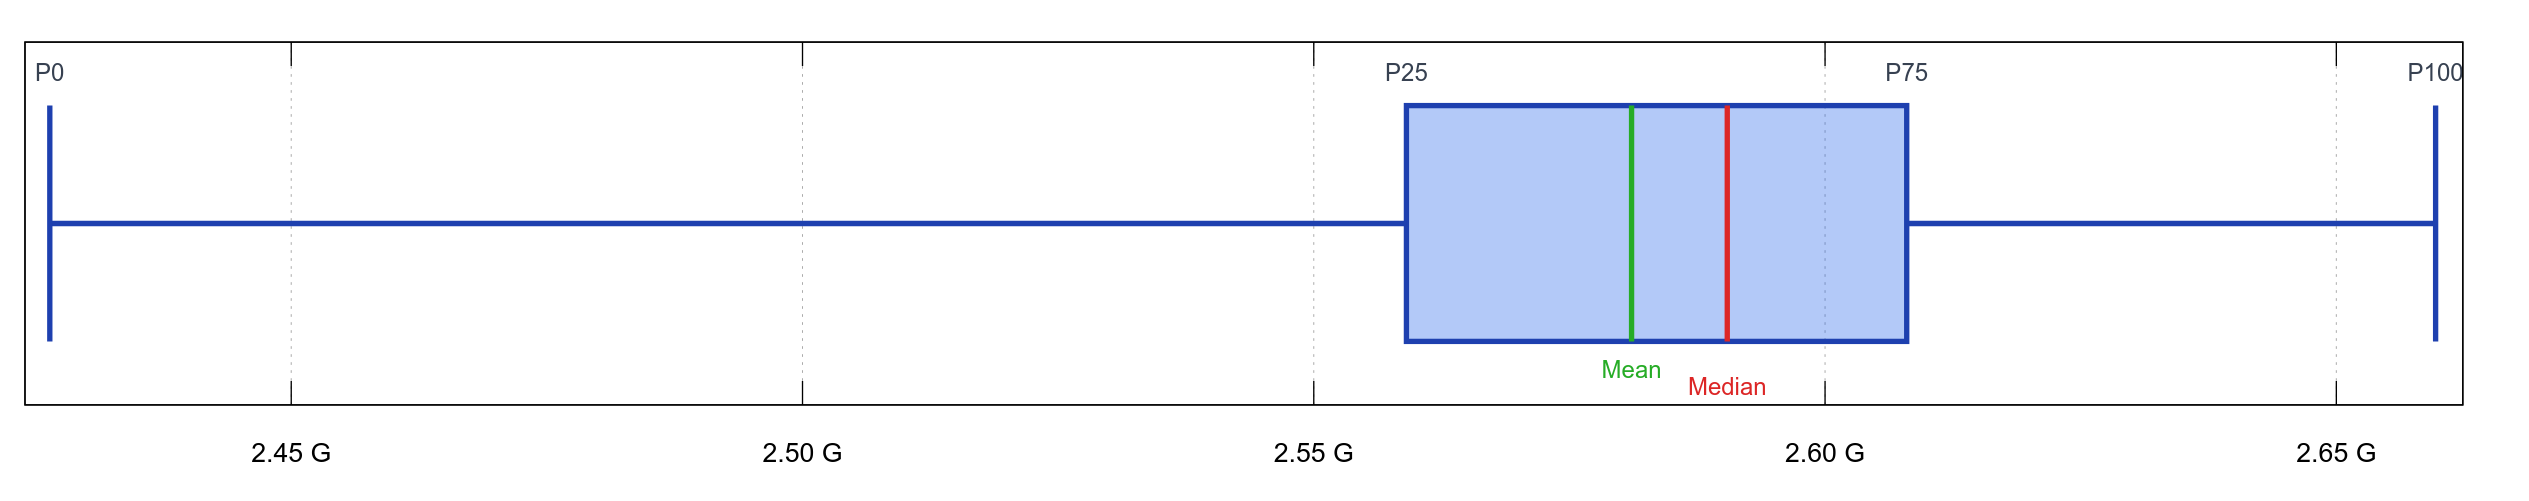
To help visualize the distribution and data spread per test, I created a separate illustration that shows the minimum, maximum, P25, P75, medium and mean values in a Box-and-Whisker Plot.
A Box-and-Whisker Plot showing the HTTP/2 parallel download speed data distribution.
Changing conditions
An obvious downside with me just storing build logs in files, is that it will not scale up to the millions. I did however decide that I’m not designing this system for that. At least not now.
Performance tests are highly specific and dependent on the exact machine it runs on, the exact third party libraries and their versions that are used, the other components involved in the tests, such as the servers, and more.
I expect that we will change conditions for the tests every once in a while that makes it hard to compare the current numbers with past numbers. Therefore I think the performance test numbers and values are primarily useful in the short term. To help us spot if we land something that subtly and unintentionally degrades something.
Stakes
To detect extremely slow and long-term changes in performance and even making sure we can better survive wiping all the existing build logs etc, I introduced a concept I call stakes. As in a stake pole. A marker. An arbitrary threshold set manually for each specific test. This value can be used to measure performance test results against, now and later. As conditions change and maybe something makes the results go up or down and we are fine with those changes because they are motivated and expected, then we just change the stakes.
If it works out, I might try to have the system automatically detect and maybe highlight tests that deviate too much from its set stake (at least if done in the wrong direction) . It could be a signal that something bad was merged.
Balances
As with everything in life, things are often balanced out. We already ran into this when we eagerly merged several changes to reduce the number of allocations done for a single HTTP download, only to realize that one of the optimizations we did had the side-effect that it expanded the size one of the main structs maybe a little too much…
Improvements in one area might come at an expense in another. With sufficient tests and data we can improve curl for users, and at the same time make sure that our changes don’t come with a cost we are not prepared to pay. Exactly how to make the balance is of course a question we need to deal with, discuss and decide. Possibly for every change we do!
The tests
As I write this, we have 24 tests and a full test round completes in about six minutes on my machine.
We can of course do multiple builds using different hardware, different operating systems, different build options, different third party libraries and different test servers to check more angles of performance, and I am certainly open for and prepared to do that going forward. I will however first let this single-flavor run for a while so that we get more data, get a change to tweak it and make it as usable as possible for curl developers.
As with everything there is no end to what we can make this do. This is a start. I sure we can take it further as we move along. In particular if people join in and help out. Both with ideas and proposals for visualizations, graphs and new tests to add, but also with actual pull-requests and code.
Build volumes and graphs
Over the last year, we have merged, on average, about 10 commits per day. If we keep this pace up and this performance test setup can show 100 build rounds conveniently into a single graph, that is just ten days of development. Probably not enough.
Once we reach one hundred builds or so in the first graphs I need to consider adding separate long term graphs that use select data-points to display data development over a longer time. Some googling told me the Largest-Triangle-Three-Buckets, or LTTB for short, is a fine algorithm to use for this. I now do a separate “long term” graph that “downsamples” the full range down to something that can be shown in a reasonable way. I suppose we will see properly in the future how this works.
Spotting change
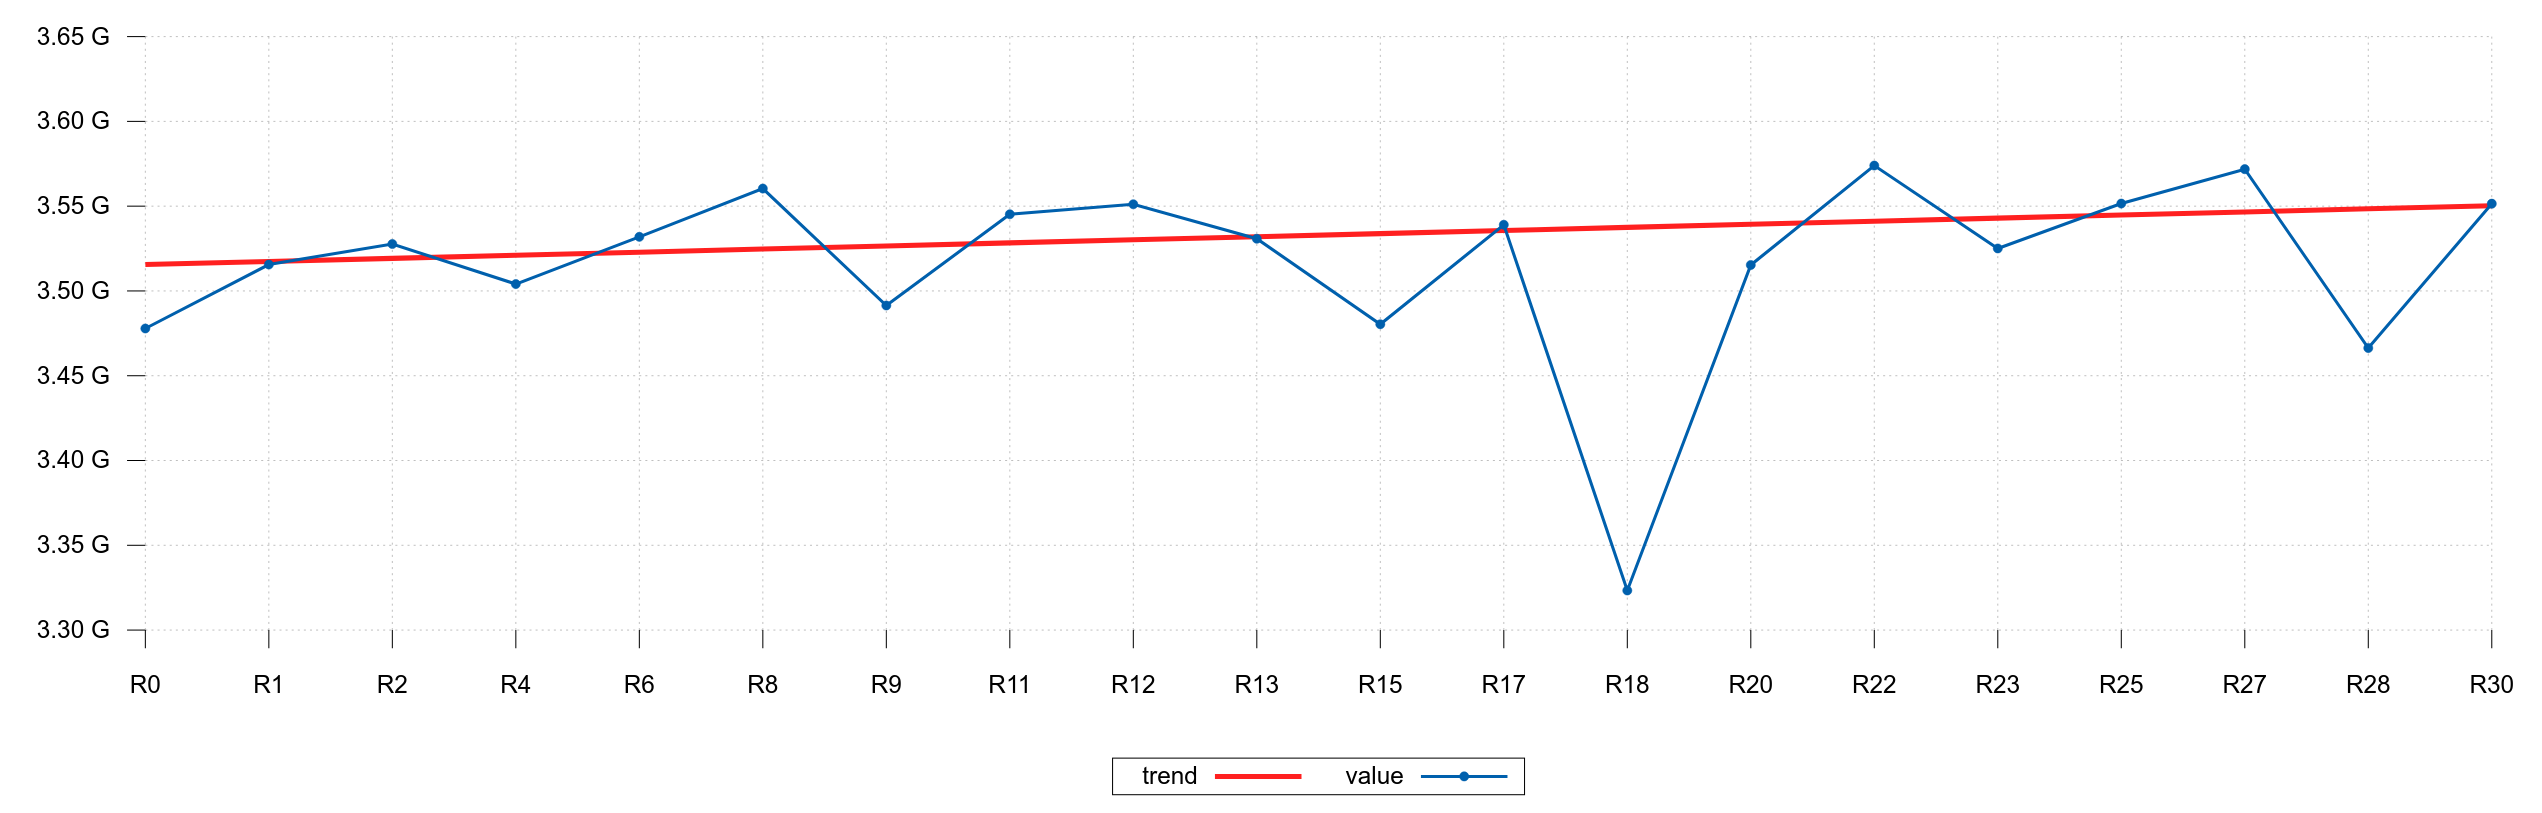
The stake thing I mentioned is one way to help us spot gradual performance changes over time. Another googling told me that there’s a Mann-Kendall Test + Sen’s Slope algorithm to use to identify trends in graphs like this and it can be used to plot a trend. It might work as a helper to better identify… yeah, the data trend for each test.
The HTTP/2 parallel download speed trend at a specific moment
Developing
This setup has only existed for a few days. There is lots to do, lots to learn and much more to experiment with.
Your comments, help and pull-requests will be appreciated!