Tag Archives: Security

“ignore the slop”

Lots of people who are against the use of AI for all its ethical and inherent issues tell me this. Just ignore it. Don’t let big AI control us.

The “slop” they refer to is anything created that involved an AI, and in our case (the curl project) it is in particular vulnerability reports.

“Ignoring the slop” cannot be done and it doesn’t help. Vulnerability reports created with the help of AIs point out actual problems, and sometimes vulnerabilities. Ignoring real vulnerabilities because they were found by AI does not make users safe and secure. It makes them vulnerable. We don’t want that.

I personally don’t refer to this as AI slop because the reports are typically accurate and correct, even if much too wordy. I think “slop” implies that it is wrong, misleading or otherwise bad content.

One can certainly object to the use of AI, but when we get real vulnerabilities reported and proven, we cannot in good faith pretend they don’t exist just because we think the tech involved in digging them up is questionable. That would be a disservice to, or even betrayal of, our users.

We make curl secure for our users.

Obligations

An Open Source project typically gives no guarantees at all, so there are no legal requirements that force us to fix flaws.

We are however a project with high goals of quality and stability and we would jeopardize our name and track record if we now would stop delivering on that. Also, a few of us involved in the project also sell curl related support and services, where at least part of that means providing secure curl releases, so we still have this contractual obligation to a set of customers. And they wouldn’t be customers in the fist place if the Open Source project didn’t already have the proven quality track record.

So no, we really cannot ignore vulnerability reports.

The slop is gone

A sizeable portion of users seem to still believe we still suffer from a lot of made up and hallucinated reports by these AIs. We really don’t.

Almost all the stupidity and lies we saw in the vulnerability reports made by AIs in the past have ceased. Since spring 2026 the slop reports are practically gone. Our current challenge is much harder: high volume, high quality.

AI talks too much

They always use too many words. Every report is now hundreds of lines and the explanations are convoluted and detailed (and often repeat themselves multiple times).

In a good report, the human writes a first paragraph explaining the problem briefly and then they submit the full report. It’s annoying when the reporter surrender everything to the AI, including the communication part.

The AIs are also still bad at figuring out exactly where the line is between a bug and a vulnerability, and if it is a vulnerability, what severity it is. This is not a surprise though, as this is also the case for human reporters.

A good trend is that they often produce good reproducers or proofs of concept helping to trigger and prove the problem/vulnerability. That was a really complicated part of the reporters’ work back in the day, now it’s just a prompt or two.

Everything is with AI now

These days, like within the last few months, we have received hundreds of vulnerability reports submitted to curl and every single one had AI involved to some extent.

It is generally easy to tell on the language and the length and details of the report.

Do minor curl vulnerabilities in the open

The curl project has decided to alter its vulnerability disclosure program procedure and starting October 26 2026, we insist that all vulnerability reports submitted to us that are deemed to be severity LOW or MEDIUM should instead be submitted as issues in our GitHub repository.

Only vulnerabilities deemed to be HIGH or CRITICAL will be kept private in the HackerOne tracker.

Security researchers in doubt can still submit the issue on HackerOne and we can tell them what severity we deem it to be. Over the last few years, over 90% of all submissions could quickly be assessed to be less than HIGH.

Issues submitted to HackerOne we deem are LOW or MEDIUM will be requested to be resubmitted on GitHub and will be closed as informative on HackerOne (and publicly disclosed).

Avalanche survival tricks

This policy change is entirely triggered by the current avalanche of vulnerability reports that keep pouring in. We see no end to them and we do not anticipate this flood to decrease within the next several months.

We are struggling as a project as all key maintainers feel strained, overloaded and brought to the brink of what we can muster. We must act to survive. This is our next step in a survival strategy. It might not be our last. We aim to not drown.

Public vs private

By opening up the process we allow the whole world to participate. Both in the assessment and understanding of the report and claimed vulnerability, but also in the creating and writing the advisory and figuring out details of when the issues was introduced etc.

Ideally we get better help to make sure the fix is the correct one, that it fixes the problem, and any other related problem that is similar and that it does not miss a related problem sitting next to this.

An obvious recent trend is that the moment we announce a new set of CVEs and their associated fixes, there is an army of AI-using researchers who throw all those at their models and harnesses to find similar mistakes or omissions in the fixes. By taking this process to the public all the way, ideally we get more help to do that scrutiny better before we ship releases.

We recognize that the amount of work needed per received vulnerability report does not shrink by doing them in public, but we think that we might share the burden among more people easier, and we hope that lessons and documentation brought up in these discussions will be easier to spot and learn from.

The open process can also allow distros and other users of curl to keep up with security fixes earlier and better.

The risks

Several people have suggested there is a risk that researchers mistakenly submit severity HIGH issues on GitHub thinking they are LOW or MEDIUM. It is basically unheard of that a researcher would have understated a reported problem so I consider that a low risk scenario. Also: there was already before this a risk that someone would submit a vulnerability report in the public, it is not a new risk.

Handling some vulnerabilities in the public of course makes the immediately available for both good and bad people. This policy will give bad people a slightly longer window of opportunity to exploit weaknesses at the expense of existing curl users. That is unfortunate but we see no way of avoiding this. We limit this practice to less than HIGH for this reason: at least these problems are not terrible.

Severity LOW

We have discussed simply dismissing all severity LOW issues, but within the CVE program there is an appeals process and if we don’t hand out a CVE to an actual vulnerability, then someone else will do it. We thus cannot ignore true vulnerabilities, or they will come back to bite us nonetheless.

We can however resist and refuse silliness and I personally aim to deny and decline more vulnerabilities harder on the basis that they do not actually hurt any users or existing applications.

Crazy combos

A clear trend these days is that many newly reported vulnerabilities are figured out by AI models that create crazy sequences or option combinations that do something unexpected, but the sequence is something that aren’t likely to ever be used in the real world, or the unexpected that happens is something that occurs every time so applications doing this would spot the problem immediately. I.e problems that have almost no risk to actually trigger in the real world. We save no users by insisting on doing the CVE dance for those issues. We only get work for ourselves and a whole world that has to act on them.

Flow control it

There is an almost infinite number of combinations you can use libcurl’s many options, protocol mixes and flexible API to do things that might not be clearly documented and the AIs will continue to try them all and together with the humans driving these checks they are super eager to treat every minor discrepancy as a vulnerability. We can’t continue down this spiraling path with our sanity intact.

We don’t have the bandwidth, manpower or even will to handle a never-ending vulnerability reporting stream at this pace. I believe few software projects can stand this kind of prolonged high volume deluge for extended periods. Something needs to give way.

How to assign severity

We only use these for levels in the curl project: LOW, MEDIUM, HIGH and CRITICAL. Often we refer back to recently managed vulnerabilities to see how we judged them, but we also provide a set of basic guidelines. I’m sure we can also make them better and clearer.

A UAF turned RCE

In the curl 8.23.0 release we shipped a fix for one of the worst vulnerabilities in curl in a long time. We grade it severity HIGH. It is known as CVE-2026-92392 with the title HTTP/2 upload Use-After-Free.

This post explains the bug, what the problem can lead to, and something about why it happened and what we have done to make it harder to introduce a problem like this in curl again in the future.

This is a much simplified explanation. Please refer to the original report for all the details and the full reproducible Docker image for all the low-level fun and education you could possibly want. I highly recommend doing that; the report and the reproducible are awesome.

Use-After-Free

It is a use-after-free, which is a classic problem in memory-unsafe programming languages, like C, where we erroneously have a lingering pointer left, pointing to memory that is already freed, and yet we use that pointer and the memory it points to.

This family of errors is especially bad when a malicious actor can affect the content that gets stored into that memory area that is still used even though it was freed. Tricking the program to do something unintended.

HTTP/2 is multiplexed

This problem involves HTTP/2. HTTP/2 is a multiplexed protocol, meaning that it handles multiple logical transfers over the same physical connection. curl needs to keep track of a number of transfers at the same time, and when data arrives or is to be sent off, it needs to keep things apart appropriately.

Handles

For every transfer done using libcurl, the application creates and sets up a dedicated handle. We call it an easy handle. This handle is kept around for as long as the transfer is in progress, and the application can close and free it once the operation is completed. When doing multiple transfers, multiple handles are used.

libcurl also has multi handles, which is a super handle type that holds any amount of easy handles. This handle, and the corresponding multi interface, makes it possible to drive any amount of concurrent transfers. A transfer done with libcurl always has at least one multi handle and one easy handle. (Sometimes the multi handle is hiddenly used under the hood.)

The setup

In order to trigger this problem, we need an application (such as the curl command line tool) to do an upload over HTTP/2 to a server. By default, libcurl negotiates HTTP/2 when a HTTPS:// URLs is used and the server agrees.

When the upload has started, the server pauses the send by zeroing the HTTP/2 window size, returns a piece of the response and then it resets the stream, which shuts down the transfer – but not the connection. curl then correctly pulls down the entire transfer, but it accidentally leaves a lingering pointer to the involved easy handle.

When the application finds out that the transfer completed (with an error), it subsequently frees the easy handle and then, and here comes the problematic part: cleans up the multi handle.

The mistake

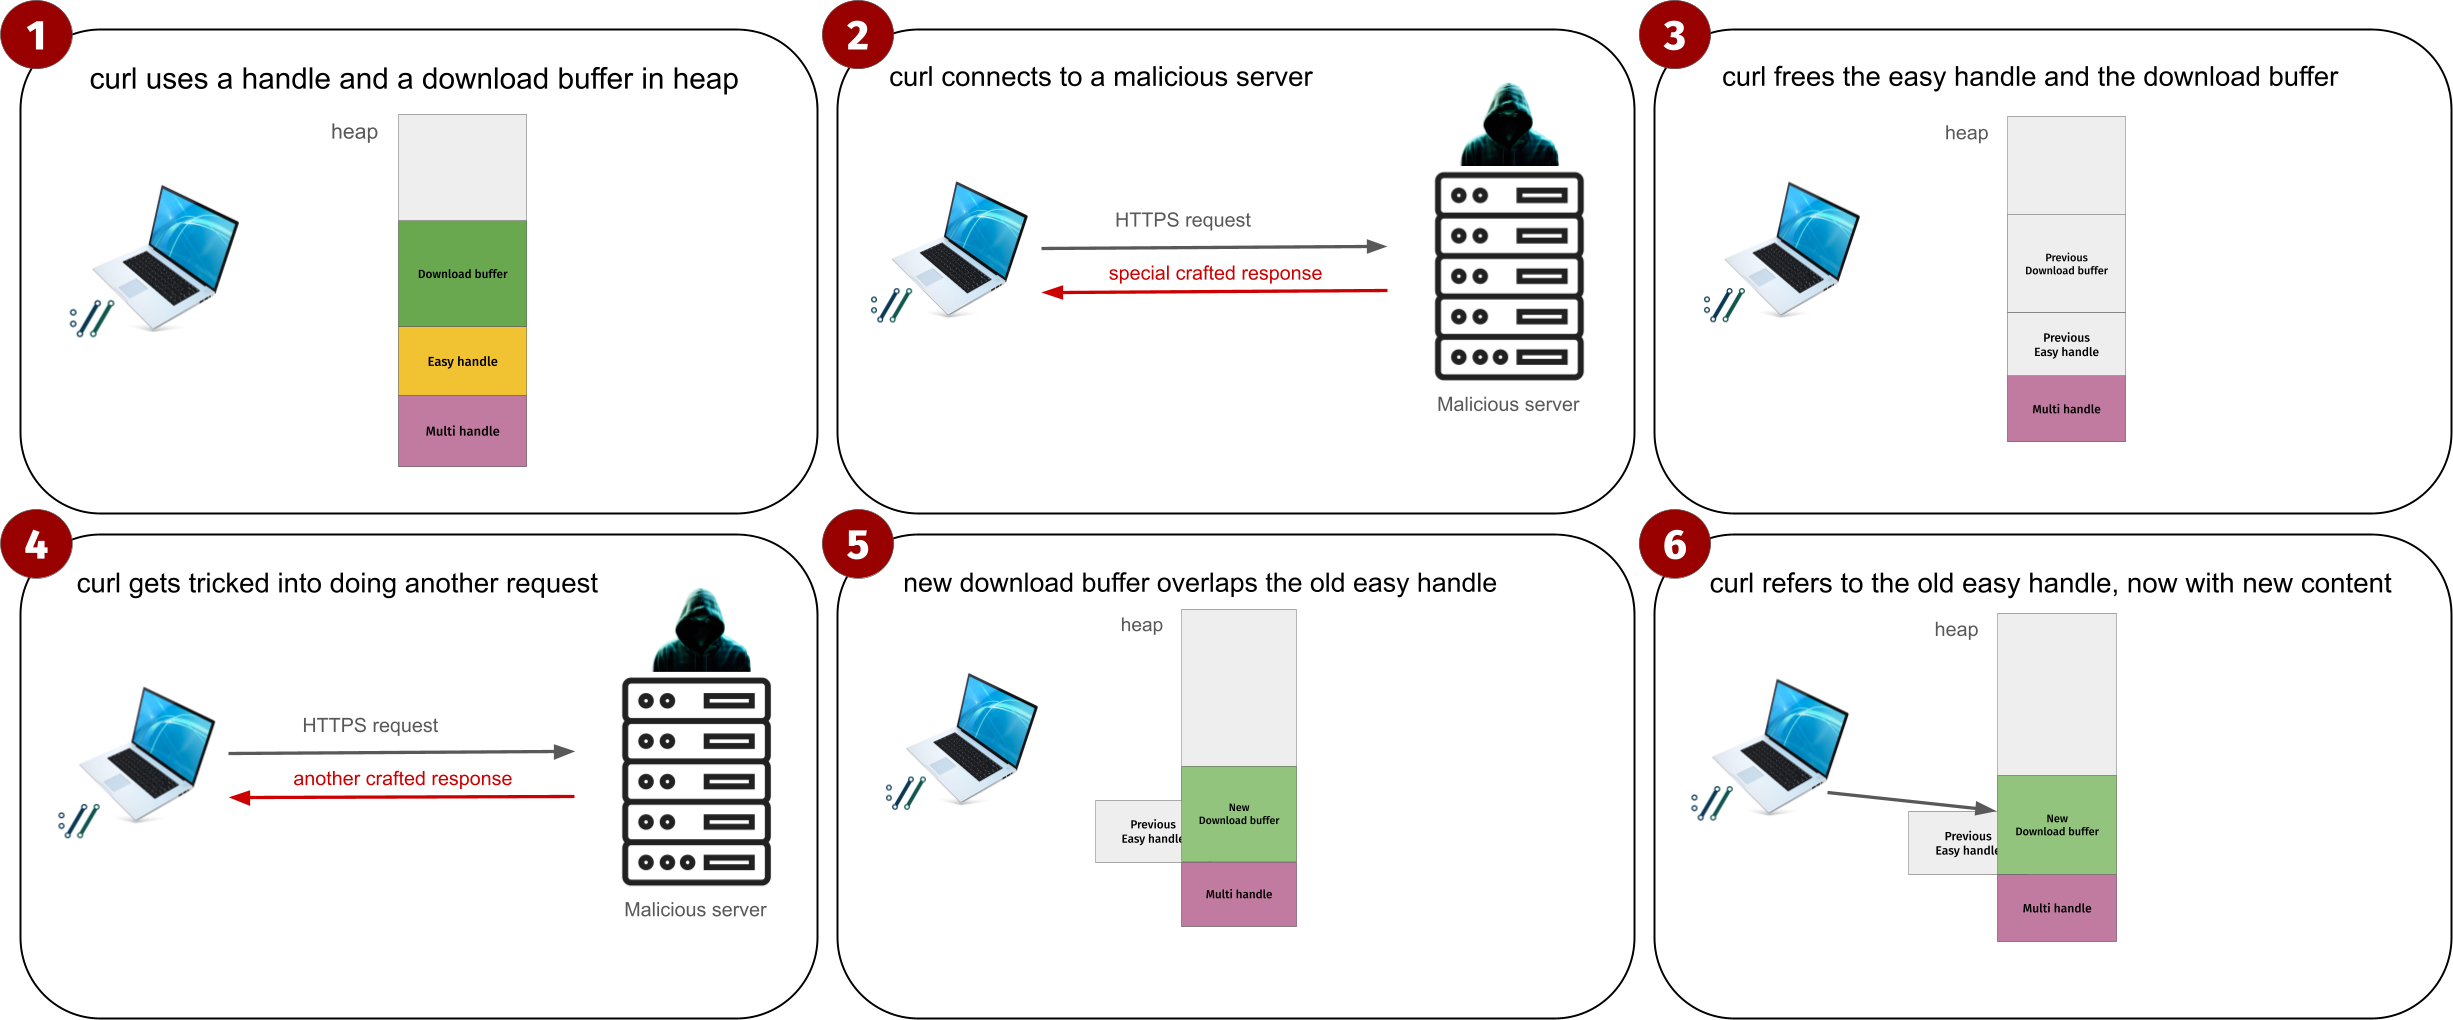
At this point, the easy handle was just freed but there is still a reference to that handle. When libcurl shuts down the multi handle, it misunderstands the situation, allocates memory to download data into, finds the still dangling pointer and manages to download data from the server that ends up in the very same memory previously used for the easy handle.

In this process, it sends off a request that leaks internal client details, which includes information about local addresses, which is crucial. Modern operating systems use Address Space Layout Randomization (ASLR), so a server needs this clue in order to generate a good attack payload.

Subsequently, when libcurl deals with this received data (using the handle the dangling pointer points to) in the download buffer, it uses a function pointer that now has been modified by data just downloaded from the server, and then it runs remote code.

An illustration

Here’s a simplified 6-step illustration.

Conditions to trigger

In order to actually successfully execute remote code, lots of several specific conditions need to be met and we deem it extremely difficult to meet these requirements in the wild, which is why we decided this is “only” severity HIGH and not CRITICAL.

  1. The victim needs to actually attempt to upload data to a malicious server, meaning that the server certificate must remain valid.
  2. The size of the upload needs to be roughly the right size (~135KB)
  3. The attacker needs to know curl’s architecture to generate and deliver the right code
  4. The attack requires a specific sequence of allocations and allocation sizes so that the data from the server ends up in the right place (from the attacker’s view). This pattern differs between Linux distros, libc versions/flavors, TLS certificate bundles, libcurl using applications and more.
  5. nghttp2 and OpenSSL/TLS 1.3 behavior, including allocation effects around session tickets
  6. The payload storage area is small (around 23 bytes)

The most likely outcome of an attempted attack is rather just a crash. We estimate that the chance for a successful attack is slim.

How was this found?

This problem was found and reported by Luna Tong at Anthropic using their new OSS Scanner. Presumably this involves their AI models.

How do we fix this?

In general we have over the last few years been working on reducing the amount of internal pointers to handles that needs to be correct, and instead we store transfer identifiers that we look-up on demand. While this is a tiny bit slower, it is more foolproof when there are logical mistakes like the one mentioned here.

We also of course continue to add more tests and we verify the code with more tools and analyzers in order to find additional similar mistakes.

Multiplexed protocols like HTTP/2 have this challenge that there are many concurrent transfers going and they all have different life-times and with memory-unsafe languages, dangling pointer mistakes can indeed be fatal.

This is of course no guarantee that we do not have or will not introduce another use-after-free in the code now or later.

Again on the language

libcurl is written in C – a memory unsafe language. With a memory-safe language, this mistake could probably have been avoided.

We have worked on curl for almost thirty years, and have over this time manage to make a rather polished transfer engine. For the longest time there really was no memory-safe alternative that also allowed libcurl to be a low-level library available on hundreds of operating systems and several dozen CPU architectures. It even barely exist alternatives now.

We do not rewrite curl. Not into another language but also not in C. We are set to iterate, polish, improve, refactor over and over until the end of time.

Porting curl to another language (like rust) would be a monstrous undertaking that would be slow and introduce lots of new short to medium term problems. Not to mention that the existing curl team is not rust experts and that libcurl is currently portable to many more platforms and environments than rust itself is.

Release schedule

When this vulnerability was confirmed by the curl security team just hours after it was submitted to us on September 15. We immediately realized the significance and decided to rush the pending next release. However, we still wanted to be careful, follow the procedures and not create any further problems or mistakes by stressing it too much. That’s how we ended up just shortening the release cycle with two weeks. Down from eight to six weeks from the previous release. This allowed us to also merge and fix many more vulnerabilities and general bugs in the same release.

CVSS

We never provide CVSS for our published vulnerabilities as we don’t think we can do a job there. Others will provide them even for our flaws.

Twenty-two pending curl vulnerabilities

On October 14 2026 we will ship curl 8.23.0. The next iteration in the never-ending series of version bumps from the curl project.

We always think of the next release as the best version we ever did – and this time is no exception. Decades of collected experiences and meticulous polishing has lead us to this.

Earlier than planned

We decided to shorten the release cycle this time, so that we can release 8.23.0 a few weeks earlier than what we originally planned. We took this decision after we received one particular vulnerability report that highlighted a rather significant flaw.

We will ship a new version with this problem removed, together with twenty-one other albeit less serious security vulnerabilities addressed.

Severity HIGH

In the curl project we only assign one of the four different severity levels on all CVEs we report (LOW, MEDIUM, HIGH or CRITICAL), as we basically don’t believe in CVSS scoring. We have only published two CVEs with severity HIGH since 2021, the most recent one being CVE-2023-38545; that could lead to a heap buffer overflow.

Now we are about to release another one: CVE-2026-92392.

All info will be revealed next week

All details about CVE-2026-92392 will become public in the European morning of October 14, 2026 in synchronization of the release of curl 8.23.0 which of course will have this problem fixed.

We will ship updated Rock-solid curl versions in sync with this.

For the safety and security of curl users everywhere (and frankly, all the infrastructure that uses curl), no details of this flaw will be made public before this date.

We will alert the distros@openwall mailing list and paying curl support customers about this problem (and the associated fix) ahead of time.

I will follow-up with a separate blog post after October 14 to describe this flaw in detail. How it can be triggered, why it isn’t quite the end of the world and what we do in curl to fix this and similar classes of problems.

What the bliss taught us

At this exact moment curl’s summer of bliss 2026 ends.

We (the maintainers of curl) took the entire month of July off from vulnerability reporting and in this post I will try to explain how this went.

(If you feel like skipping the wordy blab below, the single word answer is: fine)

This was possibly our best project decision in a long while.

Zero vulnerability reports

Already before this, we have been refusing to answer emails about vulnerabilities. Partly because we can’t keep track of them that way but even more so because it makes it much harder to properly disclose and publish the entire report sequence after the fact.

On our Hackerone page we informed visitors that we were on pause and that they could come back in August.

We had I believe one vulnerability report sent to my private email address in this period in spite of that messaging, but for all intents and purposes this worked out exactly as good as we hoped it would. I just ignored that email. That was easy.

Bliss

The effect was almost immediate. Just a few days into the bliss, my fellow curl maintainers all agreed with me that we felt a sense of relief, of vacation and that a load had been taken off our chests. We felt free, unchained, and now suddenly able to do what we wanted.

We could now spend time reviewing some of the queued up pull-requests for features and changes we like. We could suddenly again work on code in areas we had been leaving behind lately as vulnerability reports sucked all the air out the room. We polished details on the website, we found document gaps to tighten. It felt like the good old days again. The fun days. We got reminded why we do Open Source and how fun it is.

We took time off, saw some other corners of the world and enjoyed some time away from the keyboards.

We truly healed and re-energized.

CNA

Before we took off on the bliss, we were informed in clear terms that the CNA rules (we are a CNA) mandate that we must respond within 72 hours for some critical vulnerabilities so we can’t just ignore them. I told them sure we can, but in the worst case our “root” could do some emergency assignments. I figured the risk was minimal and it turns out I was right, Nothing like that was needed and no CVE assignments were necessary during the bliss.

Customers

I got a curious question or two from existing support customers on how the bliss would affect them, but that was easy: it did not affect them. Now, post-bliss, I think they all can confirm that it really did not.

New customers?

As I promised to keep up the contact with and support for paying customers even during the bliss, you could possibly imagine that this would have been an incentive for worried commercial curl users out there to sign up for support contracts.

This did not happen – at all. By this I think we should conclude that (commercial) curl users were not worried either.

The outside world

Lots of fellow open source maintainers and most people in my surrounding have been super positive and downright supportive of our taking some time off. I can’t recall having receiving a single negative comment about the curl summer of bliss!

Fellow blissers

I was moved to see that several other Open Source projects followed our example and also took some time off in order to recharge and relax. In addition to giving us a little vacation, it helps sending a signal and a reminder that Open Source is to a large extent done voluntarily and even maintainers need a break at times.

Major incidents?

Have we opened ourselves up for dangerous attacks and flaws now? Have the bad guys an edge on all curl users out there now because we lived in bliss for a month? We don’t know yet, but it would surprise me.

Queues

During this slow-down, we slowly got more open issues and pull-requests lingering on GitHub than usual. No surprise there. Once we started to come back to life again, we have since managed to return them back to the normal amounts.

Flood gates

Yes, there is an obvious risk that there are now a whole range of queued up reports that will hit us in a short period time as we open up for vulnerability reports again. Presumably the risk for duplicates among these reports should also be significantly higher than usual. I suppose I need to do an update post in a month or two and let you know what happened.

We always treat vulnerability reports and project security with topmost priority and we will continue to do so. We will simply work with what we have and make sure our users and by extension, the world, are safe.

Since I am a member of a few other (non-curl) security teams that did not have a summer of bliss, I have seen that the flood of vuln reports have not really slowed down so it might depend a lot on the details of each specific project.

Some emails were read

All individual curl maintainers of course handled this gift in their own ways. We did not all just disconnect to sit on a remote beach for the whole time. Some of us did that part of the time, but we mostly enjoyed the lower stress level and the absence of pressure. It was mentally relaxing. So, even if some of us kept up with emails, occasionally responded to issues or even submitted some pull requests of our own, it was still vacation. It was still blissful.

Rebliss?

Will we do another summer/winter of bliss? I think yes. It was simply great, with virtually no downsides for the people involved but instead lots of positiveness. Ideally a reduced workload going further will remove the need for another one, but it is not easy to tell what the future holds.

Just transfers

After all, curl just does transfers. Fast. Reliably. Secure.

Do excellent vulnerability reports

Over the years, we have received, read and handled way over one thousand vulnerability reports filed against curl. We have seen most kinds.

It is time for me to try to help future reporters by providing a short guide on how to submit a truly excellent vulnerability report to an Open Source project.

Researchers

We tend to call everyone who reports a security problem a security researcher, because by the act of the submission itself they fulfill the definition. There are however many different kinds of people who submit reports; from the most rookie youngster with limited experience, to the multi-decade experienced senior in the field.

Most reports submitted to a project like curl come from reporters who never submitted anything to the project before and are completely previously unknown. Many reporters use hacker handles or pseudonyms, so there is not a lot to learn about the person behind the report either. We don’t know the reporters’ age, experience level, employer, sex or on which continent they live. But also: none of those things matter.

When you submit a vulnerability report, consider telling the project how you want to get credited, should they consider your report real.

There is a potentially almost unlimited amount of security researchers that can find problems in a project. The project receiving your report only has a limited small number of overloaded maintainers that take care of the reports. Consider this imbalance. Make your report as easy as possible for the team to manage.

Finding

To us maintainers who receive a steady stream of vulnerability reports, it rarely matters exactly how the problem was detected. Whether you fell over it by accident, you found it by reading every single line of source code or if an AI pointed it out to you, it has little relevance to the security team. The team primarily cares about if the problem is real and if it is, how serious the impact is.

Really?

If the problem is documented, then it likely isn’t a vulnerability. This is a common theme in curl: people report that they can find something strange or peculiar to happen when they do something, only to have one of us point out that the action is either documented to have that side-effect, or the action was done in spite of clear warnings in the documentation.

To make a good vulnerability report, you should make sure you understand what the software is supposed to do – and what the documentation says its limitations and conditions are. A good Open Source project has those things documented.

Where

Figure out where and how to submit your report. If you found several problems, it is considered polite to ask the team how they want to receive the rest. As separate individual submissions or maybe as a curated list. Perhaps paced at a slow rate to avoid overflow.

Never circumvent the submission method suggested by the project. That is impolite.

Consider the initial submitting of the issue to be the first step in a multi-step communication process with the project that will continue for as long as at least one of your reported issues has not been resolved or dismissed. This can be days, weeks or in some cases even months.

Expect responses and follow-up questions. Be prepared to clarify, expand and maybe provide more code and reasoning. Remember that you submit vulnerability reports in order to help and improve the project.

Report

These days people like to create enormously long and detailed reports that have all the details, often explained three times and with several embedded lists using bullet points describing impact and providing more or less good analysis attempts.

Your first paragraph of the report should be a human-written, brief explainer of what the problem is and what badness it leads to. You should be able to explain that in just a few sentences. It is a reality-check, because if you can’t do this, if you don’t understand the flaw enough yourself to write such a paragraph, then you have homework to do. Figure it out, then come back and write the intro paragraph.

Having a quality intro saves a lot of time for the security team receiving your report.

Be aware that the Open Source project you contact may be overloaded, on vacation or seeing your report as yet another duplicate they already saw reported seven times.

Be helpful and respect that you add a load to a small team that probably consists of volunteers working on this in their spare time.

Even if you have used a lot of or just a little AI when finding the issue and writing up the report, you must make sure that you communicate as a human. With your human communication skills.

Reproducer

Your report should contain a reproducer. Ideally a fully contained and stand-alone script or source code that the security team can build and run to see the vulnerability trigger.

A reproducer helps prove to the team that the problem is real or maybe already an accepted risk or behavior. It is also convenient for the developers to first understand and reproduce the issue, and then they can convert the reproducer into a project test case for the pending fix.

Without providing a reproducer in your report, you instead push that work to the receiving end. We still need the reproducer. We still need a test case.

Patch

Provide a patch for the problem.

If you can figure out a way to fix the code to make your finding no longer trigger, that is great information for the security team and such a patch usually helps them understand the issue better and get a speedier result. It reduces the load.

Sure, such a patch is often perhaps not perfect and it can usually be improved and expanded as the developers have a different view and a more nuanced understanding of the problem and the software architecture involved. It still helps. Getting 80% towards the target is still valuable.

Versions

Usually you should look for vulnerabilities in the latest version of the software, often even using an up-to-date git repository. Whatever version you used to find it, you need to specify that in your report.

If the problem turns out to be real, which your report claims and you should never report anything if you don’t think so, it is then also immediately interesting to know when this problem first appeared. Which is the earliest version of the software that you can trigger this problem with?

The project will want to know this to write up a proper advisory for the issue. You can help figuring this out by bisecting etc.

Collaborate

Remain available after your initial submission.

In the curl project at least, we want to work with the reporter to make sure we get every angle and detail right. First, when trying to understand and assess the initial report and agreeing on a severity for it.

Then, we jointly produce and agree to a remedy (patch) for the problem, which ideally means taking the reporter’s version and massaging it into perfection.

If the problem is serious enough, there could be reasons to discuss a rushed patch release at an earlier date than the pending release would otherwise happen on. To reduce the time users in the wild remain vulnerable.

Finally, we collaborate on the description and explainer for the problem that goes into the security advisory.

Advisory

For every CVE that is registered and assigned to a particular vulnerability, there needs to be a detailed security advisory written. It should ideally describe the issue, how it triggers, what it means, the impact, the affected version ranges and more. Everything related to the vulnerability that we can think might help users.

Your job as a security researcher is to make sure the description in the advisory matches your finding, your understanding of the problem and that the description is understandable.

Learn

For every confirmed security report, the receiving project will try to learn from it and fix code and practices to avoid making the same mistake again.

As a reporter, your job is to learn from the submission experience and try to improve your reporting procedure and approach for the next time.

Then submit your next report!

Trailing dots are the worst

Trailing dots after hostnames in URLs remain my worst enemies. I wrote about several problems with them in the past that involved those nasty things. They are still painful. When we shipped curl 8.21.0 on June 24 2026 we fixed at least three brand new problems that involved trailing dots. C’mon, follow me down the trailing dot rabbit hole, episode two. I can just feel that there will be a third episode as well in a future…

IPv4 numerical address

Let’s for a second imagine that you create a URL that uses a numerical IPv4 address. Not entirely uncommon. For example lots of people use 127.0.0.1 in local tests etc. Used everywhere since the dawn of time.

Now imagine that you add a trailing dot to this hostname, like “192.168.0.1.”. What does the trailing dot even mean here?

This particular trailing dot caused a problem in curl. To figure out if curl should allow wildcard certificates when connecting to a TLS server, it needs to know if the given hostname is a numerical IP or a hostname. The check uses inet_pton() on the provided hostname extracted from the URL – which incidentally returns false for an IPv4 address that ends with dot! So if it isn’t a numerical address it is a hostname and then we allow wildcards… Argh.

I decided to solve this particular problem like this: if the address is a valid IPv4 address and there is only a single dot afterwards, that dot is “swallowed” as part of the regular IPv4 normalization process that curl always does for IPv4 addresses when parsing URLs. This way, a numerical IPv4 address with a trailing dot will never be passed on to curl internals anymore. And the meaning of the trailing dot for this use case is clear: it is a mistake so we get rid of it. (This also seems to be what browsers do.) Shipping in curl 8.21.0.

This choice has already been reported problematic by at least one user who expected a transfer for a URL like this to return error… I suppose this means that the jury is still out on what the best approach for this trailing dot is.

Double trailing dots HSTS

What could be more fun than trailing dots if not two trailing dots!

Two trailing dots is not possible to use as a hostname when resolving hostnames using DNS. It is an illegal name and causes an error. But as curl provides other ways to populate the DNS cache with a provided name, and you can provide names in /etc/hosts etc you can make curl work with URLs where the hostname has two trailing dots. Or rather, you could up until recently until I made sure it is properly banned always because of the trouble they cause internally.

A double-dot is correctly treated as a host with a trailing dot, but it turns out that in for example the HSTS logic that became problematic as removing the trailing dot for some functions would still have a trailing dot there when there were two of them to begin with… and it would get confused and act up.

No more double trailing dots. One is annoying enough. Shipping in curl 8.21.0.

Cookie domain

HTTP cookies are basically name/value pairs set by the server and held by the client to get sent back to the server again in later communications. The server can specify for which domain a cookie should apply to, so that it can be used across multiple domains. (Yes, it is a little crazy,)

To prevent the server from being able to set the cookie on a too wide domain cookie clients check if the specified domain is Public Suffic Domain (PSL) or not. A server is not allowed to set cookies for PSL domains, as that allows it to create “super cookies” that work across domains in ways that are not allowed. Cookies attempted to get set for such a name should be rejected.

In libcurl we check domains against the PSL using the libpsl library.

Turns out this too could be tricked by trailing dots. If you communicate with the URL “example.co.uk.” (with a trailing dot) and it sets a cookie for for “co.uk.” (with a trailing dot), the internal check would ask libpsl about the PSL status and… it did not work with trailing dots. The exact same process without trailing dots correctly says it is a PSL and the cookie is refused. But with the trailing dots present it was fooled and curl would allow the cookie to get stored and later sent back to such a host…

This particular issue ended up considered a vulnerability known as CVE-2026-8924. Fix shipped in curl 8.21.0.

We should consider these things

Yes, you can of course quite correctly argue that none of these things are actually new or sudden changes. Trailing dots are there, they have always been there and people will continue to use them in the future. I’m not blaming anyone else. I’m just expressing my frustration.

Trailing dots are the worst.

a CVE dispute

A few years years ago the curl project signed up and became a CNA. This means that we are masters of and can allocate our own CVE identifiers. For any security problems within our territory, it is we who decides if the issue should get a CVE or not. No more bogus CVEs.

57 CVEs

During these years we have published fifty-seven separate security vulnerabilities with their associated CVE identifiers. Getting a CVE for an issue is easy and really quickly done when you are a CNA. No hassle, no friction and as we are a small and lean security team it just works as smoothly as you could ask. Just an API call and we have new number.

Being a CNA is low maintenance, as there really is nothing extra we need to do. We already had an established and proven process for receiving, managing and assessing vulnerability reports before we became a CNA since we are a responsible and well-run Open Source project. Becoming a CNA just made the process easier as we now don’t need to involve any outsider at all.

Assess

For every report we work hard to first assess and decide if the issue is actually a vulnerability or a security problem at all.

If we deem that there is a security problem in there, we then grade it into LOW, MEDIUM, HIGH or CRITICAL. Since we don’t know how users use curl or libcurl we cannot take that into account but rather observe and set a severity of the problem from a pure curl point of view.

It’s a rough indication how we see the problem but of course every user that actually are affected by the problem might rate it differently.

Lower than LOW

For a rare few issues we can imagine that there could be a minuscule risk but because of the set of extreme requirements and convoluted steps to get there, we deem the risk so small that in practice no user is likely to ever reach it. Internally we tend to call that an issue with a severity level lower than LOW. Issues we believe we serve humanity better by not issuing a CVE for. To avoid the security dance when it seems unnecessary.

The cost of a CVE

libcurl is installed in somewhere around thirty billion instances on the globe. If we imagine that at least a sizeable portion of those installs are managed by people who want to make sure they use a secure version, it means that every CVE we publish trigger activities in many security teams all over the world, leading to a significant number of patches and subsequent software updates.

Every CVE thus has this huge cost tied to it. A cost that does not land on us and we don’t really see or feel it, but a cost on the ecosystem I believe we should not ignore. We should act responsibly. Never ignore real problems of course, but also to make sure we don’t ring the alarm for theoretical problems that will not trigger any vulnerability.

The dispute

Our first ever CVE dispute since we became a CNA reached us on February 10th, 2026 for a report submitted to us two months earlier. The reporter thinks we should have assigned their reported problem a CVE but we think not. Now they want to force the issue to get a CVE anyway, by escalating the situation to MITRE.

Yes, it makes you wonder why it is that important to have this as a CVE, but I will avoid speculations for now.

I replied to MITRE explaining that we considered and debated the issue and we remain happy with our previous decision. I linked them the original report and discussion to show them.

Hostname with a leading dot

The issue is quite technical (of course) but is based on a bug in curl’s function that checks if the used hostname matches a wildcard provided in a certificate.

First: the user must use a hostname in a URL with a leading dot, like https://.example.com/

This name is not possible to use with DNS (it is an illegal name there), but you can provide an IP address for it in your /etc/hosts file or similar, but still this condition is already making this issue really niche.

Why would a user ever do this? Well, there could be a redirect to such a host name from a malicious server if the application allows redirects but getting the address for the host is still a challenge and mostly requires a local attacker present add that.

Then: if curl can find an address for the illegal DNS hostname, the site curl connects to, also needs to have a wildcard certificate for the name *.example.com where the tail of the wildcard needs to match the name in the URL.

If curl was built to use an OpenSSL flavor or Schannel for TLS (remember that curl supports many different TLS backends), it then calls the Curl_cert_hostcheck() function to check if the wildcard covers the used hostname.

This function had a bug. The above mention combination then erroneously would return TRUE. A match. When in reality it is not a match according to the spec.

We fixed this problem on December 8, 2025, and we added unit tests for exactly this scenario to make sure that the problem doesn’t come back. For all security issues at severity below HIGH, we fix them asap so that was just our normal procedure. We then continued to discuss if this was worthy of a CVE or not.

Lower than LOW

It should be extremely rare that anyone uses a dot prefixed name, unless you are in an internal and controlled environment where you use something else than DNS for resolving.

It is not possible to trick an application to use a dot prefixed arbitrary name as it will fail to resolve.

The explicitly set, weirdly dot prefixed name, then needs to connect to a host that has a wildcard set for that same name and an attacker manage to run this impostor host and can now serve the application malicious data because curl did not properly reject the connection because of the wildcard mismatch.

A series of highly unlikely conditions that all need to be fulfilled for this to become a vulnerability. A lower than LOW situation. Too unlikely; no CVE.

Again in May

On May 28, we were again contacted by MITRE in the same case, asking again for our rationale for not giving this issue a CVE. We responded with virtually the same wording as before and linking again to the same original Hackerone issue and discussion thread. It’s all public information really.

Again in June

On June 15, we were again contacted by MITRE asking for the reasoning behind our decision to not give a CVE for this issue.

We replied with similar wording again. Linking to the same issue, again.

This seems like a great system.

Verdict

On June 24 we finally got the verdict. It is not considered a security vulnerability.

Hello Yuhao,

Thank you for your participation in the CVE dispute process regarding the reported issue affecting curl through 8.17.0.

The MITRE TL-Root has completed its review of the information provided by all parties involved,
including the materials submitted by you and the response from the responsible CNA. Based on this
review, the MITRE TL-Root has determined that a CVE ID will not be assigned for the reported issue.

CNA Determination (Summary):

"This is a bug, now fixed in the master branch. It is not considered a security vulnerability because of how it requires a local attacker with privileges present to make it so."

After evaluating the available evidence and the CNA’s assessment, the MITRE TL-Root agrees with this determination and considers the matter resolved. As the adjudicating authority in this dispute process, the decision of the MITRE TL-Root represents the final determination for this case.

We appreciate your engagement with the CVE Program and your efforts to responsibly report and coordinate security issues.

Respectfully,

MITRE TL-Root

curl summer of bliss

The curl project will not accept or otherwise handle any vulnerability reports during the month of July 2026. We call it the curl summer of bliss.

curl’s submission form on Hackerone will be paused starting July 1, 2026.

Summer of bliss starts: July 1, 2026. 00:00 CEST

Submissions resume: August 3 2026. 09:00 CEST

The security email address will also be a dead end, as we will not process or otherwise care about security or vulnerability reports sent to us that way either.

Whatever issue you find that you feel a need to report to the curl project during this month has to wait. curl’s Hackerone form opens for submissions again on Monday August 3.

We do not accept vulnerability reports over email in general, and this fact remains during and after our vacation.

Vacation for real

The curl maintainers will use this time of less pressure to take in some extra air and to enjoy the summer. Maybe stroll outside a bit more. Breath. Some of us may spend some of this time to see other places.

We may get some extra time to spend on fixing bugs or working on new code. Fun stuff!

Side-effects

As a direct side-effect of this summer of bliss, to allow us some more time to handle the issues that might have piled up for us in early August, we also push the release date of 8.22.0 two weeks into the future. Now scheduled to happen on September 2, 2026.

Vulnerability rate

As previously mentioned, we have been under a huge pressure for the last four months or so. Now we need some rest. We do not expect this deluge to be over.

GitHub

curl’s issue and pull-request trackers on GitHub remain open and active like normal.

You too?

If you and your Open Source projects also want to participate in the summer of bliss 2026: just do it and let us know! I would of course encourage you to do so. To take care of yourself as a top priority.

The bad guys won’t rest

Probably not. But we will.

But what if there is an emergency

Then we get to read about it in August. Or you get a support contract and we get to read about it earlier.

Contracts excluded

Everyone with a paid support contracts will of course still get full and appropriate service even during this period.

Credits

The ice cream image was made by fotografierende from Pixabay

Discussed

On hacker news.

A human in control

There seems to be a fair amount of people in either extremes in the current AI landscape. At one side we see the “vibe coders” who use agents and allow them to merge code without any person even looking at the source, while on the other side of the field there are people who are against everything and anything even remotely associated with AI.

My personal stance is somewhere in between, as I suppose shouldn’t be too surprising to readers of this blog.

A work of love and pride

The core team behind curl, and that is more people than just me, consists of individuals to whom code quality and source code excellence is important. We do software development because it is a craft we love and we are proud of what we have accomplished this far. We do not hand over our responsibilities to any machines. We stand for every bit of code we merge – as humans.

AIs do mistakes

Blindly accepting code written by AI means that you merge a certain amount of errors, but this is certainly true for human written code as well, so this is not in itself special. Some data suggests that AI generated code might even contain more mistakes than the human versions.

We invented test cases and code review a long time ago as a means to help us combat and reduce mistakes to get merged. The particular way code was written does not take away the benefits from code review and getting additional checks and eyes on pending changes. A good code review helps spotting mistakes, omissions or slip-ups. It also helps reinforce the architecture and established design choices. This is true however the code was created.

This far, code reviews done by automatic AI bots and the likes have not yet managed to replace the humans. They are simply not good enough.

Human reviews are much better. They catch other things and they help make sure proposed changes stay on track.

Not to mention how I want to know how curl works, even if I don’t keep 100% intimate knowledge of every single angle and corner, I know most of it. I think it helps me make better decisions, debug better, help users better and keep the architecture sound.

Getting the initial code written is not the big deal. For curl, maintaining and polishing the landed code through decades is the real task.

Everything we merge in curl is determined fine and fitting by humans.

Humans do mistakes

In all living software projects we get bugs reported and we fix them. We do new releases and continue to iterate. We have done this since software was invented and we still do, as humans are quite fallible and easily make mistakes.

We try to reduce the error density and frequency by adding tests and by adding more human eyes on the code before we green-light it. It helps, but is not perfect.

To help us do better code we invent, introduce and enforce a wide variety of different tools. With tools that look at code and identify problems in the early stages, they help avoid landing bad code in the first place. They make us do better code. They reduce the bug frequency.

Some of the best tools for detecting coding mistakes today use AI. These tools might work on existing source code in a git repository or they might look at proposed changes in pull-requests.

Above I mentioned that human code reviews are better; but the opposite is also true. In a somewhat complicated change request, it is now common that after the humans can’t spot any more problems, the AI PR review bots can still find an issue or two to remark on. Sure, sometimes they are wrong and then the comment is easily dismissed, but more often than not the findings they point out are actually something worth addressing before merge.

curl is developed and driven by humans, assisted by tools.

Communication is for humans

Open Source is about sharing code and is a development model where we do things in the open. The communication part of this model is key. Share your ideas, your visions, your problems or maybe just your ideas for what to do this afternoon.

Express what you want or what the problem is, and the team can respond and we can work together on fixing and improving whatever needs to be done.

Effective communication, a condition for good Open Source, implies human-to-human interaction. Inserting a large AI generated tone-deaf large wall-of-text into such a flow can still work, but only in the same way humans can learn to work with difficult individuals as well. It is not ideal and it is not a smooth way of working. It introduces sand in the machine. Don’t do that. It is rude.

Effective Open Source work means we communicate as humans, even if parts of the work and the code is made with the help of AI.

The combination

Humans and machines excel at different things. We can complement each other in software development.

Everyone is free to act to their own will, but in the curl project we don’t hand over responsibility to machines. We stand for our product. We make it as good as we possibly can; using all the tools that are available to us. I claim that in order to do this, humans need to remain in control.