the 277th release 4 changes 42 days (total: 10,929) 281 bugfixes (total: 14,770) 476 commits (total: 40,084) 0 new public libcurl function (total: 100) 0 new curl_easy_setopt() option (total: 312) 0 new curl command line option (total: 278) 84 contributors, 58 new (total: 3,844) 45 authors, 28 new (total: 1,546) 24 security fixes (total: 239)
Security
This time we announce no less than twenty-four fixed vulnerabilities. So many that I decided to not list them individually here. Go check them on the curl security page.
Changes
The symbol formerly known as CURL_GLOBAL_WIN32 is now deprecated in favor of the more accurately named CURL_GLOBAL_WINSOCK. Used with the curl_global_init function.
SMB(S) support is gone. Neither curl nor libcurl support these protocols anymore.
The tool’s –no-clobber option got two improvements: 1) it now inserts the number into the file name as “-[number]” before the file extension if there is an extension. 2) It now tries many more numbers before giving up. Up to 9999.
Bugfixes
Over two hundred and sixty bugfixes landed in this release. Check them out in the 8.23.0 changelog.
Back in August I mentioned the new curl performance tests we have running. I figured it could be apt to return to this topic just to mention some of the initial outcomes.
When the team gets a new set of charts, graphs and plots that visualize something, like performance, they offer an excellent opportunity for us to try to make them look better. This new setup is no exception.
The performance tests have only been running for just a little over two months but they have already made us improve curl performance in several areas. Of course, for most transfers these changes won’t make many visible differences to users. This is more in the vein that every little bit counts and that nothing should run slower than it has to.
This is a list of some improvements that are included in the curl 8.23.0 release, to be shipped tomorrow on October 14.
faster base64 encoding and decoding
With a few different changes, the internal base64 encoding function is more than twice as fast, while base64 decoding is 40% faster.
faster URL encoding and decoding
Meaning percent encoding the octets that are not safe to use in URLs. The decoding function now runs more than twice as fast compare to before, while the encoding function is around four times as fast.
faster date parsing
Converting a date provided in plain ASCII text, as is used in for example cookie headers, to the epoch – number of seconds since Jan 1st 1970, is now more than twice as fast as before. Mostly thanks to completely replaced functions for week day, month name and time zone name lookups.
faster URL parsing
Parsing a full URL to split it up into separate components as well as confirming its validity is a core component of curl, and libcurl exposes this functionality in its API.
In a test with several hundred different URLs, the new version executes 20-30% faster than before – with an improved ability to return precisely what the problem was when the URL is considered invalid.
faster printf() calls
For portability and now historical reasons, libcurl has its own printf() implementation. This ensures that it always works identically on all platforms but it also makes it our job to make sure it executes as fast as possible.
Most printf() calls now run slightly faster (5-15%) because it handles “chunks” instead of single byte-by-byte at a time.
faster number parsing
We have a generic internal function in curl that converts a number provided in ascii to its binary version (for decimal, hexadecimal and octal). It handles 64 bit values, has overflow detection and supports a maximum. This parser now runs almost twice as fast as before thanks to a simple trick to avoid the boundary check for most loops.
smaller structs
The easy handle was 4256 bytes large two months ago, it is now 3064 bytes. About 28% trimmed off. One of these structs is allocated for every concurrent transfer done with libcurl.
There is also one multi handle allocated for each set of transfer. This struct shrunk from 900 bytes to 656: 27%.
The connectdata struct that is allocated once per connection libcurl handles, went down from 824 to 656 bytes: slightly over 20%.
fewer and smaller allocations
For the test case where we count all allocations necessary for the curl tool to download a single 512MB file over clear text HTTP://, it went down from 100 to 96 used allocations. Not too exciting perhaps but it is now really hard to squeeze this further!
Mostly thanks to the decreased struct sizes mentioned above, this use case of a single HTTP download now only use 126,875 bytes allocated at peak. Down from 130,622 bytes two months ago. Also quite difficult to trim further.
It should be noted that the download buffer is 102,400 bytes of this amount. If we exclude that buffer from the count, curl is using 15% less memory.
Easy to check
If you think you can speed up any of these functions, it is now very easy to check: the tests are there in the git repository, ready to be invoked by anyone!
The curl security team happens to also double as the curl core team. The small group of people who assess security reports and take project decisions.
The exact set of participants in this team of course vary over time, as this is a volunteer membership role without monetary compensation.
I decided to write this blog post to help show the light on some of my fellow curl maintainers. I think I often get too much credit and that curl is frequently called a one man show. It really is not and it has not been exclusively my project for many years. We are a team behind this.
As of October 2026 we are six humans in this team. Me and five fellow maintainers. curl would not have been close to what it is today without this team. These are the peeps I turn to first for everything hard, complicated or tough in the curl project when they need to be done in private first. In all other cases, public communication is preferred.
The team
(alphabetical order, excluding myself)
Max Dymond. Max made his first commit in the source repository over nine years ago. He has otherwise made perhaps the biggest impact with his fierce work on the curl fuzzers and dealing with fall-outs from OSS-Fuzz. Having excellent fuzzing significantly contributes to us writing better code.
Stefan Eissing. Having authored his first curl commit just five years ago, Stefan currently has his name on more lines of code when doing git blame on production code than any other individual, including myself. Introduced the pytest test suite in curl. Master of all things HTTP. Productive like few.
Dan Fandrich. Made his first recorded curl commit twenty-two years ago. He has been involved with everything and everywhere in curl. In recent years perhaps most emphasized in test infrastructure as he made the test suite run parallelized a few years ago. He also wrote and admins Test Clutch, which helps us monitor CI test results.
James Fuller. Has been involved with curl for more than eight years. James focuses on security and is our own master of CVE reservations. Primary maintainer of curl-container – images for Docker and others.
Viktor Szakats. Having authored his first curl commit twelve years ago he is now the second most commit author in the project. Lead maintainer of curl-for-win which creates reproducible, static, curl binaries for Linux, macOS and Windows. Viktor is the unparalleled champion of our build and CI systems but shows up everywhere. Apparently he never sleeps.
Invite-only
This group is invite-only and there is no documented set of requirements. You need a proven and established presence in the project, combined with a excellent knowledge of Open Source, protocols, networking and the curl project itself. Once you do, you might get invited to join. Not everyone accepts the invite when extended, and that is perfectly fine. It’s a lot of mostly thankless work without a paycheck.
The rest
1,545 people have authored at least one commit in curl. A typical year, more than 150 individuals author commits and at least ten people author more than 10 commits each. People come and go over time. Here’s a list of the top-100 authors.
Everything that improves curl is welcome and takes us forward. Even bug reports and mere suggestions on the mailing list can help us figure out things or improve features in ways previously not considered.
More than 3,800 people are named in the THANKS file because they helped us out, one way or another.
curl is a team effort. A giant team.
Steering the herd
Our job in the core team remains to steer the direction, to enforce boundaries, to lead by example (in addition to wade through an avalanche of vulnerability reports). To guide contributors, to review changes and try to make it even easier for more people to contribute.
Keeping top-notch quality while allowing and introducing newcomers.
On October 14 2026 we will ship curl 8.23.0. The next iteration in the never-ending series of version bumps from the curl project.
We always think of the next release as the best version we ever did – and this time is no exception. Decades of collected experiences and meticulous polishing has lead us to this.
Earlier than planned
We decided to shorten the release cycle this time, so that we can release 8.23.0 a few weeks earlier than what we originally planned. We took this decision after we received one particular vulnerability report that highlighted a rather significant flaw.
We will ship a new version with this problem removed, together with twenty-one other albeit less serious security vulnerabilities addressed.
Severity HIGH
In the curl project we only assign one of the four different severity levels on all CVEs we report (LOW, MEDIUM, HIGH or CRITICAL), as we basically don’t believe in CVSS scoring. We have only published two CVEs with severity HIGH since 2021, the most recent one being CVE-2023-38545; that could lead to a heap buffer overflow.
Now we are about to release another one: CVE-2026-92392.
All info will be revealed next week
All details about CVE-2026-92392 will become public in the European morning of October 14, 2026 in synchronization of the release of curl 8.23.0 which of course will have this problem fixed.
We will ship updated Rock-solid curl versions in sync with this.
For the safety and security of curl users everywhere (and frankly, all the infrastructure that uses curl), no details of this flaw will be made public before this date.
We will alert the distros@openwall mailing list and paying curl support customers about this problem (and the associated fix) ahead of time.
I will follow-up with a separate blog post after October 14 to describe this flaw in detail. How it can be triggered, why it isn’t quite the end of the world and what we do in curl to fix this and similar classes of problems.
Exactly twenty-five years ago today. Within all their fancy release presentations and videos there are barely no mentions of curl. In their technical notes page, there is just this short single line with not a lot of explanations:
Ever since then, curl has been an established component, present in every version and every install of macOS done through the decades. When Apple later created iOS, iPadOS, WatchOS etc they also adopted libcurl into their operating systems. Never to provide the API to users, but to empower their own applications and services. (But I have no specific date logged anywhere when that started.)
The first curl version Apple shipped in macOS was curl 7.7.2 which was released in April that same year.
Apple has never used a super recent curl version but they have updated it reasonably well I would say. Sometimes less good.
We are proud to have been a part of the Internet evolution all this time. We are happy that Apple, even if merely implied, has validated us and our way of doing things.
We have never worked with Apple, never received sponsorship by Apple, not had them as customers and except a few rare and mostly failed attempts there have never been any communication between us. We ship a freely available Open Source product that they use and bundle in their products. (It is their choice and right.)
This afternoon I had a meeting with IT people at a huge US power infrastructure company. They had found a libcurl.dll file in their C:\Windows\System32 directory and asked us for help to upgrade it. Their vulnerability scanner identified it as vulnerable to several publicly known vulnerabilities. Can we bump it to the latest version please?
No. We really cannot.
There are literally thousands of Windows applications that use libcurl. Many of them install a libcurl.dll file in your file system as part of their installation process and yes, some of them even put it in the system32 directory. They can optionally link with libcurl statically, which allows them to use the library and its API without using an external file. There are pros and cons with either method.
When libcurl is shipped as a separate DLL file, it is easily checked by for example vulnerability scanners and they may find that your Windows installation contains a libcurl version that contains known vulnerabilities. The system may even contain many separate libcurl installations, each potentially at different versions and containing a different set of vulnerabilities.
Not part of Windows
Microsoft ships curl as a bundled part of Windows since many years back, but they build with a static libcurl so they never ship any libcurl.dll file and therefore we know that the file does not originate from there. It is not part of the Windows installation. Something else installs it.
We can’t fix those
Whoever built that exact libcurl.dll file needs to be the one who updates it. It is next to impossible for anyone else to know or figure out exactly how that file was built – and getting it wrong will most certainly crash the application or cause other odd and unpredictable behavior.
Figure out who uses it
My advice: figure out which application that uses this DLL. With tasklist you can check which currently running application that uses a specific DLL, and I have been told there are tools that can scan executable files to find out which ones that use a specific DLL.
This is not something we can do.
We can still help
We can help application makers with advice, education and tricks on how to build curl the best and most effective way. We can even build or ship curl for them. We are leading experts on curl, networks and transfers.
How fast is “fast” and is it good enough? Does it run as fast now as it did before or was there a regression? What exactly needs to be fast? How fast is it?
These are questions that many projects and products face, and in curl we are no different. Yet, performance testing and comparisons are hard and full of landmines and time-wasting efforts. For many years we have occasionally brought up the idea of a performance test suite for curl only to shut it down again because the challenges seemed hard and no one was volunteering to do this.
This week it changed.
Let’s do this
I started out trying to find existing projects that host performance results for Open Source projects so that we could just feed our results something else and get great visualizations and data management. I did not find any such.
I then took a look at what existing tools there are for this purpose, and most pointers seemed to suggest that Grafana is a popular and maybe even a good solution to build something like this with. But man, that is a complicated machine and it felt more than a little overwhelming just figure out where or how to start with it. I decided to postpone that take as well.
Let me do this
I decided that instead of trying to do this the best and optimal way – I shouldn’t let perfect be the enemy of good – I would start out by doing the things I know how to do and take it as far as I can one step at a time. Something should be better than nothing.
Performance testing needs decently stable system conditions so that repeated runs produce reasonably similar results, when all involved factors remain identical. This is basically impossibly to accomplish using most cloud infrastructure since those are almost always shared with countless other users. At least on the cheap and free tiers we use.
We probably need our own dedicated hardware for this, but instead of trying to figure out where to get that and arrange for that, I would start by running performance tests on my own local development machine. I am a single user on this and it has many cores and runs decently fast. It should be good enough to get this going on.
I created a first shell script that updates the curl source code from git, it configures and builds it. Then it runs a bunch of tests, outputs a bunch of data and logs all the output in a single log file. I started out with a few simple tests. How fast does curl download a 100 GB file from localhost, how many allocations and how big allocations does it need for a single HTTP download?
My second script parses all the test log files from the previous builds and generates summaries and graphs for them. To make it possible for humans to see how the performance changes between builds and ideally to automatically detect when something changes more than what should be tolerated.
As I am a graph addict already since before, and that journey has taught me a little gnuplot, I decided that even while there probably are much better tools and fancy JavaScript things that could be used, I don’t know them and learning them now is an endeavor I rather avoid. So I stick to what I know and can get results with quickly.
A third script is invoked from a crontab every twenty minutes, sets up some variables and invokes the runner script.
Once the basics started to work, I showed my curl friends the early versions and I soon created a new git repository for the code.
It’s live baby
After a little more poking, I soon made my locally produced performance test summary get packaged and automatically transferred to the curl website after each build, and voila, the first public curl performance tests were live and public.
Getting this data available immediate triggered curl developers. It only took hours until we had the first proposed changes to improve some numbers, and soon we had a few merges to that affect. Visibility really helps!
The performance numbers we get are still varying to a certain degree, partially of course because I still use my machine for my daily development things, but also because most of them do real (localhost) networking and that is by its nature a little… varying.
The system builds and runs a new round every twenty minutes and it does that using the latest commits from git. This setup makes it sometimes run many rounds on the same commit and it might also mean that it sometimes updates and get several new commits at once, so it might skip a round for some commits. I might reconsider this design later, but since it is still a twenty minute time window, the number of commits is still limited.
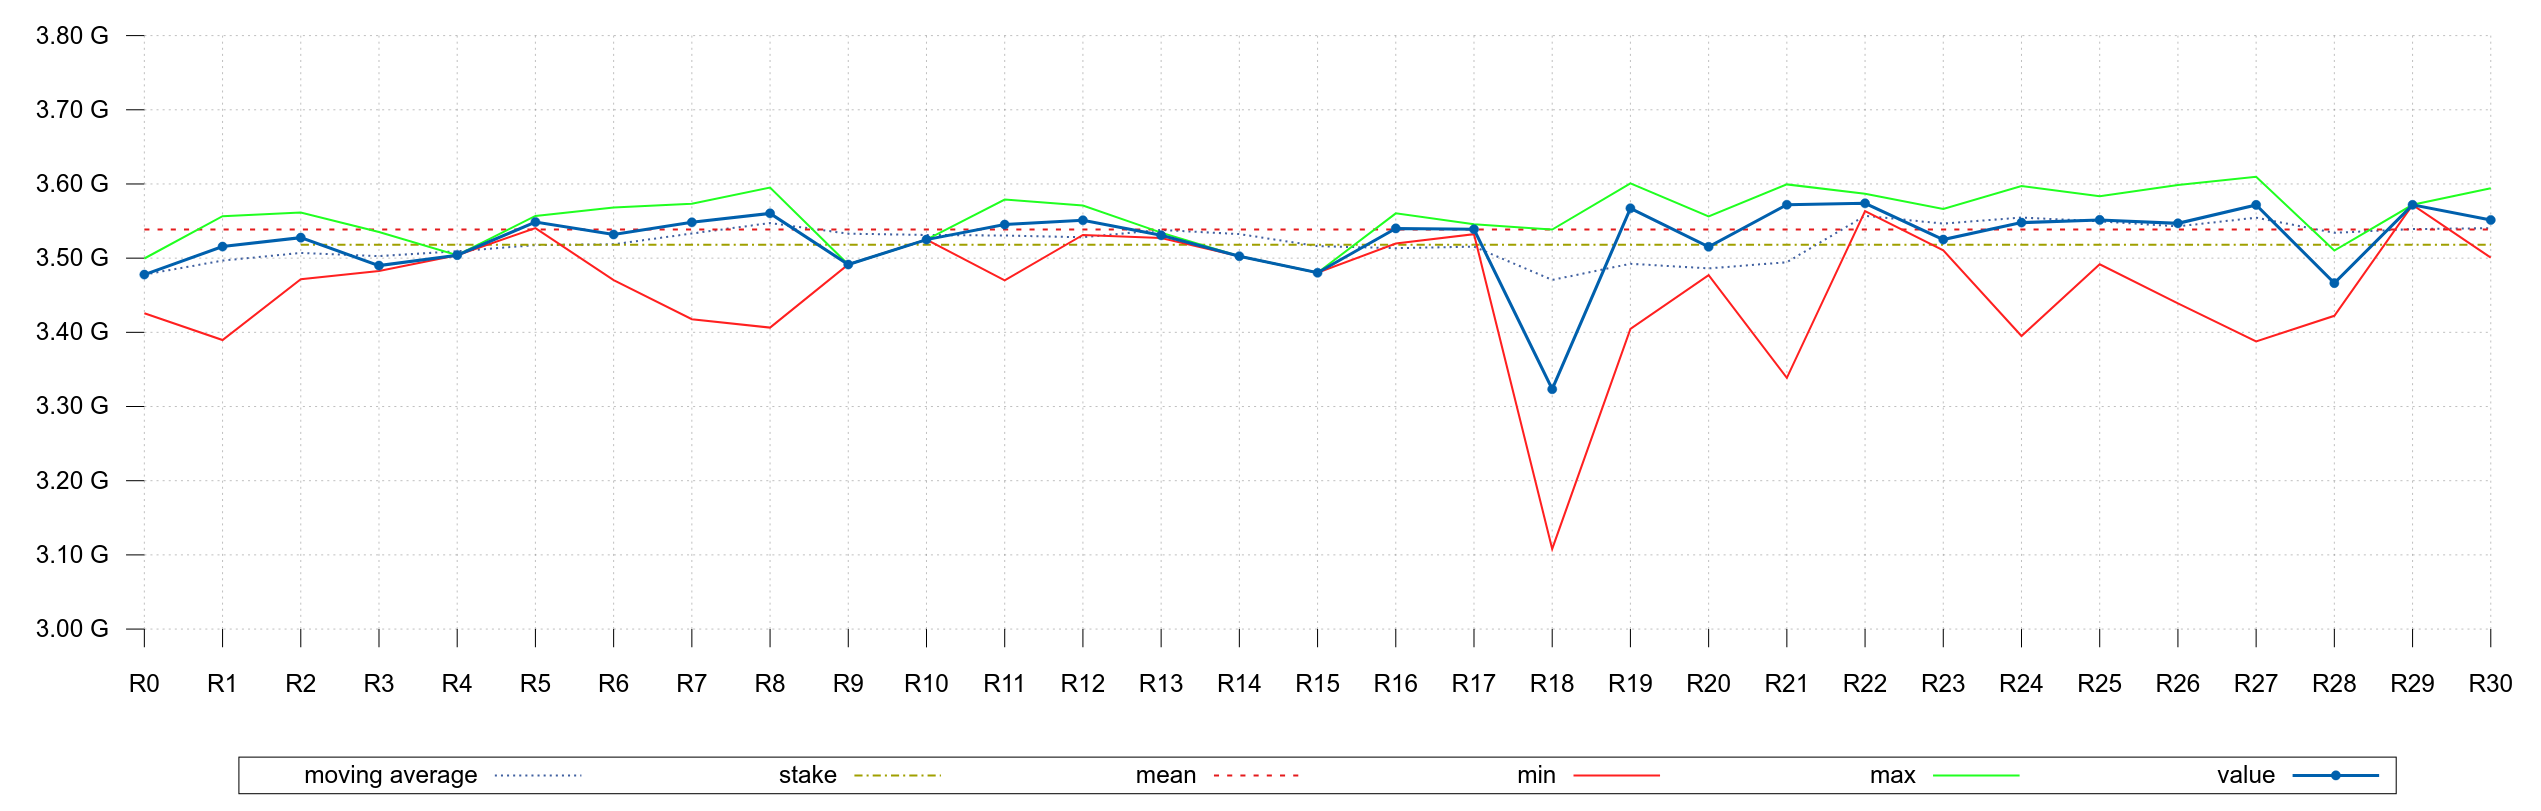
When the script makes multiple build rounds on the same commit, it accumulates the numbers and for the graph it stores the maximum, the median and the minimum value. It helps show the variation per commit and allows us to cram more into the graphs. It is still early days, but there will be a maximum limit to how many commits that can be displayed in a single graph and still be helpful.
HTTP/2 parallel download speed through 261 builds spread over 31 build rounds
Distribution
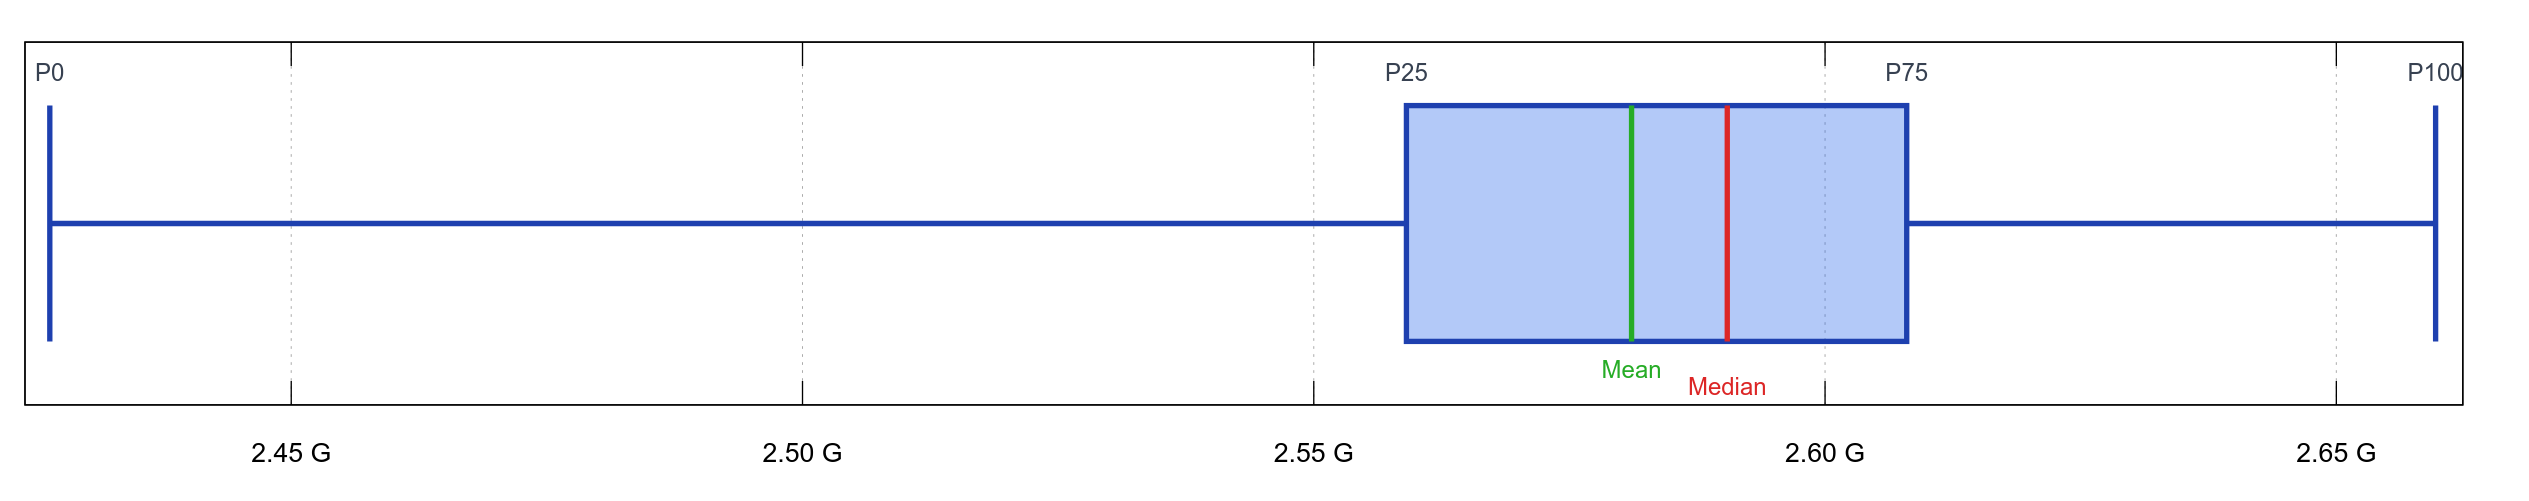
To help visualize the distribution and data spread per test, I created a separate illustration that shows the minimum, maximum, P25, P75, medium and mean values in a Box-and-Whisker Plot.
A Box-and-Whisker Plot showing the HTTP/2 parallel download speed data distribution.
Changing conditions
An obvious downside with me just storing build logs in files, is that it will not scale up to the millions. I did however decide that I’m not designing this system for that. At least not now.
Performance tests are highly specific and dependent on the exact machine it runs on, the exact third party libraries and their versions that are used, the other components involved in the tests, such as the servers, and more.
I expect that we will change conditions for the tests every once in a while that makes it hard to compare the current numbers with past numbers. Therefore I think the performance test numbers and values are primarily useful in the short term. To help us spot if we land something that subtly and unintentionally degrades something.
Stakes
To detect extremely slow and long-term changes in performance and even making sure we can better survive wiping all the existing build logs etc, I introduced a concept I call stakes. As in a stake pole. A marker. An arbitrary threshold set manually for each specific test. This value can be used to measure performance test results against, now and later. As conditions change and maybe something makes the results go up or down and we are fine with those changes because they are motivated and expected, then we just change the stakes.
If it works out, I might try to have the system automatically detect and maybe highlight tests that deviate too much from its set stake (at least if done in the wrong direction) . It could be a signal that something bad was merged.
Balances
As with everything in life, things are often balanced out. We already ran into this when we eagerly merged several changes to reduce the number of allocations done for a single HTTP download, only to realize that one of the optimizations we did had the side-effect that it expanded the size one of the main structs maybe a little too much…
Improvements in one area might come at an expense in another. With sufficient tests and data we can improve curl for users, and at the same time make sure that our changes don’t come with a cost we are not prepared to pay. Exactly how to make the balance is of course a question we need to deal with, discuss and decide. Possibly for every change we do!
The tests
As I write this, we have 24 tests and a full test round completes in about six minutes on my machine.
We can of course do multiple builds using different hardware, different operating systems, different build options, different third party libraries and different test servers to check more angles of performance, and I am certainly open for and prepared to do that going forward. I will however first let this single-flavor run for a while so that we get more data, get a change to tweak it and make it as usable as possible for curl developers.
As with everything there is no end to what we can make this do. This is a start. I sure we can take it further as we move along. In particular if people join in and help out. Both with ideas and proposals for visualizations, graphs and new tests to add, but also with actual pull-requests and code.
Build volumes and graphs
Over the last year, we have merged, on average, about 10 commits per day. If we keep this pace up and this performance test setup can show 100 build rounds conveniently into a single graph, that is just ten days of development. Probably not enough.
Once we reach one hundred builds or so in the first graphs I need to consider adding separate long term graphs that use select data-points to display data development over a longer time. Some googling told me the Largest-Triangle-Three-Buckets, or LTTB for short, is a fine algorithm to use for this. I now do a separate “long term” graph that “downsamples” the full range down to something that can be shown in a reasonable way. I suppose we will see properly in the future how this works.
Spotting change
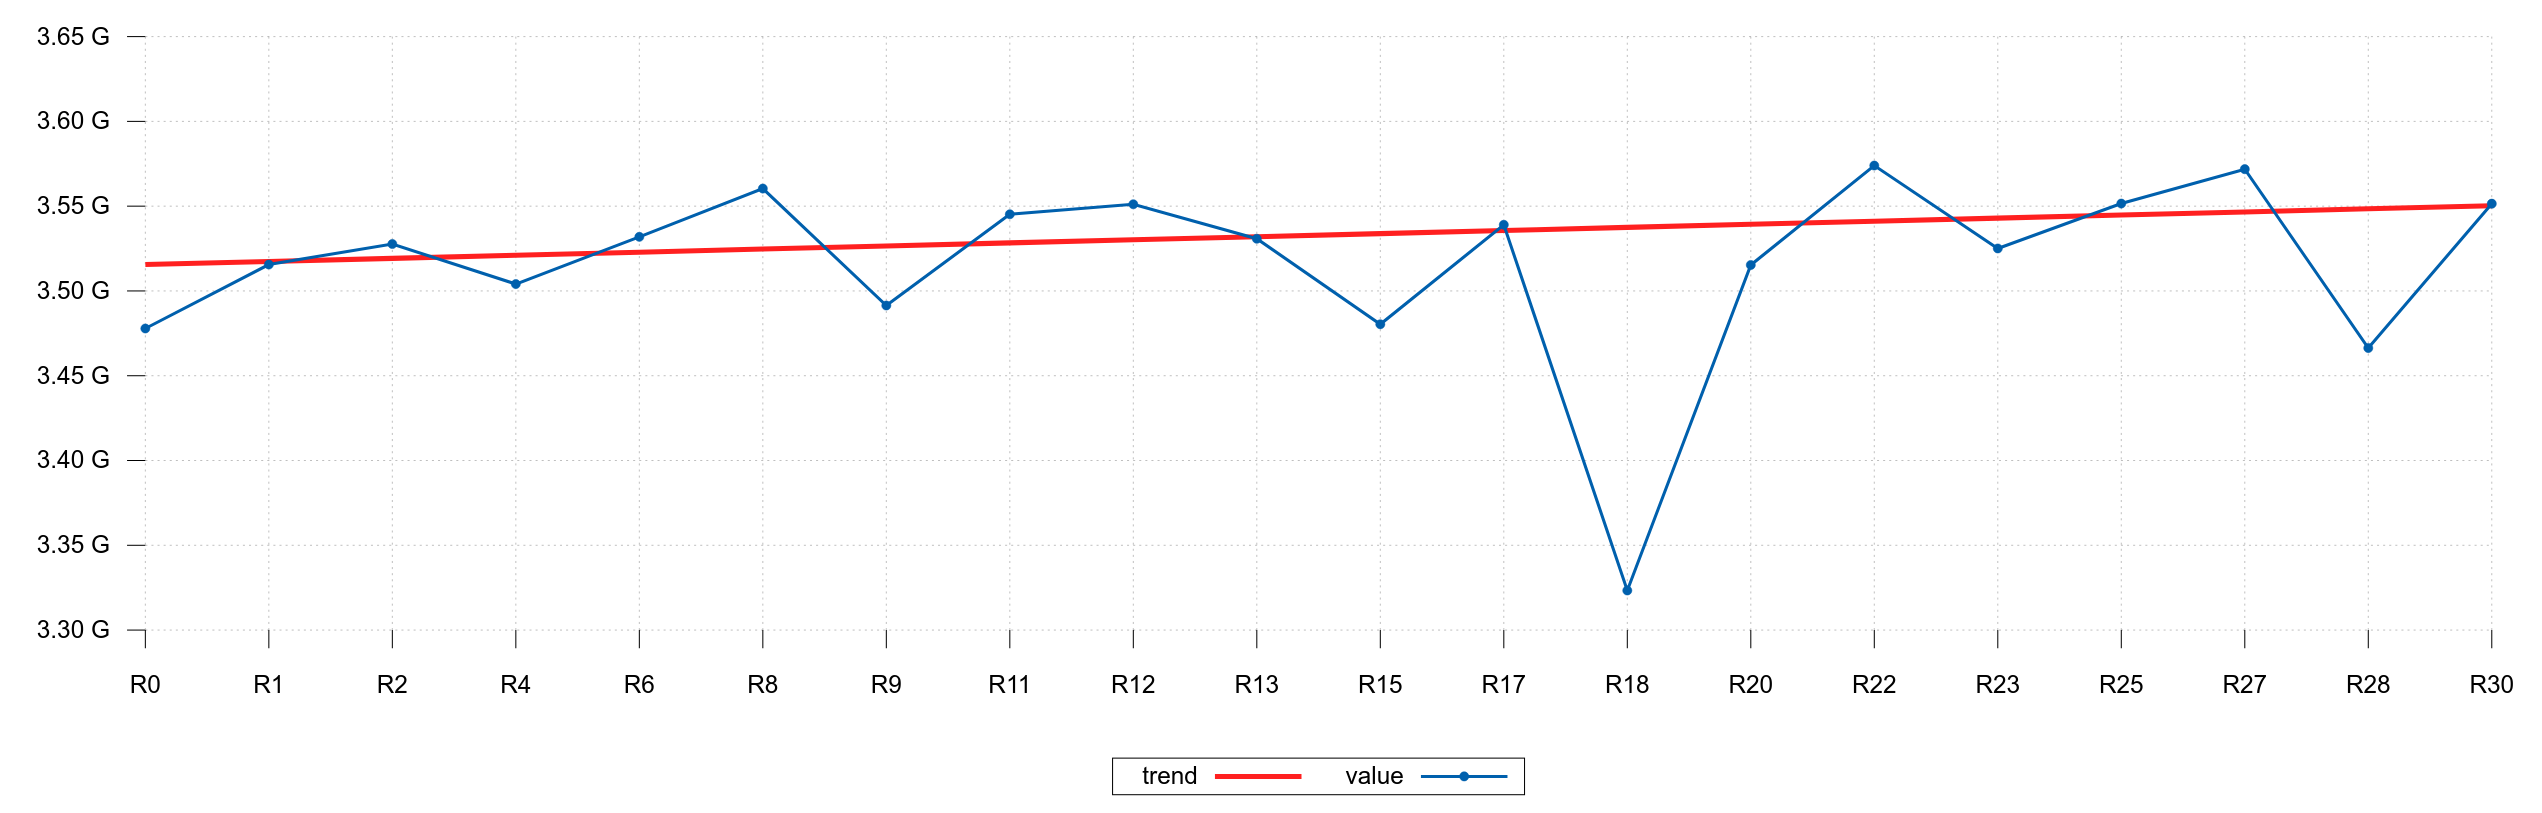
The stake thing I mentioned is one way to help us spot gradual performance changes over time. Another googling told me that there’s a Mann-Kendall Test + Sen’s Slope algorithm to use to identify trends in graphs like this and it can be used to plot a trend. It might work as a helper to better identify… yeah, the data trend for each test.
The HTTP/2 parallel download speed trend at a specific moment
Developing
This setup has only existed for a few days. There is lots to do, lots to learn and much more to experiment with.
Your comments, help and pull-requests will be appreciated!
We (the maintainers of curl) took the entire month of July off from vulnerability reporting and in this post I will try to explain how this went.
(If you feel like skipping the wordy blab below, the single word answer is: fine)
This was possibly our best project decision in a long while.
Zero vulnerability reports
Already before this, we have been refusing to answer emails about vulnerabilities. Partly because we can’t keep track of them that way but even more so because it makes it much harder to properly disclose and publish the entire report sequence after the fact.
On our Hackerone page we informed visitors that we were on pause and that they could come back in August.
We had I believe one vulnerability report sent to my private email address in this period in spite of that messaging, but for all intents and purposes this worked out exactly as good as we hoped it would. I just ignored that email. That was easy.
Bliss
The effect was almost immediate. Just a few days into the bliss, my fellow curl maintainers all agreed with me that we felt a sense of relief, of vacation and that a load had been taken off our chests. We felt free, unchained, and now suddenly able to do what we wanted.
We could now spend time reviewing some of the queued up pull-requests for features and changes we like. We could suddenly again work on code in areas we had been leaving behind lately as vulnerability reports sucked all the air out the room. We polished details on the website, we found document gaps to tighten. It felt like the good old days again. The fun days. We got reminded why we do Open Source and how fun it is.
We took time off, saw some other corners of the world and enjoyed some time away from the keyboards.
We truly healed and re-energized.
CNA
Before we took off on the bliss, we were informed in clear terms that the CNA rules (we are a CNA) mandate that we must respond within 72 hours for some critical vulnerabilities so we can’t just ignore them. I told them sure we can, but in the worst case our “root” could do some emergency assignments. I figured the risk was minimal and it turns out I was right, Nothing like that was needed and no CVE assignments were necessary during the bliss.
Customers
I got a curious question or two from existing support customers on how the bliss would affect them, but that was easy: it did not affect them. Now, post-bliss, I think they all can confirm that it really did not.
New customers?
As I promised to keep up the contact with and support for paying customers even during the bliss, you could possibly imagine that this would have been an incentive for worried commercial curl users out there to sign up for support contracts.
This did not happen – at all. By this I think we should conclude that (commercial) curl users were not worried either.
The outside world
Lots of fellow open source maintainers and most people in my surrounding have been super positive and downright supportive of our taking some time off. I can’t recall having receiving a single negative comment about the curl summer of bliss!
Fellow blissers
I was moved to see that several other Open Source projects followed our example and also took some time off in order to recharge and relax. In addition to giving us a little vacation, it helps sending a signal and a reminder that Open Source is to a large extent done voluntarily and even maintainers need a break at times.
Major incidents?
Have we opened ourselves up for dangerous attacks and flaws now? Have the bad guys an edge on all curl users out there now because we lived in bliss for a month? We don’t know yet, but it would surprise me.
Queues
During this slow-down, we slowly got more open issues and pull-requests lingering on GitHub than usual. No surprise there. Once we started to come back to life again, we have since managed to return them back to the normal amounts.
Flood gates
Yes, there is an obvious risk that there are now a whole range of queued up reports that will hit us in a short period time as we open up for vulnerability reports again. Presumably the risk for duplicates among these reports should also be significantly higher than usual. I suppose I need to do an update post in a month or two and let you know what happened.
We always treat vulnerability reports and project security with topmost priority and we will continue to do so. We will simply work with what we have and make sure our users and by extension, the world, are safe.
Since I am a member of a few other (non-curl) security teams that did not have a summer of bliss, I have seen that the flood of vuln reports have not really slowed down so it might depend a lot on the details of each specific project.
Some emails were read
All individual curl maintainers of course handled this gift in their own ways. We did not all just disconnect to sit on a remote beach for the whole time. Some of us did that part of the time, but we mostly enjoyed the lower stress level and the absence of pressure. It was mentally relaxing. So, even if some of us kept up with emails, occasionally responded to issues or even submitted some pull requests of our own, it was still vacation. It was still blissful.
Rebliss?
Will we do another summer/winter of bliss? I think yes. It was simply great, with virtually no downsides for the people involved but instead lots of positiveness. Ideally a reduced workload going further will remove the need for another one, but it is not easy to tell what the future holds.
Just transfers
After all, curl just does transfers. Fast. Reliably. Secure.
The recently published RFC 9421 describes how to do HTTP Message Signatures, and starting just now, curl experimentally supports them.
Message Signatures
The specification describes this as a mechanism for creating, encoding, and verifying digital signatures or message authentication codes over components of an HTTP message. It is a way to verify that selected parts of the HTTP request arrives unmodified and exactly the same as when the request was created by the client.
These days, it is very common that there are layers of proxies, load balancers, front-ends, CDNs, web firewalls and what not in between the client and the ultimate application. With HTTP Message Signatures, there can be assurances that the headers are components of the request end are unaltered.
Command line
This functionality comes with four new command line options to allow users to use its full power:
--httpsig-algo allows the user to specify which algorithm to use, with ed25519 being used by default. The only other algorithm supported right now is hmac-sha256.
--httpsig-key specifies the key to use when signing the request.
--httpsig-keyid is the key identifier, a string that is passed on in the headers.
--httpsig-headers details exactly which parts of the request and which headers that should be signed. If not set, it defaults to signing the method, authority, path and query.
With these four new flags added to the list, curl supports 278 different command line options.
libcurl
The corresponding options of course also exist as options for curl_easy_setopt:
This feature is marked experimental. This means that it need to be explicitly enabled in the build to appear, and that we strongly discourage use of it in production as we reserve the rights to change it before it gets supported for real. We use the experimental phases as a time for people to test it, to tweak it and to learn what we should fix so that we then can support this to the end of time. We do not guarantee any backward compatibility for experimental features.
Please test this feature and tell us how you experienced it! The more tests and more feedback we get, the faster we can get moved out of the experimental phase to have it present for real for everyone.
Ships
This feature is already merged into git and will be part of the pending curl 8.22.0 release. As experimentally supported.
Credits
This feature was graciously brought to us by Sameeh Jubran.