The curl project has decided to alter its vulnerability disclosure program procedure and starting October 26 2026, we insist that all vulnerability reports submitted to us that are deemed to be severity LOW or MEDIUM should instead be submitted as issues in our GitHub repository.
Only vulnerabilities deemed to be HIGH or CRITICAL will be kept private in the HackerOne tracker.
Security researchers in doubt can still submit the issue on HackerOne and we can tell them what severity we deem it to be. Over the last few years, over 90% of all submissions could quickly be assessed to be less than HIGH.
Issues submitted to HackerOne we deem are LOW or MEDIUM will be requested to be resubmitted on GitHub and will be closed as informative on HackerOne (and publicly disclosed).
Avalanche survival tricks
This policy change is entirely triggered by the current avalanche of vulnerability reports that keep pouring in. We see no end to them and we do not anticipate this flood to decrease within the next several months.
We are struggling as a project as all key maintainers feel strained, overloaded and brought to the brink of what we can muster. We must act to survive. This is our next step in a survival strategy. It might not be our last. We aim to not drown.
Public vs private
By opening up the process we allow the whole world to participate. Both in the assessment and understanding of the report and claimed vulnerability, but also in the creating and writing the advisory and figuring out details of when the issues was introduced etc.
Ideally we get better help to make sure the fix is the correct one, that it fixes the problem, and any other related problem that is similar and that it does not miss a related problem sitting next to this.
An obvious recent trend is that the moment we announce a new set of CVEs and their associated fixes, there is an army of AI-using researchers who throw all those at their models and harnesses to find similar mistakes or omissions in the fixes. By taking this process to the public all the way, ideally we get more help to do that scrutiny better before we ship releases.
We recognize that the amount of work needed per received vulnerability report does not shrink by doing them in public, but we think that we might share the burden among more people easier, and we hope that lessons and documentation brought up in these discussions will be easier to spot and learn from.
The open process can also allow distros and other users of curl to keep up with security fixes earlier and better.
The risks
Several people have suggested there is a risk that researchers mistakenly submit severity HIGH issues on GitHub thinking they are LOW or MEDIUM. It is basically unheard of that a researcher would have understated a reported problem so I consider that a low risk scenario. Also: there was already before this a risk that someone would submit a vulnerability report in the public, it is not a new risk.
Handling some vulnerabilities in the public of course makes the immediately available for both good and bad people. This policy will give bad people a slightly longer window of opportunity to exploit weaknesses at the expense of existing curl users. That is unfortunate but we see no way of avoiding this. We limit this practice to less than HIGH for this reason: at least these problems are not terrible.
Severity LOW
We have discussed simply dismissing all severity LOW issues, but within the CVE program there is an appeals process and if we don’t hand out a CVE to an actual vulnerability, then someone else will do it. We thus cannot ignore true vulnerabilities, or they will come back to bite us nonetheless.
We can however resist and refuse silliness and I personally aim to deny and decline more vulnerabilities harder on the basis that they do not actually hurt any users or existing applications.
Crazy combos
A clear trend these days is that many newly reported vulnerabilities are figured out by AI models that create crazy sequences or option combinations that do something unexpected, but the sequence is something that aren’t likely to ever be used in the real world, or the unexpected that happens is something that occurs every time so applications doing this would spot the problem immediately. I.e problems that have almost no risk to actually trigger in the real world. We save no users by insisting on doing the CVE dance for those issues. We only get work for ourselves and a whole world that has to act on them.
Flow control it
There is an almost infinite number of combinations you can use libcurl’s many options, protocol mixes and flexible API to do things that might not be clearly documented and the AIs will continue to try them all and together with the humans driving these checks they are super eager to treat every minor discrepancy as a vulnerability. We can’t continue down this spiraling path with our sanity intact.
We don’t have the bandwidth, manpower or even will to handle a never-ending vulnerability reporting stream at this pace. I believe few software projects can stand this kind of prolonged high volume deluge for extended periods. Something needs to give way.
How to assign severity
We only use these for levels in the curl project: LOW, MEDIUM, HIGH and CRITICAL. Often we refer back to recently managed vulnerabilities to see how we judged them, but we also provide a set of basic guidelines. I’m sure we can also make them better and clearer.
In the curl 8.23.0 release we shipped a fix for one of the worst vulnerabilities in curl in a long time. We grade it severity HIGH. It is known as CVE-2026-92392 with the title HTTP/2 upload Use-After-Free.
This post explains the bug, what the problem can lead to, and something about why it happened and what we have done to make it harder to introduce a problem like this in curl again in the future.
This is a much simplified explanation. Please refer to the original report for all the details and the full reproducible Docker image for all the low-level fun and education you could possibly want. I highly recommend doing that; the report and the reproducible are awesome.
Use-After-Free
It is a use-after-free, which is a classic problem in memory-unsafe programming languages, like C, where we erroneously have a lingering pointer left, pointing to memory that is already freed, and yet we use that pointer and the memory it points to.
This family of errors is especially bad when a malicious actor can affect the content that gets stored into that memory area that is still used even though it was freed. Tricking the program to do something unintended.
HTTP/2 is multiplexed
This problem involves HTTP/2. HTTP/2 is a multiplexed protocol, meaning that it handles multiple logical transfers over the same physical connection. curl needs to keep track of a number of transfers at the same time, and when data arrives or is to be sent off, it needs to keep things apart appropriately.
Handles
For every transfer done using libcurl, the application creates and sets up a dedicated handle. We call it an easy handle. This handle is kept around for as long as the transfer is in progress, and the application can close and free it once the operation is completed. When doing multiple transfers, multiple handles are used.
libcurl also has multi handles, which is a super handle type that holds any amount of easy handles. This handle, and the corresponding multi interface, makes it possible to drive any amount of concurrent transfers. A transfer done with libcurl always has at least one multi handle and one easy handle. (Sometimes the multi handle is hiddenly used under the hood.)
The setup
In order to trigger this problem, we need an application (such as the curl command line tool) to do an upload over HTTP/2 to a server. By default, libcurl negotiates HTTP/2 when a HTTPS:// URLs is used and the server agrees.
When the upload has started, the server pauses the send by zeroing the HTTP/2 window size, returns a piece of the response and then it resets the stream, which shuts down the transfer – but not the connection. curl then correctly pulls down the entire transfer, but it accidentally leaves a lingering pointer to the involved easy handle.
When the application finds out that the transfer completed (with an error), it subsequently frees the easy handle and then, and here comes the problematic part: cleans up the multi handle.
The mistake
At this point, the easy handle was just freed but there is still a reference to that handle. When libcurl shuts down the multi handle, it misunderstands the situation, allocates memory to download data into, finds the still dangling pointer and manages to download data from the server that ends up in the very same memory previously used for the easy handle.
In this process, it sends off a request that leaks internal client details, which includes information about local addresses, which is crucial. Modern operating systems use Address Space Layout Randomization (ASLR), so a server needs this clue in order to generate a good attack payload.
Subsequently, when libcurl deals with this received data (using the handle the dangling pointer points to) in the download buffer, it uses a function pointer that now has been modified by data just downloaded from the server, and then it runs remote code.
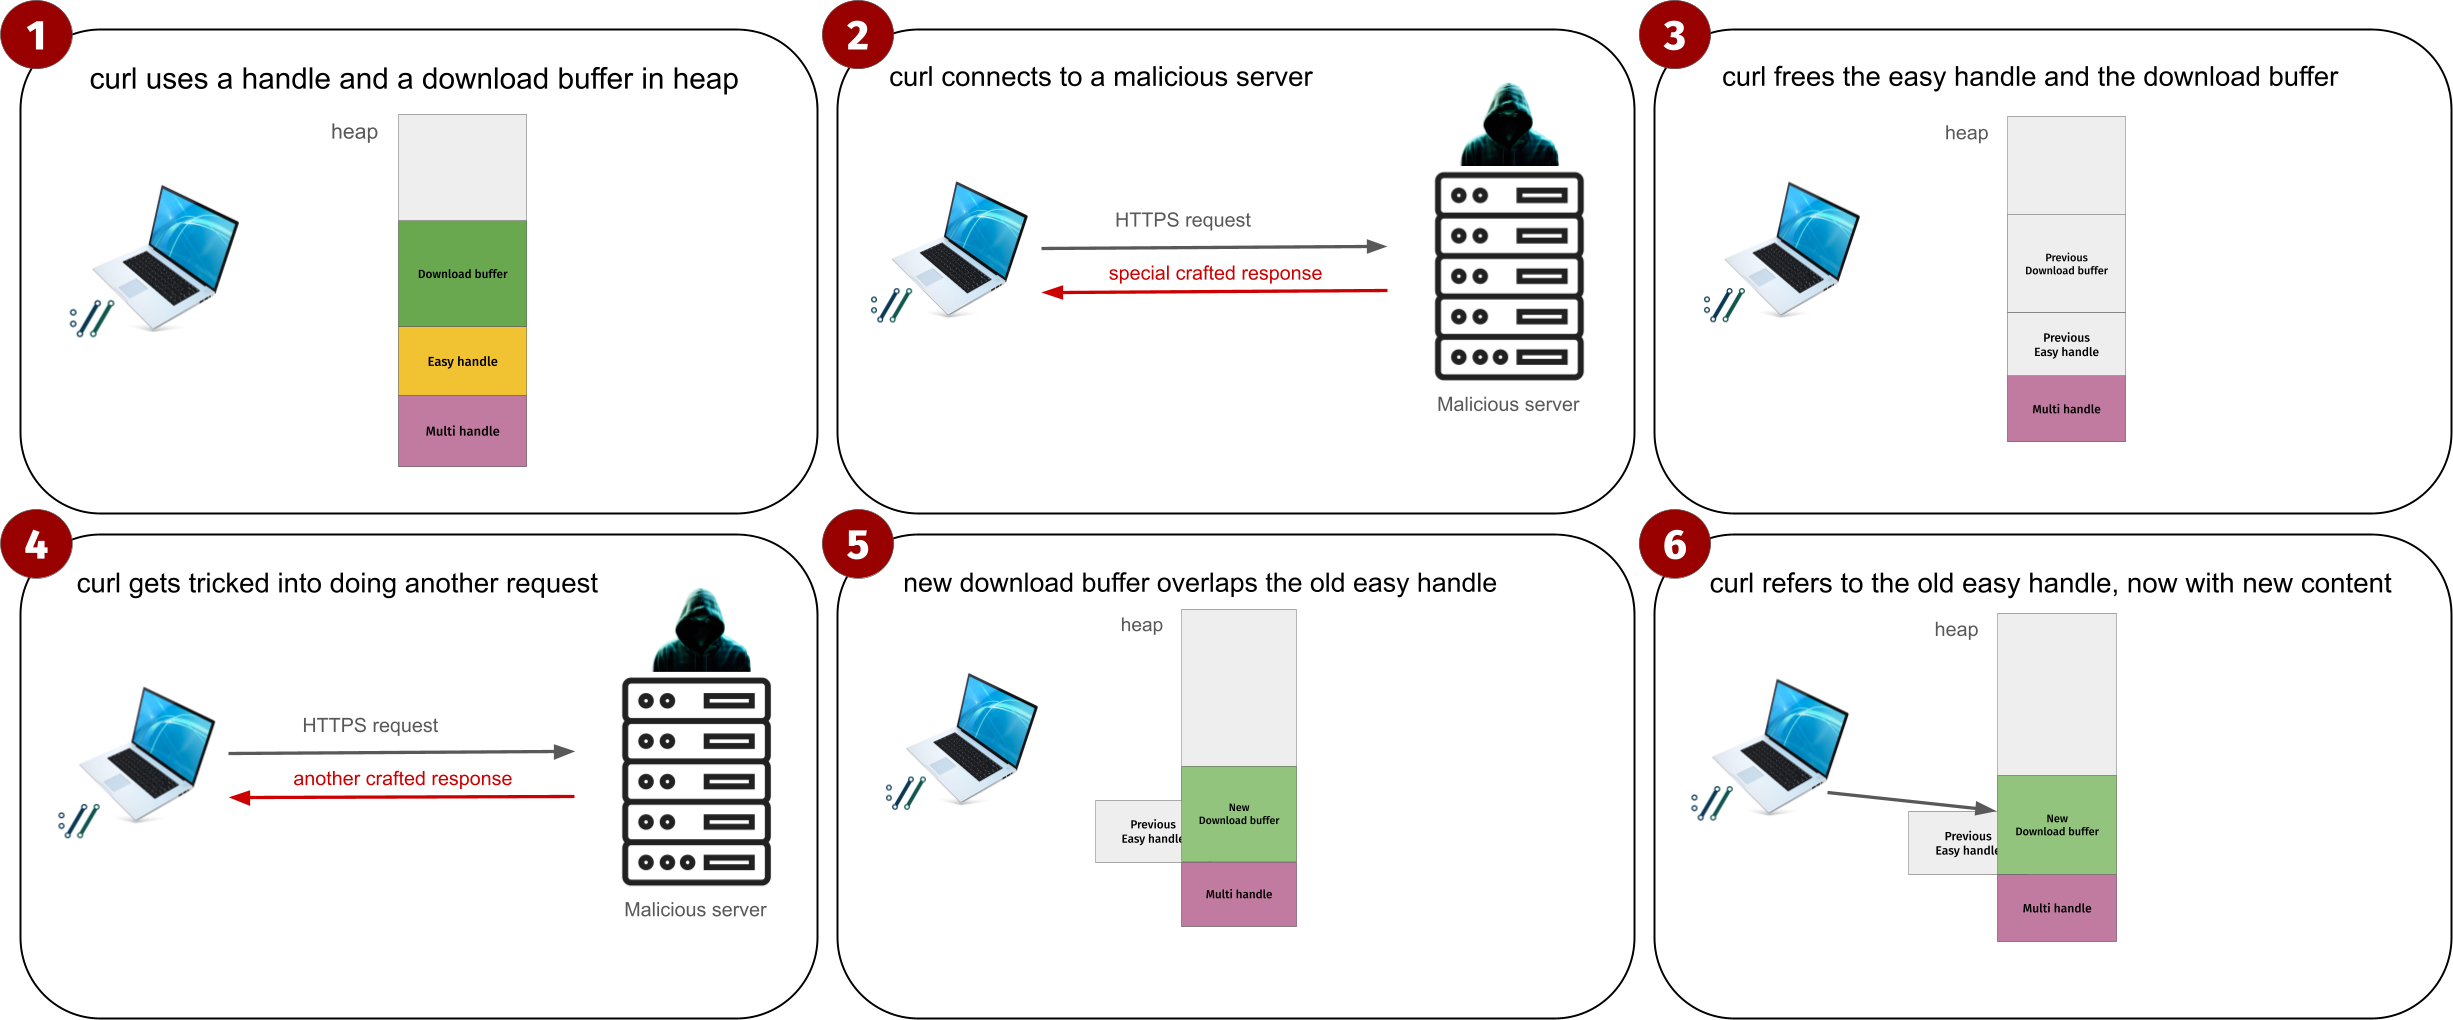
An illustration
Here’s a simplified 6-step illustration.
Conditions to trigger
In order to actually successfully execute remote code, lots of several specific conditions need to be met and we deem it extremely difficult to meet these requirements in the wild, which is why we decided this is “only” severity HIGH and not CRITICAL.
The victim needs to actually attempt to upload data to a malicious server, meaning that the server certificate must remain valid.
The size of the upload needs to be roughly the right size (~135KB)
The attacker needs to know curl’s architecture to generate and deliver the right code
The attack requires a specific sequence of allocations and allocation sizes so that the data from the server ends up in the right place (from the attacker’s view). This pattern differs between Linux distros, libc versions/flavors, TLS certificate bundles, libcurl using applications and more.
nghttp2 and OpenSSL/TLS 1.3 behavior, including allocation effects around session tickets
The payload storage area is small (around 23 bytes)
The most likely outcome of an attempted attack is rather just a crash. We estimate that the chance for a successful attack is slim.
How was this found?
This problem was found and reported by Luna Tong at Anthropic using their new OSS Scanner. Presumably this involves their AI models.
How do we fix this?
In general we have over the last few years been working on reducing the amount of internal pointers to handles that needs to be correct, and instead we store transfer identifiers that we look-up on demand. While this is a tiny bit slower, it is more foolproof when there are logical mistakes like the one mentioned here.
We also of course continue to add more tests and we verify the code with more tools and analyzers in order to find additional similar mistakes.
Multiplexed protocols like HTTP/2 have this challenge that there are many concurrent transfers going and they all have different life-times and with memory-unsafe languages, dangling pointer mistakes can indeed be fatal.
This is of course no guarantee that we do not have or will not introduce another use-after-free in the code now or later.
Again on the language
libcurl is written in C – a memory unsafe language. With a memory-safe language, this mistake could probably have been avoided.
We have worked on curl for almost thirty years, and have over this time manage to make a rather polished transfer engine. For the longest time there really was no memory-safe alternative that also allowed libcurl to be a low-level library available on hundreds of operating systems and several dozen CPU architectures. It even barely exist alternatives now.
We do not rewrite curl. Not into another language but also not in C. We are set to iterate, polish, improve, refactor over and over until the end of time.
Porting curl to another language (like rust) would be a monstrous undertaking that would be slow and introduce lots of new short to medium term problems. Not to mention that the existing curl team is not rust experts and that libcurl is currently portable to many more platforms and environments than rust itself is.
Release schedule
When this vulnerability was confirmed by the curl security team just hours after it was submitted to us on September 15. We immediately realized the significance and decided to rush the pending next release. However, we still wanted to be careful, follow the procedures and not create any further problems or mistakes by stressing it too much. That’s how we ended up just shortening the release cycle with two weeks. Down from eight to six weeks from the previous release. This allowed us to also merge and fix many more vulnerabilities and general bugs in the same release.
CVSS
We never provide CVSS for our published vulnerabilities as we don’t think we can do a job there. Others will provide them even for our flaws.
This afternoon I had a meeting with IT people at a huge US power infrastructure company. They had found a libcurl.dll file in their C:\Windows\System32 directory and asked us for help to upgrade it. Their vulnerability scanner identified it as vulnerable to several publicly known vulnerabilities. Can we bump it to the latest version please?
No. We really cannot.
There are literally thousands of Windows applications that use libcurl. Many of them install a libcurl.dll file in your file system as part of their installation process and yes, some of them even put it in the system32 directory. They can optionally link with libcurl statically, which allows them to use the library and its API without using an external file. There are pros and cons with either method.
When libcurl is shipped as a separate DLL file, it is easily checked by for example vulnerability scanners and they may find that your Windows installation contains a libcurl version that contains known vulnerabilities. The system may even contain many separate libcurl installations, each potentially at different versions and containing a different set of vulnerabilities.
Not part of Windows
Microsoft ships curl as a bundled part of Windows since many years back, but they build with a static libcurl so they never ship any libcurl.dll file and therefore we know that the file does not originate from there. It is not part of the Windows installation. Something else installs it.
We can’t fix those
Whoever built that exact libcurl.dll file needs to be the one who updates it. It is next to impossible for anyone else to know or figure out exactly how that file was built – and getting it wrong will most certainly crash the application or cause other odd and unpredictable behavior.
Figure out who uses it
My advice: figure out which application that uses this DLL. With tasklist you can check which currently running application that uses a specific DLL, and I have been told there are tools that can scan executable files to find out which ones that use a specific DLL.
This is not something we can do.
We can still help
We can help application makers with advice, education and tricks on how to build curl the best and most effective way. We can even build or ship curl for them. We are leading experts on curl, networks and transfers.
There is only one thing that is better than two days of HTTP workshop, and that is of course three days of HTTP workshop. The final day of this edition of the series started out with us again shuffling around where we parked ourselves around the big table. Except Mr captain of course who once again got to herd us forward through another day from the same seat.
Why MOQ is going to replace HTTP live streaming
MOQ (Media over QUIC transport) is not HTTP, but it uses QUIC so it is at least tangentially interesting and it involves a lot of the same people so this status update still felt welcome and suitable. Compared to existing HTTP based solutions, MOQ is supposed to offer less complexity and lower latency. The moon landing was broadcasted with less latency than current live-streamed TV and maybe MOQ can make us come close to those numbers again. In MOQ clients subscribe to a track that then contains a lot of objects that are delivered. It’s not the request + response approach of HTTP. The fact that this is not HTTP of course brings a lot of questions and well, doubts, and we lingered on various aspects of this topic for quite a while.
Reverse HTTP
My prize for the best slides of the HTTP workshop 2026 goes to [redacted] for the excellent use of potato images in their presentation.
PTTH is HTTP spelled backwards, commonly pronounced as PoTaToH. A client sets up the connection but the actual HTTP request is sent from the server to the client. One of the intended use cases for this, is to allow an origin server to connect to the CDN proxy and then be able to deliver traffic to the world, rather than to have the CDN connect to the origin the way they usually do. Apparently most CDNs already have custom and proprietary solutions for exactly this kind of feature, so maybe doing it in a standard way instead makes sense?
Resumable uploads
The draft explains the new proposed way to continue a previously interrupted upload over HTTP. The upload request gets a Location: header back for the resource being uploaded, and if it gets stopped prematurely, a client can then HEAD that resource, figure out the size and then do a second upload (using the PATCH method) request that tells the server that this transfer should start at offset X.
Exactly how this should be supported in browser’ upload forms seemed a little bit uncertain. For my own sake I can see a challenge to implement this nicely for curl in particular when the upload is using formpost upload (curl’s -F flag) which after all still is a very common way to do uploads on the current web. I’ll return to this topic at a later time when I written an implementation to test…
io_uring vs. multithreaded server runtimes vs HTTP mismatch
io_uring is a Linux asynchronous I/O framework that avoids the overhead of traditional system calls. It uses two shared ring buffers between user space and the kernel, allowing applications to batch I/O operations with zero-copy efficiency.
The feature is disabled by Google in ChromeOS, Android and in production Google servers which certainly holds back some use of it.
io_uring can be helpful to speed up things, but might be complicated to use in existing software architectures and the presentation went into some details on why this is so.
Modern UDP I/O for Firefox in Rust
A walk-through of some of the recent developments and improvements in Firefox’s UDP networking stack. Going from single datagrams to the modern ways to ship large chunks of data offloaded to the kernel to speed things up. Upload throughput in Firefox is up 60-90% over the last 11 releases. Lots of fun graphs and metrics were shown. This work is based on the quinn-udp stack.
Rollout of Happy Eyeballs v3 in Firefox
Happy Eyeballs v3 is coming and Firefox is implementing it. It now takes into account many more data sources than before, including alt-svc and HTTPS-RR and races connections against each other to use the one that connects first. There are some recommended timers in the specification and parts of the discussion was around how maybe the timers could instead be tightened a bit, and maybe the delay between the subsequent attempts could then use an exponential backoff instead sticking to a fixed interval?
(I know I’ll discuss some of these details with my curl hacker friends and see what we should adjust… curl already supports most of the Happy Eyeballs v3 specification.)
Shorter ones
As we approached the end of the day a few shorter topics were ventilated to give us a little more to consider before going home:
Why is there no UTF8 in URIs? “If we would do it again, we would have allowed UTF8 in there” was said by someone who was there in the mid 1990s…
Optimistic DNS is a draft. Use stale DNS cache data while getting the new. Connection remains alive for 120 seconds while DNS data is often not cached for even 30 seconds. No one in the room seemed to hate it. Let’s do this!
The journey to QUERY. One of the primary authors of the RFC took us through what it took to make it happen. It was sixteen years since the most previous registered HTTP method and maybe this was the last one ever?
The end for this time
With this, the seventh HTTP workshop had ended. Again a very fine event. This time graciously sponsored and arranged by Adobe. Thank you everyone!
The general idea is to continue with these events roughly every second year and I support this. The HTTP workshops are definitely one of my favorite events.
Credits
The top image on this post was used in the final presentation and the author told me he is aware of the AI errors in there, “of which there are at least two”.
Caffeinated and ready, we all gathered in the same spacious room as yesterday, but seated in new places as “suggested” by our captain. Some of us even remembered to move over the name tags we wrote yesterday to our new seats.
No time was wasted on introductions today. We dove straight in at the deep end.
How AI is changing how HTTP is implemented.
Is the future of software that we check-in the AI prompts in the git repository and trust it to generate the correct code? Are specifications the new level o
f abstraction for source code? These questions triggered long discussions with a huge mix of opinions and experiences getting shared about how AI is used, should be used and could be used now and in the future.
Observations and Measurements of HTTP/2 During Large-Scale Web Crawls
The Common Crawl spidering upgraded to using HTTP/2 for their scan and as an end result, I believe 61% of the responses used HTTP/2 and the entire round ended a few percent faster than before, which when you traverse a few billion URLs really makes a difference. They apparently use a locally patched version of Apache Nutch for this.
HTTP/1.1 behavior divergence
The HTTP probe project runs a lot of tests on HTTP/1 servers and compares how they behave in a lot of different aspects and then generates these awesome tables. Looks like something for every server implementer team to have a look at and decide what of these red boxes that should rather be converted into green alternatives.
Request smuggling test suite
HTTP Zoll is a newtest suite for intermediaries that tests intermediaries (what we often call proxies) for a large amount of request and response smuggling issues. Some real world problems found were discussed and as this project aims at going Open Source words were expressed on what kind of precautions and checks that maybe should be done first. I hope we get to hear more about this project soon.
Server performance & measurement
The HTTP Arena is another project that does performance and measurements. They test HTTP server frameworks and present the results in various ways on their site.
Increase and evolve HTTP/3 & QUIC
In this presentation, we were presented with different HTTP/3 deployment numbers from different sources and the associated reasoning around why they differ but then more importantly. what can and should be done to increase HTTP/3 usage.
Anti-virus interceptions, enterprise blocks and server-side performance not yet on par with TCP were mentioned as reasons for holding back the numbers.
Reasons for using HTTP/3 include use cases that encourage QUIC adoption: WebTransport, Media over QUIC and MASQUE (HTTP/3 proxies and HTTP/3 proxies over older HTTP proxies).
Using HTTPS-RR for upgrade was promoted, as every alt-svc response that is returned with an ALPN using h3 should perhaps also offer h3 over DNS. Why doesn’t your server announce its h3 support over HTTPS-RR?
QUIC v2 is deployed on an amazing 0.003% of all QUIC v1 domains and there was a discussion why this is so and the common sentiment in the room seemed to be that very few saw a reason for deploying v2 and several expressed a concern that doing so might in fact introduce issues. Someone (you can probably guess who) in the room increased that number a lot by quietly mentioning that haxproxy.org certainly supports it.
QMUX
QUIC multiplexing over bi-directional streams is a proposal on how to do QUIC-style multiplexing over TLS (or anything else really). It has been adopted by the IETF QUIC working group and there was a somewhat extended discussion about what the HTTPbis group should or should not do with it. The biggest interest might be for data center use, but is that then something IETF should bother about? This is not the first time I blog about this, and even if there did not seem to be a strong demand or need for this, it also did not seem to be completely dead. I bet we will hear more about this later.
Multiplexed proxying: challenges in H2 and H3
Doing a TLS terminating MITM proxy has its challenges and we were given some insights and experiences on the challenges of doing HTTP/2 and HTTP/3 to the server.
The browsers refuse to do HTTP/3 when they detect custom CA certs installed, which apparently is mostly because of lots of past bad experiences with anti-virus software that in particular seems to break QUIC and for users it is not obvious where the blame should go. This then makes browsers not do HTTP/3 over any MITM proxy.
Some time was spent on how allowing different clients to the proxy uses a shared h2 connection to the target server is complicated and not used, even though in theory it should be possible. An argument was made that it could even lead to worse performance than when using HTTP/1 but I could not quite follow that reasoning. I’m sure I missed some subtle detail in that explanation.
Making the Web QUICer with Rapid Start
When the afternoon is running late and we have been promised beer and snacks after the final talk, what is better than a hard core technical presentation with lots of graphs and numbers showing how QUIC performance can be improved by tweaking the congestion control algorithm and send more data in the startup phase of a new QUIC connections? This new approach is called Rapid Start and it looks like a promising and yet simple improvement. According to experiments done on real world traffic, the time to last byte was reduced by 14.7% on average. Not bad at all.
Drinks and food
Our meeting sponsor Adobe graciously sponsored drinks and food so we got to linger around for a few extra hours and talk even more HTTP and networking until the personal firmly insistent they needed us to leave the room and we instead continued solving world problems elsewhere. Topics around the table included the famous HTTP/2 spec coin flip, the QUIC spin bit, the SCONE situation for QUIC, the timeline behind the QUERY method and many more great stories.
On this hot summer’s day in Basel, Switzerland, the seventh HTTP workshop started. These events tend to work roughly the same way and the people in the room are also to large extent familiar and known since previous editions. Forty people in a meeting room, where we take turns in doing short talks on HTTP and networking topics, with the following question and discussion session. The rules for the meetings are explicitly Chatham rules, which means that everything I write about the meeting will be sufficiently fuzzy and without many company or personal names. This is not the kind of meeting that can be easily summed up in a short blog post anyway. You really should be here.
Present in the room were representatives from all the world’s most prominent and used HTTP deployments: clients, browsers, CDNs, proxies and servers. I’m happy to say that there were also several first-timers. We like fresh blood.
(If you think I’m being overly brief or vague about specifics in this post; that is partially on purpose but primarily because I’m a lousy note-taker and mostly write this up after a busy day that also may have involved beer.)
After a round of introductions, we started.
Extending REST for State synchronization
REST is a set of constraints, and in this presentation it was argued that it can or maybe even should be extended to do more. A number of recent applications like Mastodon/ActivityPub, Bluesky/AT, Matrix, Nostr, IndieWeb, all currently use HTTP to do state synchronization but they all do it differently in their own unique ways. Can REST and maybe HTTP be adjusted to help this for improved interoperability?
Last-Modified header use over time
Looking at the Common Crawl data and comparing data over time, it was observed that responses use the Last-Modified header field more now than they did in the past, and there were great follow-up speculations on why this is so. Data also shows that a large share of these headers present dates that are almost identical to the time the requests were issued.
How is HTTP used in the world?
With the cc-lint tool, data was gathered on how HTTP is actually used today, proving that there is work to be done: deprecated headers are used, some headers are done wrong, and many are overly big. This indicates that there are well used both servers and clients out there that would benefit from cleanup. It probably also shows that doing HTTP correctly and all the correct headers is far from an easy task.
AI-bots’ use of HTTP
Another presentation showed data, this time from a well-known CDN, on the impact the existing AI scraper bots have on the Internet from their point of view. It showed that roughly half of the requests and half of the bandwidth are spent by scraper bots. A long discussion followed where the numbers were questioned as maybe the numbers look like this because a sufficiently large number of the “bad AI scrapers” appear as regular users to the classifiers. Speculations of different kinds were made.
The Apple HTTP stack two years later
As a follow-up from a presentation from a previous HTTP workshop we got to learn how the journey on developing their new HTTP stack has progressed and several fun adventures and lessons from that were shared with the audience.
Why new HTTP APIs?
A look into new HTTP API development at Apple. Some discussions and lessons learned from creating new APIs for both servers and clients.
Android Networking
We got an excellent walk-through of some details and internals of the Android networking stack. Emphasis was perhaps especially put on ECH and QUIC connection migration, and the final “don’t tell us when your connection closed” led to a long new discussion on how we really should fix the problem: when connection has been left idle for a long time and it is closed by the server, the client (mobile phones) don’t want to be told. This, because getting that RST and more, just wakes up the radio and more on the phone only to tell it to go back to sleep. It was theorized that if we could get rid of this unnecessary battery waste, the accumulated gain across billions of devices would make a serious dent.
Day one world problem solving
Several additional HTTP related problems were of course also subsequently solved as we then wandered into the city for dinner and maybe a beer. Of course yours truly returned back to his hotel room in good time to be able to write up this blog post.
The best part of these workshops might be the (no pun intended) networking and discussions had completely outside of the agenda.
Over the years, we have received, read and handled way over one thousand vulnerability reports filed against curl. We have seen most kinds.
It is time for me to try to help future reporters by providing a short guide on how to submit a truly excellent vulnerability report to an Open Source project.
Researchers
We tend to call everyone who reports a security problem a security researcher, because by the act of the submission itself they fulfill the definition. There are however many different kinds of people who submit reports; from the most rookie youngster with limited experience, to the multi-decade experienced senior in the field.
Most reports submitted to a project like curl come from reporters who never submitted anything to the project before and are completely previously unknown. Many reporters use hacker handles or pseudonyms, so there is not a lot to learn about the person behind the report either. We don’t know the reporters’ age, experience level, employer, sex or on which continent they live. But also: none of those things matter.
When you submit a vulnerability report, consider telling the project how you want to get credited, should they consider your report real.
There is a potentially almost unlimited amount of security researchers that can find problems in a project. The project receiving your report only has a limited small number of overloaded maintainers that take care of the reports. Consider this imbalance. Make your report as easy as possible for the team to manage.
Finding
To us maintainers who receive a steady stream of vulnerability reports, it rarely matters exactly how the problem was detected. Whether you fell over it by accident, you found it by reading every single line of source code or if an AI pointed it out to you, it has little relevance to the security team. The team primarily cares about if the problem is real and if it is, how serious the impact is.
Really?
If the problem is documented, then it likely isn’t a vulnerability. This is a common theme in curl: people report that they can find something strange or peculiar to happen when they do something, only to have one of us point out that the action is either documented to have that side-effect, or the action was done in spite of clear warnings in the documentation.
To make a good vulnerability report, you should make sure you understand what the software is supposed to do – and what the documentation says its limitations and conditions are. A good Open Source project has those things documented.
Where
Figure out where and how to submit your report. If you found several problems, it is considered polite to ask the team how they want to receive the rest. As separate individual submissions or maybe as a curated list. Perhaps paced at a slow rate to avoid overflow.
Never circumvent the submission method suggested by the project. That is impolite.
Consider the initial submitting of the issue to be the first step in a multi-step communication process with the project that will continue for as long as at least one of your reported issues has not been resolved or dismissed. This can be days, weeks or in some cases even months.
Expect responses and follow-up questions. Be prepared to clarify, expand and maybe provide more code and reasoning. Remember that you submit vulnerability reports in order to help and improve the project.
Report
These days people like to create enormously long and detailed reports that have all the details, often explained three times and with several embedded lists using bullet points describing impact and providing more or less good analysis attempts.
Your first paragraph of the report should be a human-written, brief explainer of what the problem is and what badness it leads to. You should be able to explain that in just a few sentences. It is a reality-check, because if you can’t do this, if you don’t understand the flaw enough yourself to write such a paragraph, then you have homework to do. Figure it out, then come back and write the intro paragraph.
Having a quality intro saves a lot of time for the security team receiving your report.
Be aware that the Open Source project you contact may be overloaded, on vacation or seeing your report as yet another duplicate they already saw reported seven times.
Be helpful and respect that you add a load to a small team that probably consists of volunteers working on this in their spare time.
Even if you have used a lot of or just a little AI when finding the issue and writing up the report, you must make sure that you communicate as a human. With your human communication skills.
Reproducer
Your report should contain a reproducer. Ideally a fully contained and stand-alone script or source code that the security team can build and run to see the vulnerability trigger.
A reproducer helps prove to the team that the problem is real or maybe already an accepted risk or behavior. It is also convenient for the developers to first understand and reproduce the issue, and then they can convert the reproducer into a project test case for the pending fix.
Without providing a reproducer in your report, you instead push that work to the receiving end. We still need the reproducer. We still need a test case.
Patch
Provide a patch for the problem.
If you can figure out a way to fix the code to make your finding no longer trigger, that is great information for the security team and such a patch usually helps them understand the issue better and get a speedier result. It reduces the load.
Sure, such a patch is often perhaps not perfect and it can usually be improved and expanded as the developers have a different view and a more nuanced understanding of the problem and the software architecture involved. It still helps. Getting 80% towards the target is still valuable.
Versions
Usually you should look for vulnerabilities in the latest version of the software, often even using an up-to-date git repository. Whatever version you used to find it, you need to specify that in your report.
If the problem turns out to be real, which your report claims and you should never report anything if you don’t think so, it is then also immediately interesting to know when this problem first appeared. Which is the earliest version of the software that you can trigger this problem with?
The project will want to know this to write up a proper advisory for the issue. You can help figuring this out by bisecting etc.
Collaborate
Remain available after your initial submission.
In the curl project at least, we want to work with the reporter to make sure we get every angle and detail right. First, when trying to understand and assess the initial report and agreeing on a severity for it.
Then, we jointly produce and agree to a remedy (patch) for the problem, which ideally means taking the reporter’s version and massaging it into perfection.
If the problem is serious enough, there could be reasons to discuss a rushed patch release at an earlier date than the pending release would otherwise happen on. To reduce the time users in the wild remain vulnerable.
Finally, we collaborate on the description and explainer for the problem that goes into the security advisory.
Advisory
For every CVE that is registered and assigned to a particular vulnerability, there needs to be a detailed security advisory written. It should ideally describe the issue, how it triggers, what it means, the impact, the affected version ranges and more. Everything related to the vulnerability that we can think might help users.
Your job as a security researcher is to make sure the description in the advisory matches your finding, your understanding of the problem and that the description is understandable.
Learn
For every confirmed security report, the receiving project will try to learn from it and fix code and practices to avoid making the same mistake again.
As a reporter, your job is to learn from the submission experience and try to improve your reporting procedure and approach for the next time.
A few years years ago the curl project signed up and became a CNA. This means that we are masters of and can allocate our own CVE identifiers. For any security problems within our territory, it is we who decides if the issue should get a CVE or not. No more bogus CVEs.
57 CVEs
During these years we have published fifty-seven separate security vulnerabilities with their associated CVE identifiers. Getting a CVE for an issue is easy and really quickly done when you are a CNA. No hassle, no friction and as we are a small and lean security team it just works as smoothly as you could ask. Just an API call and we have new number.
Being a CNA is low maintenance, as there really is nothing extra we need to do. We already had an established and proven process for receiving, managing and assessing vulnerability reports before we became a CNA since we are a responsible and well-run Open Source project. Becoming a CNA just made the process easier as we now don’t need to involve any outsider at all.
Assess
For every report we work hard to first assess and decide if the issue is actually a vulnerability or a security problem at all.
If we deem that there is a security problem in there, we then grade it into LOW, MEDIUM, HIGH or CRITICAL. Since we don’t know how users use curl or libcurl we cannot take that into account but rather observe and set a severity of the problem from a pure curl point of view.
It’s a rough indication how we see the problem but of course every user that actually are affected by the problem might rate it differently.
Lower than LOW
For a rare few issues we can imagine that there could be a minuscule risk but because of the set of extreme requirements and convoluted steps to get there, we deem the risk so small that in practice no user is likely to ever reach it. Internally we tend to call that an issue with a severity level lower than LOW. Issues we believe we serve humanity better by not issuing a CVE for. To avoid the security dance when it seems unnecessary.
The cost of a CVE
libcurl is installed in somewhere around thirty billion instances on the globe. If we imagine that at least a sizeable portion of those installs are managed by people who want to make sure they use a secure version, it means that every CVE we publish trigger activities in many security teams all over the world, leading to a significant number of patches and subsequent software updates.
Every CVE thus has this huge cost tied to it. A cost that does not land on us and we don’t really see or feel it, but a cost on the ecosystem I believe we should not ignore. We should act responsibly. Never ignore real problems of course, but also to make sure we don’t ring the alarm for theoretical problems that will not trigger any vulnerability.
The dispute
Our first ever CVE dispute since we became a CNA reached us on February 10th, 2026 for a report submitted to us two months earlier. The reporter thinks we should have assigned their reported problem a CVE but we think not. Now they want to force the issue to get a CVE anyway, by escalating the situation to MITRE.
Yes, it makes you wonder why it is that important to have this as a CVE, but I will avoid speculations for now.
I replied to MITRE explaining that we considered and debated the issue and we remain happy with our previous decision. I linked them the original report and discussion to show them.
Hostname with a leading dot
The issue is quite technical (of course) but is based on a bug in curl’s function that checks if the used hostname matches a wildcard provided in a certificate.
First: the user must use a hostname in a URL with a leading dot, like https://.example.com/
This name is not possible to use with DNS (it is an illegal name there), but you can provide an IP address for it in your /etc/hosts file or similar, but still this condition is already making this issue really niche.
Why would a user ever do this? Well, there could be a redirect to such a host name from a malicious server if the application allows redirects but getting the address for the host is still a challenge and mostly requires a local attacker present add that.
Then: if curl can find an address for the illegal DNS hostname, the site curl connects to, also needs to have a wildcard certificate for the name *.example.com where the tail of the wildcard needs to match the name in the URL.
If curl was built to use an OpenSSL flavor or Schannel for TLS (remember that curl supports many different TLS backends), it then calls the Curl_cert_hostcheck() function to check if the wildcard covers the used hostname.
This function had a bug. The above mention combination then erroneously would return TRUE. A match. When in reality it is not a match according to the spec.
We fixed this problem on December 8, 2025, and we added unit tests for exactly this scenario to make sure that the problem doesn’t come back. For all security issues at severity below HIGH, we fix them asap so that was just our normal procedure. We then continued to discuss if this was worthy of a CVE or not.
Lower than LOW
It should be extremely rare that anyone uses a dot prefixed name, unless you are in an internal and controlled environment where you use something else than DNS for resolving.
It is not possible to trick an application to use a dot prefixed arbitrary name as it will fail to resolve.
The explicitly set, weirdly dot prefixed name, then needs to connect to a host that has a wildcard set for that same name and an attacker manage to run this impostor host and can now serve the application malicious data because curl did not properly reject the connection because of the wildcard mismatch.
A series of highly unlikely conditions that all need to be fulfilled for this to become a vulnerability. A lower than LOW situation. Too unlikely; no CVE.
Again in May
On May 28, we were again contacted by MITRE in the same case, asking again for our rationale for not giving this issue a CVE. We responded with virtually the same wording as before and linking again to the same original Hackerone issue and discussion thread. It’s all public information really.
Again in June
On June 15, we were again contacted by MITRE asking for the reasoning behind our decision to not give a CVE for this issue.
We replied with similar wording again. Linking to the same issue, again.
This seems like a great system.
Verdict
On June 24 we finally got the verdict. It is not considered a security vulnerability.
Hello Yuhao,
Thank you for your participation in the CVE dispute process regarding the reported issue affecting curl through 8.17.0.
The MITRE TL-Root has completed its review of the information provided by all parties involved, including the materials submitted by you and the response from the responsible CNA. Based on this review, the MITRE TL-Root has determined that a CVE ID will not be assigned for the reported issue.
CNA Determination (Summary):
"This is a bug, now fixed in the master branch. It is not considered a security vulnerability because of how it requires a local attacker with privileges present to make it so."
After evaluating the available evidence and the CNA’s assessment, the MITRE TL-Root agrees with this determination and considers the matter resolved. As the adjudicating authority in this dispute process, the decision of the MITRE TL-Root represents the final determination for this case.
We appreciate your engagement with the CVE Program and your efforts to responsibly report and coordinate security issues.
The security email address will also be a dead end, as we will not process or otherwise care about security or vulnerability reports sent to us that way either.
Whatever issue you find that you feel a need to report to the curl project during this month has to wait. curl’s Hackerone form opens for submissions again on Monday August 3.
We do not accept vulnerability reports over email in general, and this fact remains during and after our vacation.
Vacation for real
The curl maintainers will use this time of less pressure to take in some extra air and to enjoy the summer. Maybe stroll outside a bit more. Breath. Some of us may spend some of this time to see other places.
We may get some extra time to spend on fixing bugs or working on new code. Fun stuff!
Side-effects
As a direct side-effect of this summer of bliss, to allow us some more time to handle the issues that might have piled up for us in early August, we also push the release date of 8.22.0 two weeks into the future. Now scheduled to happen on September 2, 2026.
Vulnerability rate
As previously mentioned, we have been under a huge pressure for the last four months or so. Now we need some rest. We do not expect this deluge to be over.
GitHub
curl’s issue and pull-request trackers on GitHub remain open and active like normal.
You too?
If you and your Open Source projects also want to participate in the summer of bliss 2026: just do it and let us know! I would of course encourage you to do so. To take care of yourself as a top priority.
The bad guys won’t rest
Probably not. But we will.
But what if there is an emergency
Then we get to read about it in August. Or you get a support contract and we get to read about it earlier.
Contracts excluded
Everyone with a paid support contracts will of course still get full and appropriate service even during this period.
Back in April 2026 Anthropic caused a lot of media noise when they concluded that their new AI model Mythos is dangerously good at finding security flaws in source code. Apparently Mythos was so good at this that Anthropic would not release this model to the public yet but instead trickle it out to a selected few companies for a while to allow a few good ones(?) to get a head start and fix the most pressing problems first, before the general populace would get their hands on it.
The whole world seemed to lose its marbles. Is this the end of the world as we know it? An amazingly successful marketing stunt for sure.
My (non-) access
Part of the deal with project Glasswingwas that Anthropic also offered access to their latest AI model to “Open Source projects” via Linux Foundation. Linux Foundation let their project Alpha Omega handle this part, and I was contacted by their representatives. As lead developer of curl I was offered access to the magic model and I graciously accepted the offer. Sure, I’d like to see what it can find in curl.
I signed the contract for getting access, but then nothing happened. Weeks went past and I was told there was a hiccup somewhere and access was delayed.
Eventually, I was instead offered that someone else, who has access to the model, could run a scan and analysis on curl for me using Mythos and send me a report. To me, the distinction isn’t that important. It’s not that I would have a lot of time to explore lots of different prompts and doing deep dive adventures anyway. Getting the tool to generate a first proper scan and analysis would be great, whoever did it. I happily accepted this offer.
(I am purposely leaving out the identity of the individual(s) involved in getting the curl analysis done as it is not the point of this blog post.)
AI scans of curl
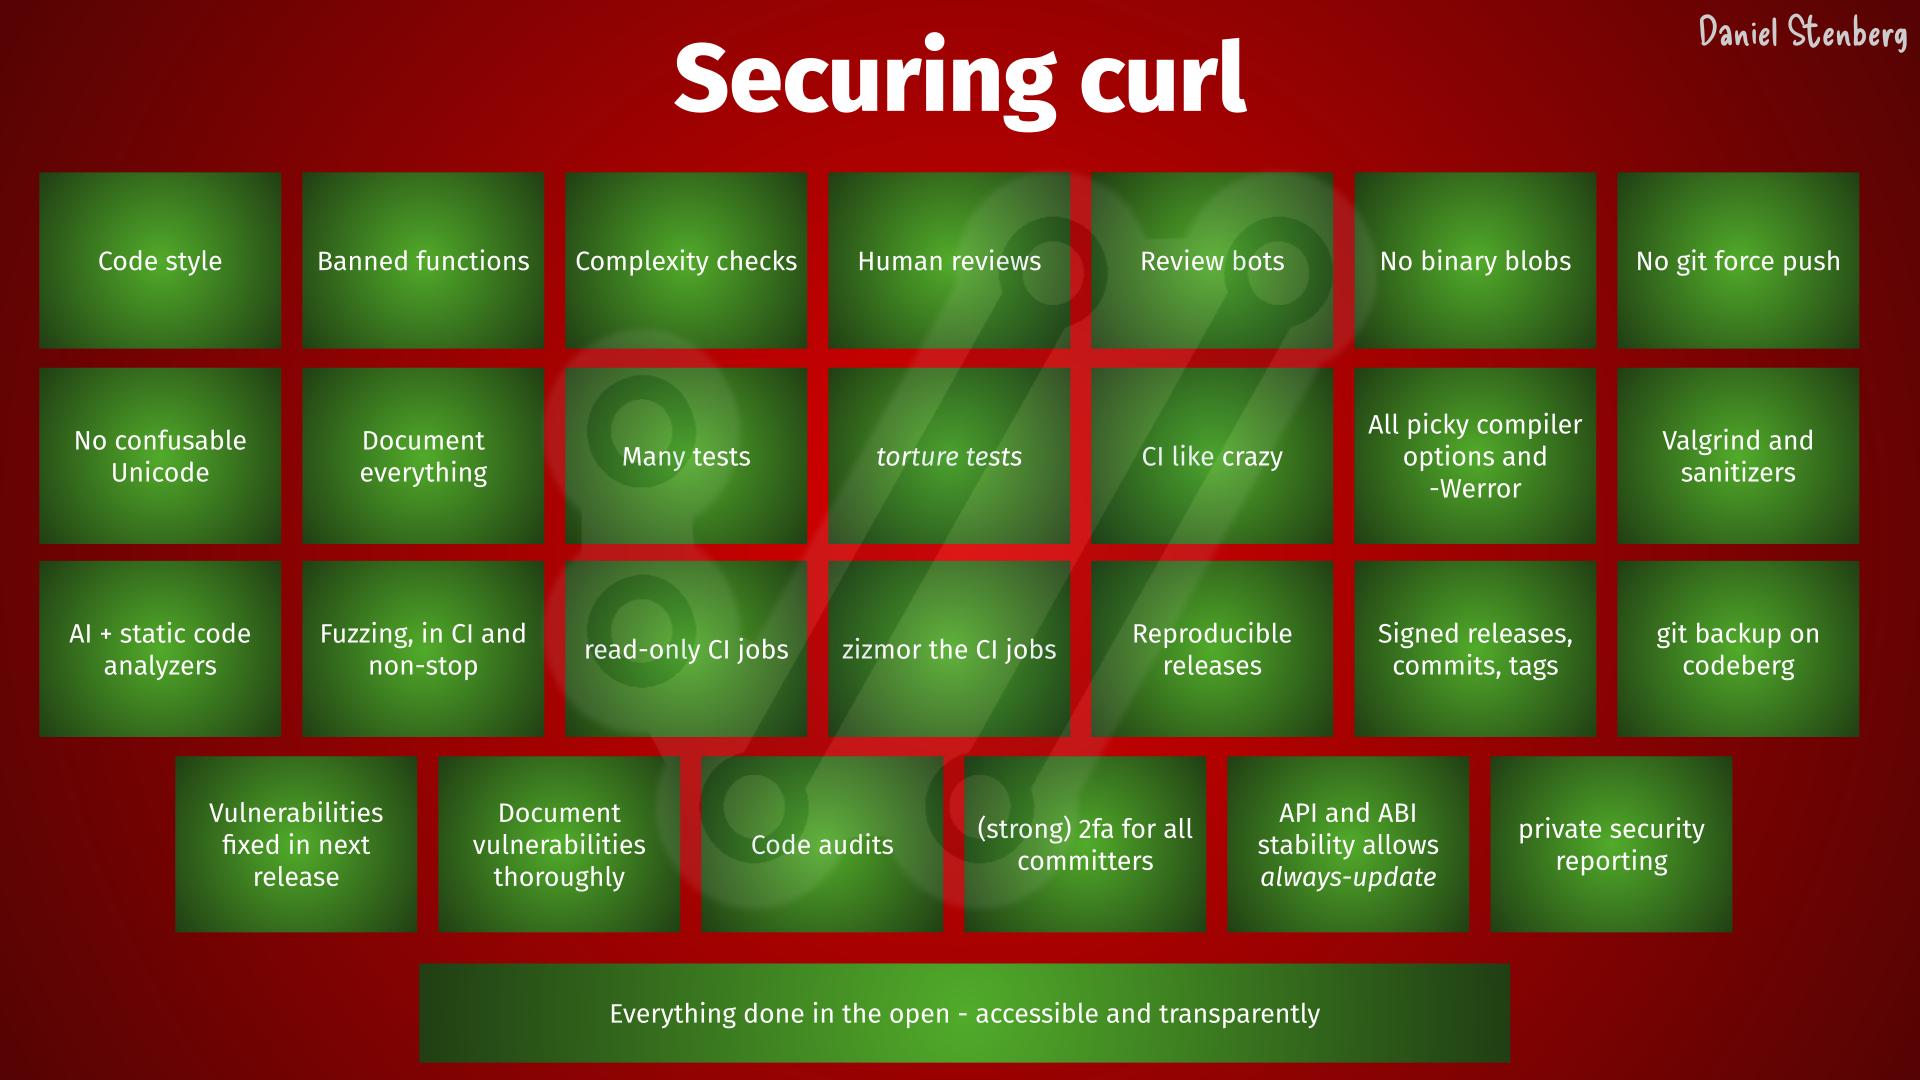
Before this first Mythos report, we had already scanned curl with several different very capable AI powered tools (I mean in addition to running a number of “normal” static code analyzers all the time, using the pickiest compiler options and doing fuzzing on it for years etc). Primarily AISLE, Zeropath and OpenAI’s Codex Security have been used to scrutinize the code with AI. These tools and the analyses they have done have triggered somewhere between two and three hundred bugfixes merged in curl through-out the recent 8-10 months or so. A bunch of the findings these AI tools reported were confirmed vulnerabilities and have been published as CVEs. Probably a dozen or more.
Nowadays we also use tools like GitHub’s Copilot and Augment code to review pull requests, and their remarks and complaints help us to land better code and avoid merging new bugs. I mean, we still merge bugs of course but the PR review bots regularly highlight issues that we fix: our merges would be worse without them. The AI reviews are used in addition to the human reviews. They help us, they don’t replace us.
Security is a toppriority for us in the curl project. We follow every guideline and we do software engineering properly, to reduce the number of flaws in code. Scanning for flaws is just one of many steps to keep this ship safe. You need to search long and hard to find another software project that makes as much or goes further than curl, for software security.
Steps involved in keeping curl secure
May 6, 2026
It was with great anticipation we received the first source code analysis report generated with Mythos. Another chance for us to find areas to improve and bugs to fix. To make an even better curl.
This initial scan was made on curl’s git repository and its master branch of a certain recent commit. It counted 178K lines of code analyzed in the src/ and lib/ subdirectories.
The analysis details several different approaches and methods it has performed the search, and how it has focused on trying to find which flaws. A fun note in the top of the report says:
curl is one of the most fuzzed and audited C codebases in existence (OSS-Fuzz, Coverity, CodeQL, multiple paid audits). Finding anything in the hot paths (HTTP/1, TLS, URL parsing core) is unlikely.
… and it correctly found no problems in those areas.
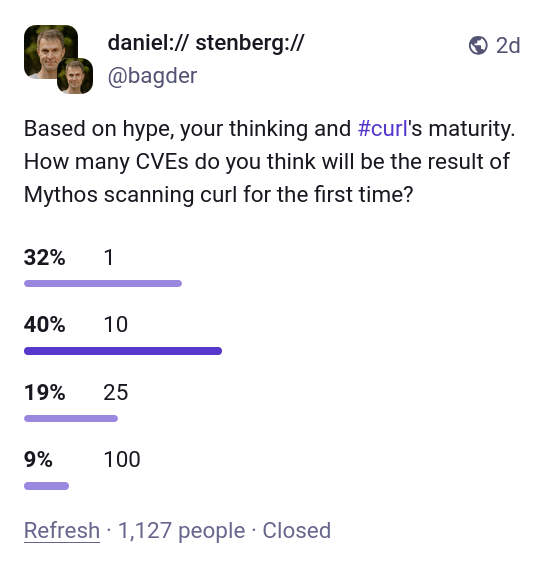
Completely unscientific poll on Mastodon about people’s expectations for Mythos scanning curl
The size of curl
curl is currently 176,000 lines of C code when we exclude blank lines. The source code consists of 660,000 words, which is 12% more words than the entire English edition of the novel War and Peace.
On average, every single production source code line of curl has been written (and then rewritten) 4.14 times. We have polished on this.
Right now, the existing production code in git master that still remains, has been authored by 573 separate individuals. Over time, a total of 1,465 individuals have so far had their proposed changes merged into curl’s git repository.
curl is installed in over twenty billion instances. It runs on over 110 operating systems and 28 CPU architectures. It runs in every smart phone, tablet, car, TV, game console and server on earth.
Five findings became one
The report concluded it found five “Confirmed security vulnerabilities”. I think using the term confirmed is a little amusing when the AI says it confidently by itself. Yes, the AI thinks they are confirmed, but the curl security team has a slightly different take.
Five issues felt like nothing as we had expected an extensive list. Once my curl security team fellows and I had poked on the this short list for a number of hours and dug into the details, we had trimmed the list down and were left with one confirmed vulnerability. The other four were three false positives (they highlighted shortcomings that are documented in API documentation) and the fourth we deemed “just a bug”.
The single confirmed vulnerability is going to end up a severity low CVE planned to get published in sync with our pending next curl release 8.21.0 in late June. The flaw is not going to make anyone grasp for breath. All details of that vulnerability will of course not get public before then, so you need to hold out for details on that.
The Mythos report on curl also contained a number of spotted bugs that it concluded were not vulnerabilities, much like any new code analyzer does when you run it on hundreds of thousands of lines of code. All the bugs in the report are being investigated and one by one we are fixing those that we agree with.
All in all about twenty bugs that are described and explained very nicely. Barely any false positives, so I presume they have had a rather high threshold for certainty.
curl is certainly getting better thanks to this report, but counted by the volume of issues found, all the previous AI tools we have used have resulted in larger bugfix amounts. This is only natural of course since the first tools we ran had many more and easier bugs to find. As we have fixed issues along the way, finding new ones are slowly becoming harder. Additionally, a bug can be small or big so it’s not always fair to just compare numbers
Not particularly “dangerous”
My personal conclusion can however not end up with anything else than that the big hype around this model so far was primarily marketing. I see no evidence that this setup finds issues to any particular higher or more advanced degree than the other tools have done before Mythos. Maybe this model is a little bit better, but even if it is, it is not better to a degree that seems to make a significant dent in code analyzing.
This is just one source code repository and maybe it is much better on other things. I can only tell and comment on what it found here.
Still very good
But allow me to highlight and reiterate what I have said before: AI powered code analyzers are significantly better at finding security flaws and mistakes in source code than any traditional code analyzers did in the past. All modern AI models are good at this now. Anyone with time and some experimental spirits can find security problems now. The high quality chaos is real.
Any project that has not scanned their source code with AI powered tooling will likely find huge number of flaws, bugs and possible vulnerabilities with this new generation of tools. Mythos will, and so will many of the others.
Not using AI code analyzers in your project means that you leave adversaries and attackers time and opportunity to find and exploit the flaws you don’t find.
How AI analyzers differ
They can spot when the comment says something about the code and then conclude that the code does not work as the comment says.
It can check code for platforms and configurations we otherwise cannot run analyzers for
It “knows” details about 3rd party libraries and their APIs so it can detect abuse or bad assumptions.
It “knows” details about protocols curl implements and can question details in the code that seem to violate or contradict protocol specifications
They are typically good at summarizing and explaining the flaw, something which can be rather tedious and difficult with old style analyzers.
They can often generate and offer a patch for its found issue (even if the patch usually is not a 100% fix).
More details from the report
Zero memory-safety vulnerabilities found.
Methodology note: this review is hand-driven analysis using LLM subagents for parallel file reads, with every candidate finding re-verified by direct source inspection in the main session before being recorded. The CVE to variant-hunt mapping was built from curl’s own vuln.json. No automated SAST tooling was used.
This outcome is consistent with curl’s status as one of the most heavily fuzzed and audited C codebases. The defensive infrastructure (capped dynbufs everywhere, curlx_str_number with explicit max on every numeric parse, curlx_memdup0 overflow guard, CURL_PRINTF format-string enforcement, per-protocol response-size caps, pingpong 64KB line cap) systematically closes the bug classes that would normally be productive in a codebase this size.
Coverage now includes: all minor protocols, all file parsers, all TLS backends’ verify paths, http/1/2/3, ftp full depth, mprintf, x509asn1, doh, all auth mechanisms, content encoding, connection reuse, session cache, CLI tool, platform-specific code, and CI/build supply chain.
AI finds existing kinds of errors
It should be noted that the AI tools find the usual and established kind of errors we already know about. It just finds new instances of them.
We have not seen any AI so far report a vulnerability that would somehow be of a novel kind or something totally new. They do not reinvent the field in that way, but they do dig up more issues than any other tools did before.
More to find
These were absolutely not the last bugs to find or report. Just while I was writing the drafts for this blog post we have received more reports from security researchers about suspected problems. The AI tools will improve further and the researchers can find new and different ways to prompt the existing AIs to make them find more.
We have not reached the end of this yet.
I hope we can keep getting more curl scans done with Mythos and other AIs, over and over until they truly stop finding new problems.
Credits
Thanks to Anthropic and Alpha Omega for providing the model, the tools and doing the scan for us. Thanks also to the individual who did the scan for us. Much appreciated!